Reddit API in Go: A Runnable net/http Client for 2026
Call the Reddit API from Go with plain net/http, one bearer token, typed structs, after-cursor pagination, and a concurrent worker pool. No wrapper.
The Reddit API works in Go with nothing but the standard library. net/http sends the request, encoding/json decodes the response, and one Authorization: Bearer header carries your credential. There is no wrapper to install, no OAuth developer app to register, and no client ID to manage. A single bearer token from redditapis.com reads posts, search, comment trees, and user profiles from a typed Go client you can paste into any project.
Not affiliated with Reddit Inc. redditapis.com is an independent third-party REST proxy for Reddit's API.
TL;DR: Go's
net/httpplus one bearer token is a complete Reddit client. Skip the OAuth app flow and the aging wrapper libraries. Decode responses into typed structs, walk listings with theaftercursor, fan out across subreddits with a boundederrgroupworker pool, and retry transient errors withcontextdeadlines. Reads cost $0.0015 per call (pricing).
What you will build:
- A working
GET /api/reddit/postscall from Go in about 15 lines, no wrapper - Typed structs for posts, search, comments, and users with
encoding/json - Cursor pagination across an entire subreddit
- A bounded concurrent worker pool with
golang.org/x/sync/errgroup - A production request layer with retries, timeouts, and
context
Cost: $0.0015 per read call. Free credit at signup. No card required.
Why Go Developers Skip the Reddit Wrapper Libraries
Most Reddit tutorials assume Python or JavaScript, so a Go developer searching for a client hits a thin shelf. The main community package, github.com/vartanbeno/go-reddit, models Reddit's OAuth API faithfully, but it inherits the same access friction the OAuth flow imposes: a registered developer app, a client ID and secret, and a token you refresh. That friction is what people complain about across languages when they reach for a wrapper at all:

Observer of Time
@chronobserver
@feross You wrote an (un)sophisticated, 150 LoC HTTP request wrapper for the Reddit API and want to charge $99 for it? I'd much rather donate that money to https://t.co/SgBYijQYmJ which is entirely FLOSS and has an abstracted, semantic, and functional interface.
Underneath the wrapper question sits an access question. Reddit tightened API access over 2023 and again through 2025, moving commercial use behind a paid tier documented in Reddit's Data API terms, and the developer-app review path on reddit.com/dev/api has been slow and inconsistent. A Go service that needs to keep running does not want a token lifecycle it has to babysit.
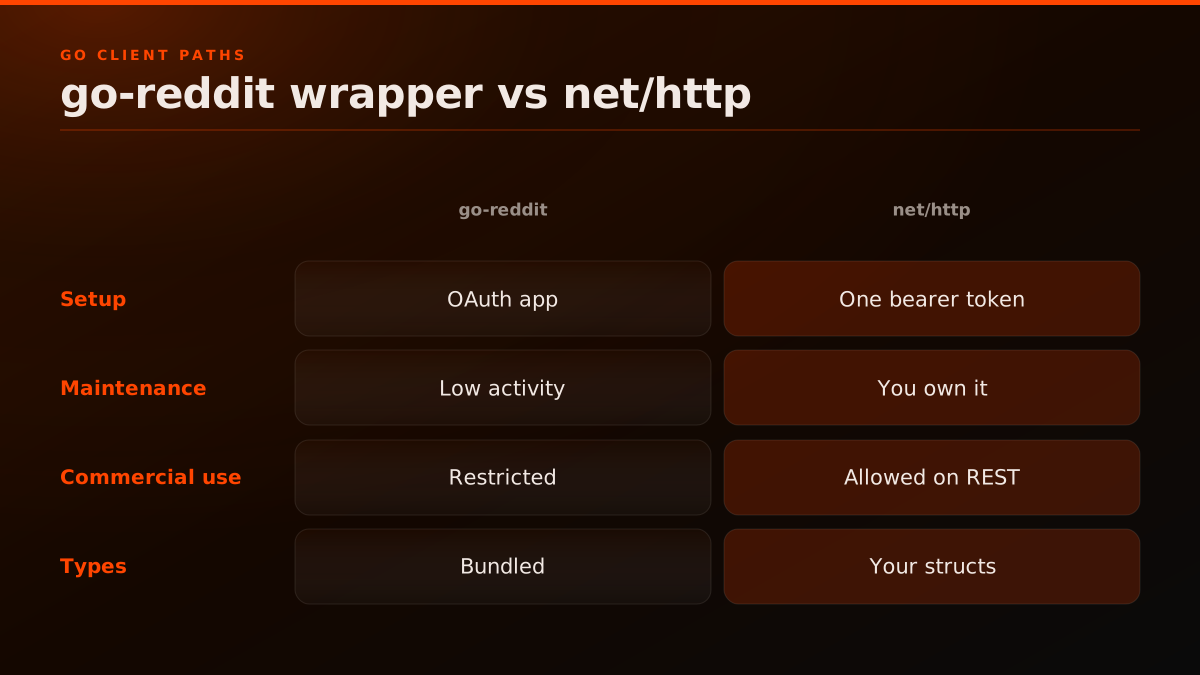
Go is unusually well suited to dropping the wrapper. The standard library ships a production HTTP client, JSON decoding is a struct tag away, and goroutines make concurrency native rather than a bolt-on. Point net/http at a managed REST endpoint that handles the Reddit session internally, and you get reads with one bearer token, structs you control, and nothing to keep patched. This tutorial does what a wrapper would, reads posts, searches, walks comment trees, and fetches users, with the standard library and $0.0015 per read call (pricing). For the JavaScript version of the same idea, see the Node.js and TypeScript tutorial, and for the endpoint map across languages, the Reddit data API overview.
Setup: One Token, One Header
The entire credential story is a single bearer token. Generate one at signup, export it, and every request carries it in one header. There is no client ID, no client secret, no redirect URI, and no refresh loop.
export REDDITAPI_KEY="YOUR_API_KEY"
go version   # confirm Go 1.21 or newer
Keep the key out of source. Read it from the environment with os.Getenv and load it from your platform's secret store in production. Never commit it, and never ship it inside a client binary you distribute, because a bearer token embedded in a shipped executable is readable by anyone who inspects it. If a public tool needs Reddit data, proxy the call through a small server that holds the key. That one rule keeps a distributed Go program safe. For how keys and auth work, see how to get a Reddit API key and the authentication overview.
The base URL is https://api.redditapis.com and the key goes in Authorization: Bearer. There is no token prefix variant and no query-string key. Every call to the API carries this one header, which is what makes the Go client small.
Quick Start: The Reddit API in Go in 15 Lines
First prove the endpoint from the shell so you can see the raw JSON before writing any Go:
curl -s -H "Authorization: Bearer YOUR_API_KEY" \
  "https://api.redditapis.com/api/reddit/posts?subreddit=golang&sort=top&t=week&limit=5"
That returns a { "posts": [...], "after": "..." } object. Now the same call in Go, decoding into a struct:
package main

import (
	"encoding/json"
	"fmt"
	"net/http"
	"os"
)

const base = "https://api.redditapis.com"

type Post struct {
	ID        string `json:"id"`
	Name      string `json:"name"` // fullname, e.g. "t3_abc123"
	Title     string `json:"title"`
	Author    string `json:"author"`
	Subreddit string `json:"subreddit"`
	Permalink string `json:"permalink"`
	Upvotes   int    `json:"upvotes"`
	Comments  int    `json:"comments"`
	CreatedAt float64 `json:"created_utc"`
}

type PostsResponse struct {
	Posts []Post `json:"posts"`
	After string `json:"after"`
}

func main() {
	req, _ := http.NewRequest("GET", base+"/api/reddit/posts?subreddit=golang&sort=top&limit=5", nil)
	req.Header.Set("Authorization", "Bearer "+os.Getenv("REDDITAPI_KEY"))

	res, err := http.DefaultClient.Do(req)
	if err != nil {
		panic(err)
	}
	defer res.Body.Close()

	var data PostsResponse
	json.NewDecoder(res.Body).Decode(&data)
	for _, p := range data.Posts {
		fmt.Printf("%d up  %s\n", p.Upvotes, p.Title)
	}
}
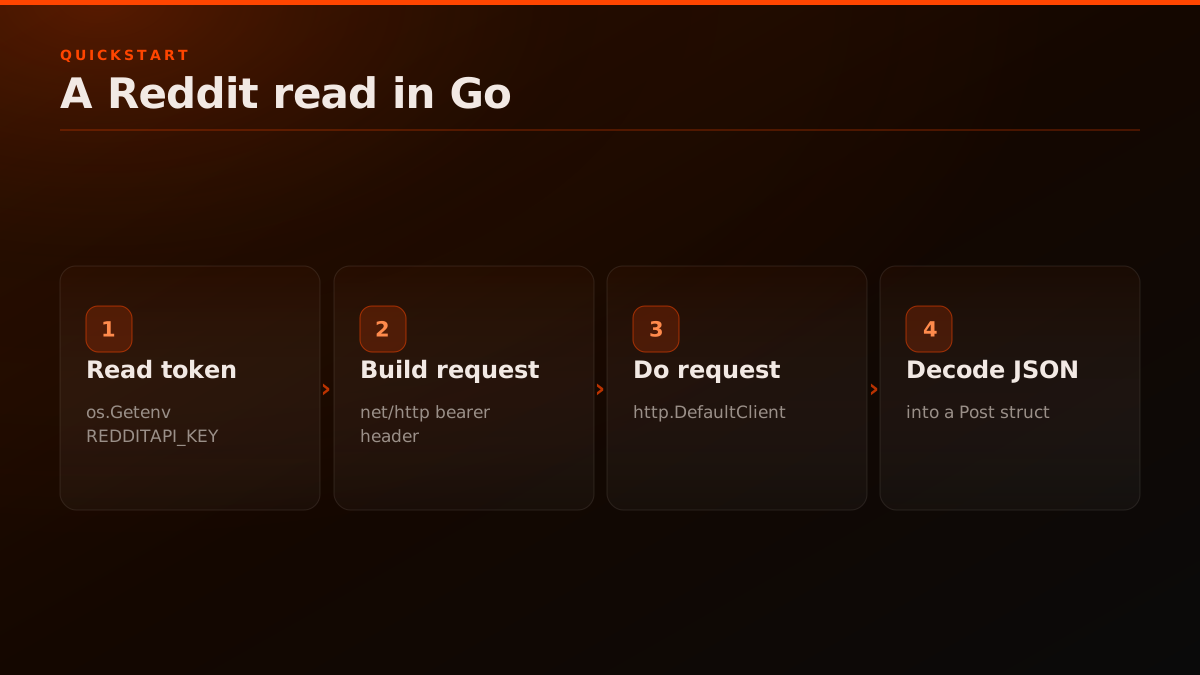
Two details save the most debugging time. First, the fields are upvotes and comments, not ups or num_comments, so match your struct tags to the live response exactly. Second, the response is wrapped: reads return { posts: [...] }, not a bare array, so you decode into a struct with a Posts field. The sort value accepts top, new, hot, and rising, and t bounds the window for top with hour, day, week, month, year, or all. The full parameter list lives in the Reddit data API overview.
Typed Structs for Every Response
The reason a wrapper felt useful was types. In Go you get them from encoding/json and struct tags, with no code generation. Declare the shape once, decode into it, and the compiler enforces field names. Because every read returns the same JSON-over-HTTPS shape, one request helper and a struct per response type cover the whole read surface:
func get[T any](path string) (T, error) {
	var out T
	req, err := http.NewRequest("GET", base+path, nil)
	if err != nil {
		return out, err
	}
	req.Header.Set("Authorization", "Bearer "+os.Getenv("REDDITAPI_KEY"))

	res, err := http.DefaultClient.Do(req)
	if err != nil {
		return out, err
	}
	defer res.Body.Close()
	if res.StatusCode != http.StatusOK {
		return out, fmt.Errorf("reddit api %d", res.StatusCode)
	}
	return out, json.NewDecoder(res.Body).Decode(&out)
}
That generic get[T] helper, available since Go 1.18 generics documented at go.dev/doc, gives you a single place to attach the header and handle non-200 responses. The net/http package reference is at pkg.go.dev/net/http. Developers keep asking which wrapper to pick precisely because the named ones stalled; the answer in Go is a typed helper you own:

Surya Prakash
@SuryaMadasi
Building a Node.js Wrapper for Reddit API: A Step-by-Step Guide. @ThePracticalDev @nodejs #NodeJs #Reddit #API #javascript https://t.co/v3pmGJFRM7
Reading Reddit Data: Posts, Search, Comments, Users
The read surface is a handful of GET endpoints, all $0.0015 per call (pricing), all through the same get[T] helper. This is the core of most Go Reddit projects: monitors, data pipelines, and research tools.
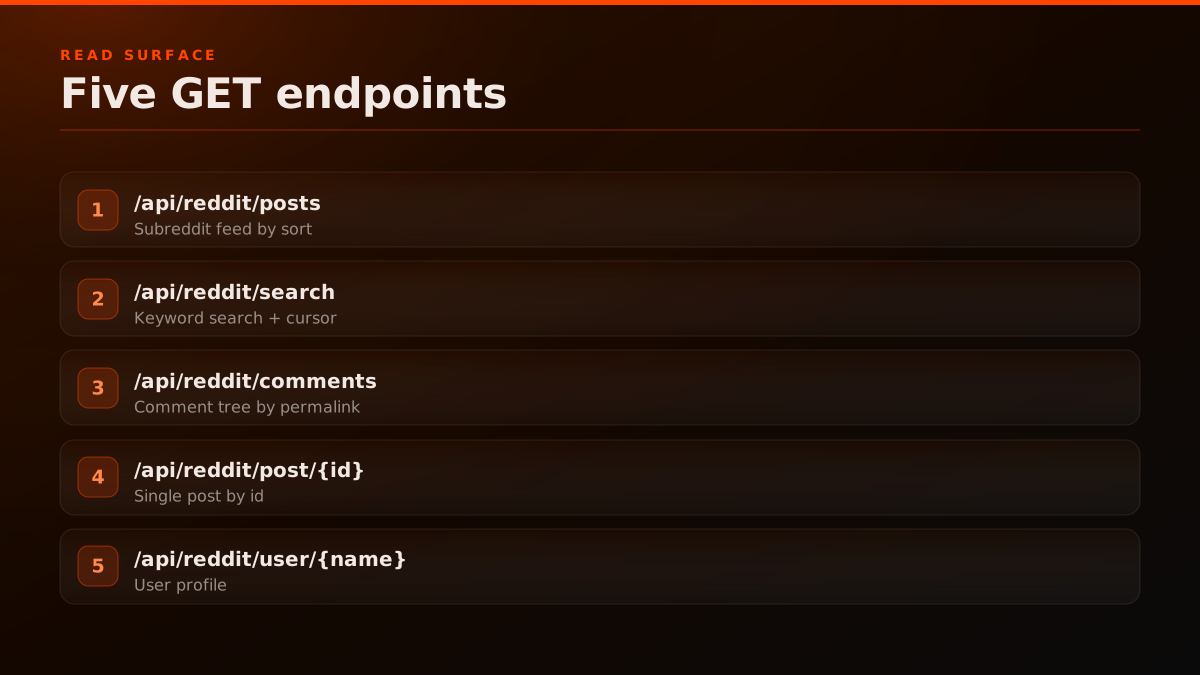
Subreddit posts come from /api/reddit/posts with a subreddit parameter. Keyword search across Reddit is /api/reddit/search with a q parameter, and it returns an after cursor alongside the posts array. Verify search from the shell first:
curl -s -H "Authorization: Bearer YOUR_API_KEY" \
  "https://api.redditapis.com/api/reddit/search?q=goroutines&sort=top&t=year&limit=5"
Then in Go, search and read a user profile with two small structs:
type SearchResponse struct {
	Posts []Post `json:"posts"`
	After string `json:"after"`
}

type User struct {
	Name         string  `json:"name"`
	LinkKarma    int     `json:"link_karma"`
	CommentKarma int     `json:"comment_karma"`
	TotalKarma   int     `json:"total_karma"`
	CreatedUTC   float64 `json:"created_utc"`
}

search, _ := get[SearchResponse]("/api/reddit/search?q=go+concurrency&sort=top&t=year&limit=25")
user, _ := get[User]("/api/reddit/user/spez")
fmt.Printf("%s has %d total karma\n", user.Name, user.TotalKarma)
Comment trees come from /api/reddit/comments with a permalink parameter, the path you already have on every post. Pass a post's Permalink and you get the post plus its threaded comments in one response. The r/redditdev community documents this exact "how do I read Reddit data" question that sends people toward a wrapper in the first place:
C Reddit API Wrapper
For keyword-driven work, the Reddit search API tutorial goes deeper on query operators, and how to find subreddits by API covers community discovery from Go.
Start building with Redditapis
Reads $0.0015, votes $0.005, writes $0.012, DMs $0.025. $0.50 free credits.
Pagination with the after Cursor
Listing endpoints cap a single response, so walking an entire subreddit means following the after cursor. Every listing response includes an after value; pass it back as the after parameter to get the next page, and stop when it comes back empty. A loop accumulates everything:
func fetchAll(subreddit string, max int) ([]Post, error) {
	var all []Post
	after := ""
	for len(all) < max {
		path := fmt.Sprintf("/api/reddit/posts?subreddit=%s&sort=new&limit=100", subreddit)
		if after != "" {
			path += "&after=" + after
		}
		page, err := get[PostsResponse](path)
		if err != nil {
			return all, err
		}
		all = append(all, page.Posts...)
		if page.After == "" || len(page.Posts) == 0 {
			break // no next page. Check listing_status before calling the data complete.
		}
		after = page.After
	}
	if len(all) > max {
		all = all[:max]
	}
	return all, nil
}
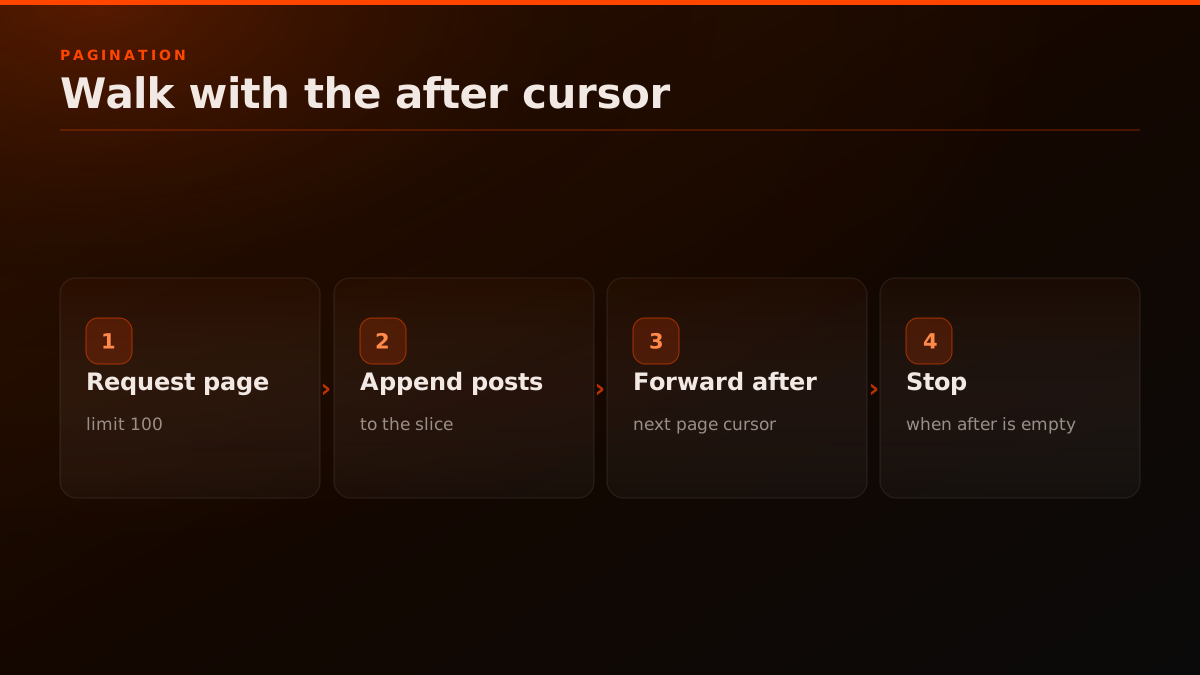
The cursor is opaque, so you never build it yourself, you only echo back the previous page's value. This is the same pattern the curl and Python clients use, so a pipeline you prototype in the shell ports to Go unchanged. Building a subreddit monitor on this loop is one of the most common Go Reddit projects, and the video below walks the HTTP-client mechanics that underpin it:
For streaming-style monitoring instead of batch pagination, weigh the tradeoffs in webhooks versus polling for Reddit data streams.
Concurrency: A Bounded Worker Pool with errgroup
Fetching ten subreddits one after another wastes time in serial round trips. Go's goroutines make concurrent fetching native, and golang.org/x/sync/errgroup gives you both error propagation and a concurrency limit in a few lines. SetLimit caps how many requests are in flight, so you stay a good client rather than opening a hundred connections at once:
import "golang.org/x/sync/errgroup"

func fetchMany(subs []string) (map[string][]Post, error) {
	var mu sync.Mutex
	out := make(map[string][]Post, len(subs))

	g := new(errgroup.Group)
	g.SetLimit(5) // at most 5 requests in flight

	for _, s := range subs {
		s := s // capture per-iteration
		g.Go(func() error {
			page, err := get[PostsResponse]("/api/reddit/posts?subreddit=" + s + "&limit=25")
			if err != nil {
				return err
			}
			mu.Lock()
			out[s] = page.Posts
			mu.Unlock()
			return nil
		})
	}
	return out, g.Wait()
}

feeds, _ := fetchMany([]string{"golang", "programming", "webdev", "rust"})
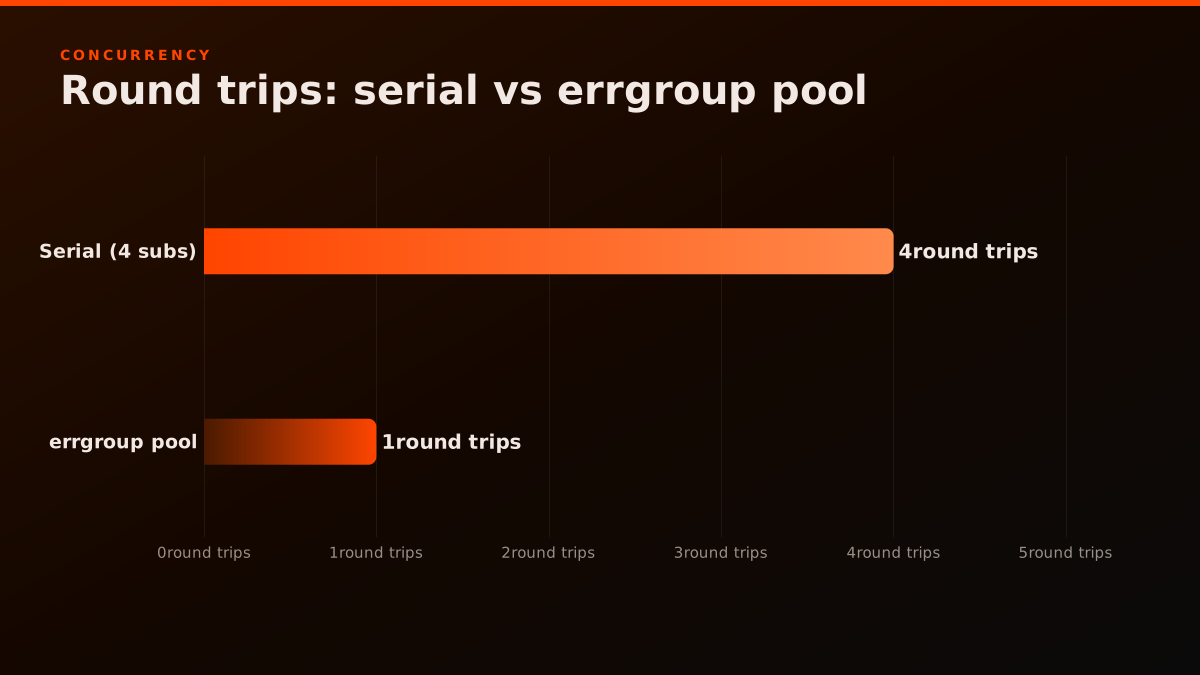
The mu.Lock guards the shared map because goroutines write to it in parallel, following the memory-model guidance in Effective Go. g.Wait() returns the first error and waits for every goroutine to finish. This concurrency model is why a Go Reddit pipeline can outrun a naive serial one, and it is where the standard library earns its keep over a wrapper that serializes calls behind its own queue. A concurrent monitor across dozens of communities is a natural fit, and it stays cheap: each read is $0.0015 (pricing), so even a wide fan-out costs cents. The r/node community trades exactly these latency-versus-safety tradeoffs when a Reddit-adjacent service scales:
Building an Open source peer-to-peer Selfhosted Reddit alternative — looking for feedback and feature ideas!
It's a pure peer-to-peer, selfhosted reddit alternative, so there’s no central server that can be taken down or censored. Each community moderates its own content and has full control over it. There are no global…
Production: Retries, Timeouts, and context
Prototype code assumes every request succeeds. Production code assumes the network is hostile. Any HTTP call can return a transient 429 or 5xx, so wrap requests in exponential backoff, and give every request a deadline through context:
func getWithRetry[T any](ctx context.Context, path string, maxAttempts int) (T, error) {
	var out T
	var lastErr error
	for attempt := 0; attempt < maxAttempts; attempt++ {
		req, _ := http.NewRequestWithContext(ctx, "GET", base+path, nil)
		req.Header.Set("Authorization", "Bearer "+os.Getenv("REDDITAPI_KEY"))

		res, err := http.DefaultClient.Do(req)
		if err != nil {
			lastErr = err
		} else {
			func() {
				defer res.Body.Close()
				if res.StatusCode == 429 || res.StatusCode >= 500 {
					lastErr = fmt.Errorf("transient %d", res.StatusCode)
					return
				}
				if res.StatusCode != 200 {
					lastErr = fmt.Errorf("reddit api %d", res.StatusCode)
					return
				}
				lastErr = json.NewDecoder(res.Body).Decode(&out)
			}()
			if lastErr == nil {
				return out, nil
			}
		}
		time.Sleep(time.Duration(1<<attempt) * 500 * time.Millisecond) // 0.5s, 1s, 2s
	}
	return out, lastErr
}
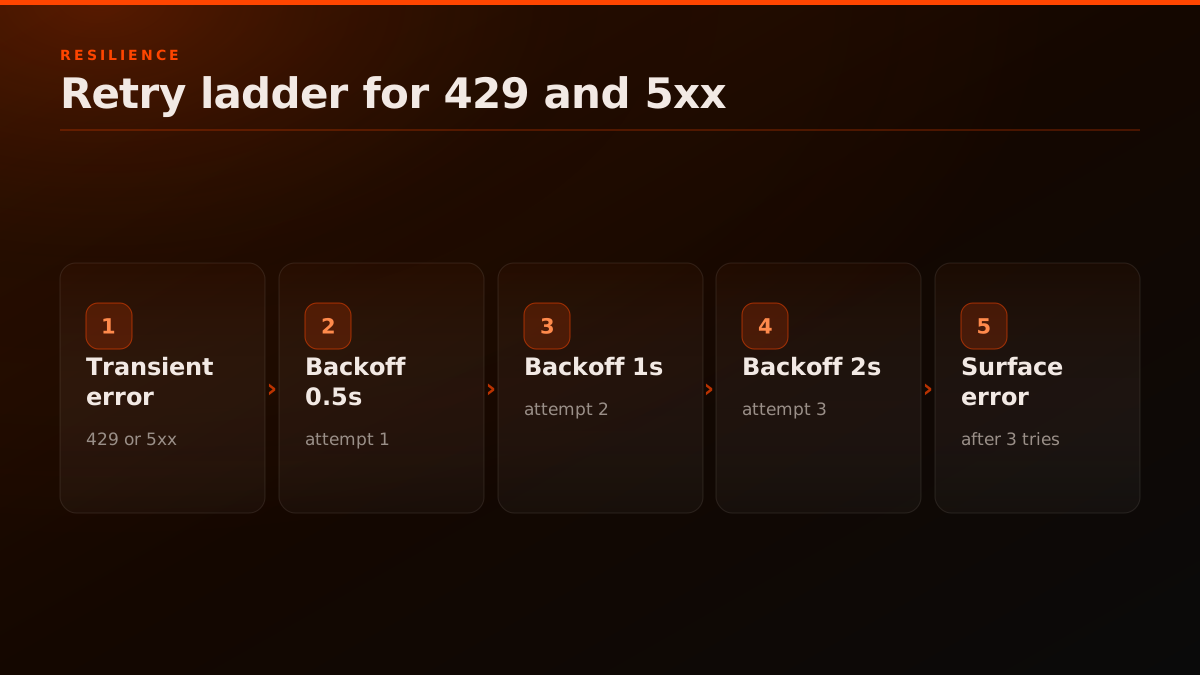
GET reads are safe to retry because they are idempotent. A context.WithTimeout at the call site bounds total time so a slow response never hangs a request handler. Set a client timeout too, since http.DefaultClient has none by default, a classic Go gotcha that lets a stalled connection block forever. The failure mode that quietly breaks unattended jobs is a transient error treated as fatal, so a retry ladder plus a deadline is the difference between a monitor that survives a rough patch and one that dies overnight. For the numbers behind a healthy request budget, see Reddit API rate limits 2026.
A Reusable Client Type
The pieces above compose into one small client type you configure once and reuse. Holding the key, the base URL, and a tuned *http.Client on a struct keeps the header and timeout in one place:
type Client struct {
	key  string
	base string
	http *http.Client
}

func New(key string) *Client {
	return &Client{
		key:  key,
		base: base,
		http: &http.Client{Timeout: 30 * time.Second},
	}
}

func (c *Client) Posts(subreddit, sort string, limit int) (PostsResponse, error) {
	path := fmt.Sprintf("/api/reddit/posts?subreddit=%s&sort=%s&limit=%d", subreddit, sort, limit)
	return doGet[PostsResponse](c, path)
}
Every method becomes a one-liner that names an endpoint and its parameters, and the *http.Client timeout applies to all of them. Because the read surface is uniform, adding an endpoint is adding a method plus a struct, never a new auth path. This is the whole ergonomic payoff of a REST endpoint over an OAuth wrapper: the client stays boring, which is what you want in a service that runs for months. For the migration story from Reddit's own OAuth API, see PRAW versus Redditapis REST.
Common Errors and What They Mean in Go
Because the client is one request helper, error handling is one status-code switch. Knowing the taxonomy turns most debugging into a five-second fix:
- 401 Unauthorized: the bearer key is missing or wrong. Check
os.Getenv("REDDITAPI_KEY")actually loaded and the header readsBearerplus the key. This is the most common first-call error, and it is always the header. - 402 Payment Required: the account is out of credit (pricing). Top up, or note the free starter credit covers a few hundred reads while you build.
- 403 Forbidden: the subreddit or user may be private, banned, or quarantined. The path is fine; the resource is restricted.
- 404 Not Found: the path is wrong or the resource is gone. A misspelled endpoint (
/api/reddit/postversus/api/reddit/posts) or a deleted thread both return404. - 429 and 5xx: transient. These are what
getWithRetryexists for. Back off and retry; do not treat them as fatal.
Reading the response body on a failed request gives you the JSON error, which almost always names the exact problem. For a systematic look at staying inside a healthy request budget, the rate limits guide covers the numbers, and the scraping benchmarks show real-world error rates across access paths.
The cheapest Reddit API. Try it free.
Reads from $0.0015 per call. $0.50 free credits. No credit card required.
The Reddit API in Go in the 2026 AI-Agent Era
A growing share of Go Reddit clients are not monitors, they are tools inside an AI agent. A Go service that gives a model live Reddit reads is a read loop plus a tool schema, and the same get[T] helper is the whole data layer. The value of a bearer-token REST endpoint here is that the agent's tool never manages an OAuth lifecycle; it makes a typed call and gets JSON back. Reddit is one of the most-cited sources in AI answer engines, which is why live Reddit reads are a common agent capability. For the agent-facing packaging, see the Reddit API for AI agents guide and how to build a Reddit MCP server.
The concurrency story matters more for agents, not less. An agent that surveys ten communities before answering wants those reads to happen at once, and the bounded errgroup pool above is exactly that pattern behind a single tool call. Keep the fan-out bounded, retry transient errors, and the tool stays fast and cheap: at $0.0015 per read (pricing), a ten-subreddit survey is 1.5 cents.
What the Reddit API Costs for a Go Service
Cost depends on which endpoints you call, not on a per-seat subscription. Reads are $0.0015 each, votes $0.005, comments and logins $0.012, and direct messages $0.025 (full per-call pricing). There is no monthly minimum and no platform call cap. Three concrete Go scenarios:
| Go scenario | Monthly calls | Approx cost |
|---|---|---|
| Subreddit monitor (500 reads/day) | ~15,000 reads | about $22.50 (pricing) |
| Agent tool (50,000 reads/month) | 50,000 reads | about $75 (pricing) |
| Weekend project (a few hundred reads) | ~300 reads | covered by free credit (pricing) |
Most Go Reddit services are read-heavy and bursty, which is the shape usage pricing fits: you pay $0.0015 per read for exactly the calls you make (pricing) rather than a flat fee sized for a workload you do not have yet. Reddit's own commercial access is sold only by negotiated agreement, at a reported $0.24 per 1,000 calls (about $12,000 per 50 million requests, per The Verge (2023)), and that contract is what stops most side projects from using the official commercial API at all. Model your exact numbers with the cost calculator and compare access paths on the pricing page.
A Complete Subreddit Monitor in Go
The pieces above assemble into the most common production shape: a subreddit monitor that polls on a schedule, keeps only posts it has not seen, and hands new ones to a handler. This is where the client type, pagination, retries, and a time.Ticker come together into a program you can leave running:
func monitor(ctx context.Context, c *Client, subreddit string, every time.Duration) {
	seen := map[string]bool{}
	ticker := time.NewTicker(every)
	defer ticker.Stop()

	for {
		select {
		case <-ctx.Done():
			return
		case <-ticker.C:
			page, err := c.Posts(subreddit, "new", 50)
			if err != nil {
				log.Printf("poll %s: %v", subreddit, err)
				continue // a transient error is not fatal to the loop
			}
			for _, p := range page.Posts {
				if seen[p.ID] {
					continue
				}
				seen[p.ID] = true
				handleNewPost(p) // your logic: alert, store, enqueue
			}
		}
	}
}
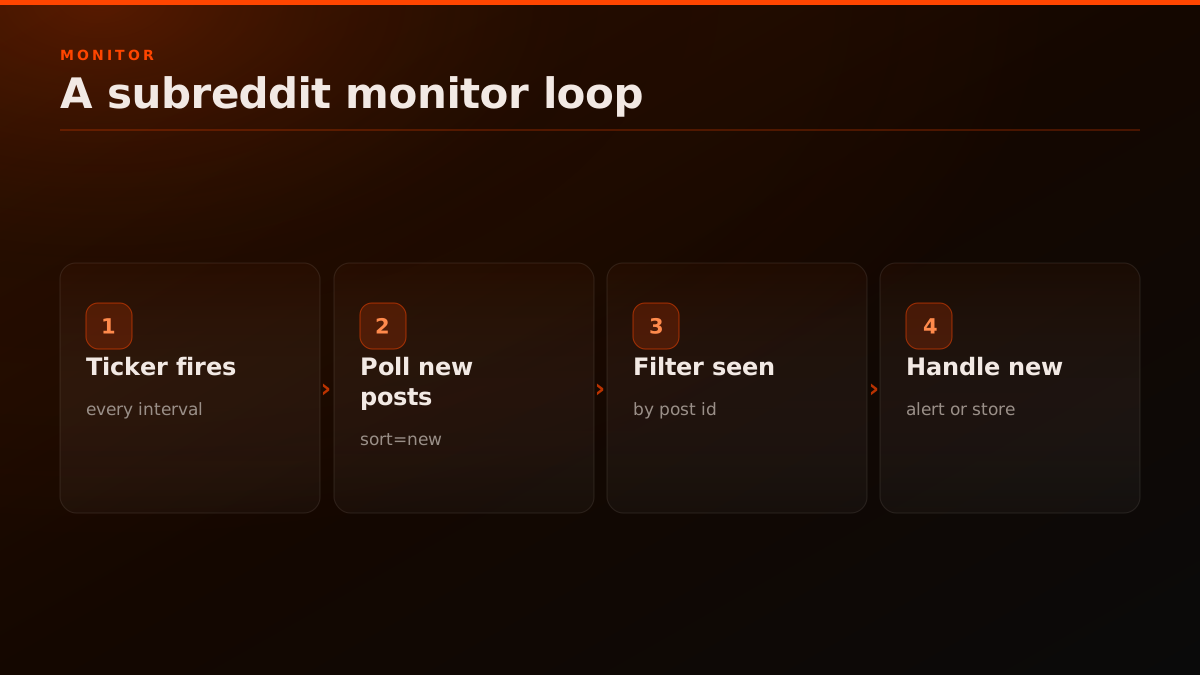
The seen map is the whole deduplication story: because sort=new returns the newest posts each poll and every post carries a stable id, tracking ids you have already handled turns an overlapping poll into a clean stream of genuinely new posts. In a long-running service, cap the map or evict old ids so it does not grow without bound, and persist the seen set if the process restarts so you do not re-alert on a backlog. The ctx.Done() case is what lets you shut the monitor down cleanly on a signal, which matters when the program runs as a service under a supervisor. A monitor like this is the backbone of brand tracking, keyword alerting, and lead discovery, and it costs about $0.0015 per poll for 50 posts (pricing). For the alerting-specific variant, see the keyword monitor tutorial, and for the streaming alternative, webhooks versus polling.
Choosing the poll interval is a cost-versus-freshness tradeoff. A busy subreddit warrants a tighter interval because new posts arrive constantly; a quiet one can poll every few minutes without missing anything. Because each poll is a single read, the math is simple: a 60-second interval is 1,440 reads a day, roughly $2.16 a month for one subreddit (pricing), so you can afford to poll aggressively where it matters and back off where it does not. This is the kind of arithmetic that a flat subscription hides and a per-call model makes obvious, which is exactly why usage pricing suits a monitor.
Testing and Observability for a Go Reddit Service
A service that runs for months needs two things a prototype skips: tests that do not hit the network, and logging that tells you what happened when something breaks. Go's net/http/httptest package makes the first easy by standing up a fake server that returns canned JSON, so your client logic is tested without spending a single API call:
func TestPostsDecode(t *testing.T) {
	srv := httptest.NewServer(http.HandlerFunc(func(w http.ResponseWriter, r *http.Request) {
		if got := r.Header.Get("Authorization"); got != "Bearer test-key" {
			t.Errorf("missing bearer header, got %q", got)
		}
		w.Write([]byte(`{"posts":[{"id":"abc","title":"hi","upvotes":42,"comments":3}],"after":""}`))
	}))
	defer srv.Close()
	// point the client's base at srv.URL and assert it decodes upvotes=42
}
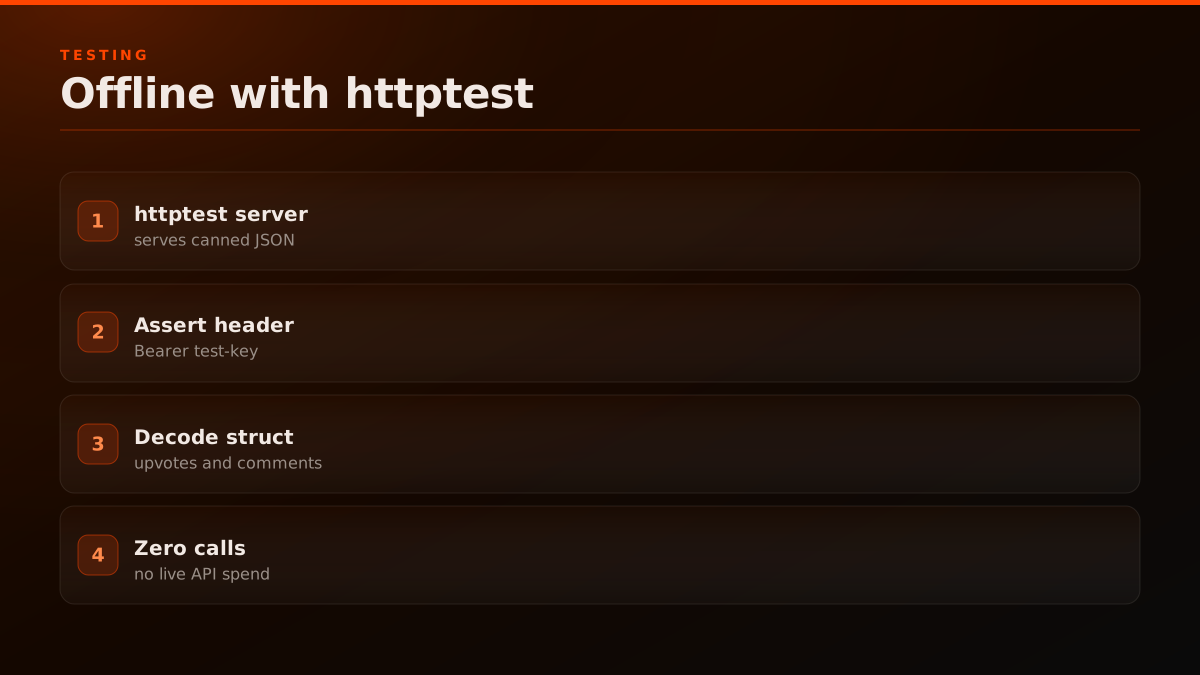
Testing against httptest means you can assert the header is set, the JSON decodes into the right struct, and error paths behave, all offline and instantly. This matters more with a paid API than a free one, because a test suite that hammered the live endpoint would both cost money and be flaky. For observability in production, log the status code, the endpoint, and the elapsed time of every request, and count 429 and 5xx responses so a rising error rate is visible before it becomes an outage. Go's standard log/slog package gives you structured logs with a few lines, and pairing it with a simple counter for retries turns the retry ladder from an invisible mechanism into a metric you can alert on.
The failure mode to instrument for is the slow degradation, not the hard crash. A monitor that starts returning 429 more often is telling you it is polling too aggressively or sharing a budget with another job, and a monitor whose latency creeps up is telling you the upstream is under load. Both are visible in logs long before they cause a missed alert, so the observability work pays off the first time a poll starts to struggle, and Go's log/slog package makes structured request logs a few lines of code. The r/webdev community trades hard-won lessons about exactly these production-runtime surprises:
We spent 33 months building a data grid, here's how we solved slow UIs.
A few months ago, we launched the beta of [LyteNyte Grid](https://www.1771technologies.com/), our high-performance React data grid. Today, we're taking the next leap forward with LyteNyte Grid v1, a major release that…

When to Reach for Reddit's Official OAuth API Instead
A tutorial that only sells one path is not being honest, so here is the boundary. Reddit's own OAuth Data API, documented on the official Reddit developer API reference, is the right choice in a few specific cases, and a Go service should use it when they apply:
- Single-user personal script. If you act entirely as one authenticated user on your own account, for a script that never redeploys or monetizes, the official OAuth flow is a one-time setup cost and the free tier covers you.
- Explicitly permitted non-commercial use. If your case fits Reddit's free non-commercial terms and stays under the free rate budget, the official API is free where a per-call endpoint is not.
- Very high volume with a commercial agreement. If you can absorb a negotiation and an app review, a direct commercial agreement prices lower per call than we do, at a reported $0.24 per 1,000 (about $12,000 per 50 million requests, per The Verge (2023)).
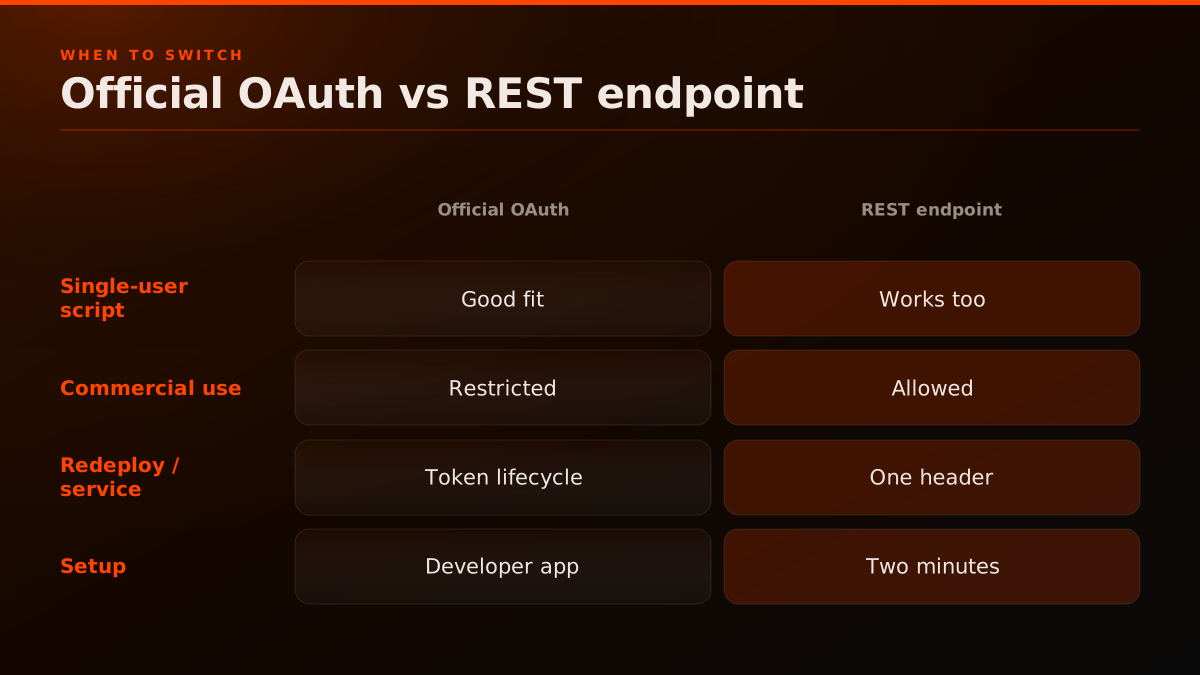
Outside those cases, the friction is the point. The official path means a registered developer app, an OAuth flow with a token you refresh, a review queue that has been slow through 2025 and 2026, and free-tier terms that forbid commercial use. A Go service that needs commercial use, a redeploy in its future, or reads without an OAuth lifecycle is exactly what a bearer-token REST endpoint is for. The practical test is deployment shape: a script you run once on your laptop can absorb the OAuth setup, while a service that ships to a server, serves users, or runs unattended wants the one-header path so there is no token to expire at an inconvenient hour and no app registration to renew. Weigh your own case against both, because the right answer is the one that matches how the code will actually run, not the one a tutorial prefers. The honest summary is that the two paths serve different shapes: the official API suits a permitted single-user non-commercial script, and a managed REST endpoint suits a commercial or multi-tenant service that wants one header and no app. For the full side-by-side across access paths, see PRAW versus Redditapis REST and the Reddit data API overview.
Ship It
The Reddit API in Go is not a wrapper problem, it is an net/http problem you already know how to solve. The standard library's HTTP client, one bearer token, and a generic get[T] helper replace the entire OAuth-app stack, and the same helper covers reads, pagination, concurrency, and retries. Skip the developer-app queue, decode responses into structs you control, and you have a production Reddit client in an afternoon.
The whole client fits in a single file: a base URL, a key from the environment, a generic get[T] for reads, a fetchAll for pagination, an errgroup pool for concurrency, and a getWithRetry for resilience. None of it depends on a third-party package that can go stale, because you wrote every line yourself. Generate a key and make your first call in about two minutes: sign up for free, no card required. When you are ready to wire Reddit into an agent, the Reddit MCP server guide picks up where this leaves off, and the Reddit data API overview maps the full endpoint surface.
Where these numbers come from.
Each row is a figure in this post and the artefact it was read from. Reddit's access rules and the third-party archives around them keep moving, so check the date on a source before you build against it.
- go-reddit on GitHub
- The main community Go wrapper the guide weighs against the standard library.
- Go net/http
- The standard-library HTTP client the guide builds the Reddit client on.
- golang.org/x/sync/errgroup
- The bounded concurrency primitive used for the guide's worker pool.
- Reddit Data API Terms
- Reddit's commercial data terms behind the managed endpoint the client targets.
Frequently asked questions.
You do not need one. The Reddit API in Go is JSON over HTTPS, so the standard library net/http plus encoding/json covers every call. The Go wrappers that exist, like github.com/vartanbeno/go-reddit, target Reddit's OAuth app flow and see little activity. Redditapis exposes a stable bearer-token REST interface, so a small typed client around net/http reads posts, search, comments, and users without registering a developer app. See the quickstart or sign up for a free key.
Set one header: Authorization: Bearer YOUR_KEY. There is no OAuth dance, no client ID, no client secret, and no token refresh. Read the key from an environment variable with os.Getenv, attach it to every *http.Request, and you are done. The setup section shows the full request helper, and the authentication overview covers how bearer auth compares to Reddit's OAuth flow.
Every listing response includes an after cursor. Pass it back as the after query parameter to fetch the next page, and stop when it comes back empty. A for loop that accumulates posts and forwards the cursor walks an entire subreddit or search result set. The pagination section has the full loop, and the pagination guide covers the same pattern across languages.
Go's goroutines make concurrent fetching a few lines. Launch one goroutine per subreddit, bound them with a golang.org/x/sync/errgroup group plus SetLimit so you never open too many connections at once, and collect results. The concurrency section shows the bounded worker pool. Reads price at $0.0015 each (pricing), so a wide fan-out stays cheap.
Wrap requests in exponential backoff for 429 and 5xx responses: sleep a growing interval between retries, capped at three attempts. GET reads are safe to retry because they are idempotent. The production section has the retry helper with context deadlines. See also Reddit API rate limits 2026 for the numbers behind a healthy request budget.
Redditapis charges per call: $0.0015 per GET read, $0.005 per vote, $0.012 per comment or login, and $0.025 per direct message (pricing). A read-heavy Go service, a monitor or a data pipeline, spends almost nothing because reads dominate. There is no monthly minimum and no platform call cap. Model your own volume with the cost calculator, and the first credit is free at signup.
Keep reading.
Continue exploring related pages.
Reddit API documentation
The complete 2026 reference: auth, all 74 endpoints, and code.
Get a Reddit API key
Instant bearer token, no waitlist and no enterprise contract.
Reddit Responsible Builder Policy
Why Reddit denies API applications, and the managed REST bypass.
Reddit API use cases
14 use cases from AI training to brand monitoring and DMs.
Reddit Search API
Search posts, comments, users, and communities over one REST endpoint.
Reddit MCP server
Wrap the REST API as MCP tools for Claude, Cursor, and any MCP client.
Reddit MCP hub
Install tabs for every client, the full tool table, pricing and fixes.
Reddit API for AI agents
Live Reddit context for tool calls, MCP servers, and RAG pipelines.
Redditapis pricing
Endpoint-level costs and quick monthly totals - reads from $0.0015 / call.
Reddit API cost calculator
Estimate monthly spend using your request volume.
Reddit API guides and tutorials
Tutorials, walkthroughs, and API deep-dives for developers.
Reddit API alternatives
Evaluate alternatives by cost model, limits, and integration fit.
Cheap Reddit API
The cheapest way to get Reddit data: $0.0015 per call, no contract, no minimum.
Official Reddit API vs Redditapis
Access, setup, rate limits, and pricing, side by side.
PRAW alternative
A hosted Reddit REST API for any language, no app registration or OAuth.
Reddapi alternative
A maintained Reddit REST API with published pricing and write endpoints.
Reddit comment scraper alternative
The raw comment API: search and filter comments, historical and live, clean JSON.
Reddit scraper API
Hosted scraper API vs building your own: no proxies to manage, clean JSON.
RapidAPI Reddit alternative
A direct, maintained Reddit API with published pricing and write endpoints.
Bright Data Reddit alternative
A purpose-built Reddit API vs a general scraping platform: structured JSON, plus writes.
ScraperAPI Reddit alternative
A Reddit-native API vs a generic HTML fetcher: auth and pagination handled, typed JSON.
TikHub alternative
TikHub's Reddit surface is read-only; get comment, vote, and DM endpoints too.
EnsembleData alternative
No $100/month floor: pay per call from $0.0015, plus write, vote, and DM endpoints.
Scrape Creators alternative
7 read-only Reddit endpoints vs a dedicated API with real write, vote, and DM paths.
FetchLayer alternative
Posts, comments, and search only; add vote, comment, and DM over the same REST auth.
PullPush alternative
PullPush is free but volunteer-run and goes offline for reindexing; a maintained REST API that stays up.
Reddit monitoring API
Build your own keyword and brand-mention monitor: search, comment search, and subreddit streams over REST.
F5Bot vs Redditapis
F5Bot's Slack and Discord delivery needs its $49.99/mo Gold tier; Redditapis includes it from $19/mo.
Syften vs Redditapis
Syften caps you at 100 to 500 results a day; Redditapis allows 10,000 a day per monitor at the entry plan.
Octolens vs Redditapis
Octolens meters by mention with overage fees; Redditapis is flat-priced by subreddit slot from $19/mo.
Affiliate program
Earn 20% lifetime commissions - capped at $5,000/yr.
Reddit Vote API tutorial
Upvote and downvote a post programmatically via the REST API.
Reddit Data API: REST, no PRAW
REST endpoints for Reddit data with no PRAW and no OAuth dance.
Reddit scraping benchmarks
Real throughput, error rates, and cost benchmarks for Reddit scraping.
Reddit API answers
Direct answers on cost, access, rate limits, endpoints, and auth.
How much the Reddit API costs
Per-call pricing from $0.0015 a read, with $0.50 in free credits.
Reddit API in Python
One requests call with a bearer token, no PRAW and no OAuth flow.
Reddit shadowban checker
Check if a Reddit account is shadowbanned in seconds, free and no login.
Subreddit stats checker
See any subreddit's live subscriber count, active users, and age, free and no login.
Similar reads.
More guides on the Reddit API, scraping, pricing, and MCP servers.
Reddit Comment IDs Are Now 13 Characters and Out of Order: What Breaks in Your Code
Reddit's new comment IDs are 13 characters and no longer increasing. When the change went live, what it breaks in your code, and the fix for each case.
Reddit Stops New Data API Requests on October 31: What to Do If You Have Not Applied
Reddit stops accepting new Data API requests on October 31, 2026. What closes, why the request form keeps failing, and how a new project reads Reddit after.
Reddit Data for Market Research After ChatGPT's Citation Drop (2026)
ChatGPT now cites Reddit about 88% less than six months ago. Here is what Reddit data is still worth pulling, and how to mine it through an API.
Reddit RSS Feeds End November 13, 2026: What Breaks and What Replaces Them
Reddit stops supporting RSS feeds on November 13, 2026. What breaks, what Reddit offers moderators instead, the 2027 API dates, and how to replace a feed.
How to Estimate Your Reddit API Bill: a Per-Call Cost Model in Python
A per-call Reddit API cost model in Python: price every read, write and DM, then size the monthly bill for a keyword monitor, a RAG refresh and a reply bot.
Reddit API Limitations in 2026: What the API Will Not Do, Beyond Rate Limits
Every Reddit API ceiling that is not a rate limit: the 1,000-item listing cap we measured, search depth, deleted content, access approval and commercial terms.
Subreddit AI-Rule Index 2026: 52.8% of the 250 Most Popular Subreddits Prohibit AI-Generated Posts or Comments
We read the rules of the 250 most popular subreddits. 132, or 52.8%, prohibit AI-generated posts or comments. 27 of the 50 largest do. 9 require disclosure.
Reddit Subscriber Counts Disappeared From Subreddits: How to Read Them From the API, and What 120 Subreddits Say About Whether the Number Ever Meant Anything
Reddit replaced the member count with Visitors and Contributions in September 2025. The data API still returns subscribers. We measured 120 subreddits to test Reddit's reason for the swap, and the data agrees with Reddit.