Apify Reddit Scraper Deprecated: Why Actors Broke in 2026 and How to Migrate
The most used Apify Reddit actor is now marked Deprecated. Why Reddit actors broke in 2026, what changes on November 13, and how to migrate a job.
The most used Apify Reddit actor, trudax/reddit-scraper, now carries a Deprecated label on its Apify Store page. If a scheduled Reddit run of yours started returning errors, fewer items or nothing at all this year, the cause is on Reddit's side, and one more change lands on November 13, 2026.
TL;DR: The trudax/reddit-scraper Store page showed a Deprecated label, 15K total users and 483 monthly active users when we read it on 7 November 2026. Logged-out Reddit reads began returning 403 in late May 2026, and Reddit stops supporting RSS on November 13. Check every run for silent empty results, then pick a route.
TL;DR
The Apify Reddit Scraper by trudax, with 15K total users, is marked Deprecated on its Apify Store page as of 7 November 2026. Reddit actors broke in two waves: logged-out .json reads began returning 403 in late May 2026, and Reddit stops supporting RSS feeds on November 13, 2026, which is the default data source of both trudax actors. Teams can move to another actor, read with a logged-in session, build a Devvit app, or call a keyed data API, and should check every scheduled run for silent empty results first.
This is an independent guide from redditapis.com, a third-party API that is not affiliated with Reddit, Inc. or with Apify. We sell a Reddit data API, so we have a stake in where you land; the Apify facts below link to the actor pages and changelogs they come from, and the cost comparison is in our separate Reddit API pricing vs Apify post. What redditapis.com reads and which calls it bills is on our data access page.
Is the Apify Reddit Scraper deprecated?
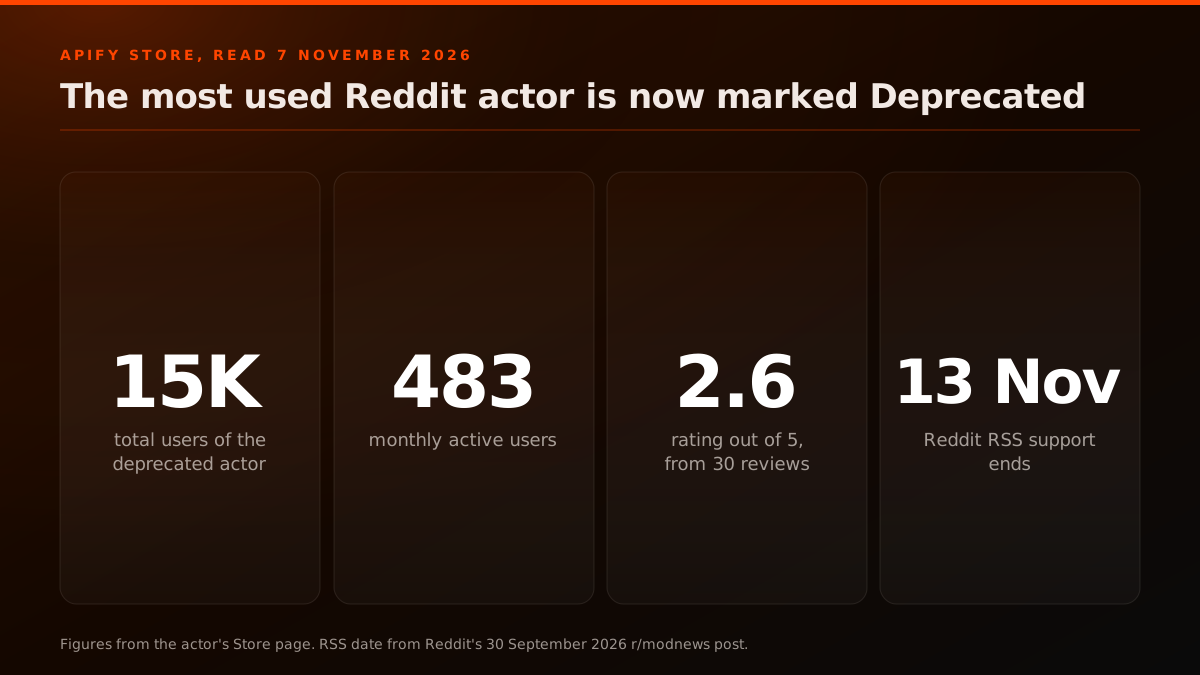
Yes. The trudax/reddit-scraper actor shows a Deprecated label on its Apify Store page, read on 7 November 2026, along with a link to alternative actors. It is maintained by the community, not by Apify, and it was still the actor ranking first on Google for "apify reddit scraper" that day.
What the Store page showed when we read it:
- Status: Deprecated, with a "See alternative Actors" link.
- Usage: 15K total users, 483 monthly active users and 252 bookmarks.
- Rating: 2.6 out of 5 from 30 reviews.
- Price line: from $0.10 per 1,000 results, plus Apify platform usage; the README says 1,000 results cost "less than $4 in platform usage credits".
- Last modified: "a day ago" on the page; the newest changelog entry is 5.9.0 of 5 November 2026.
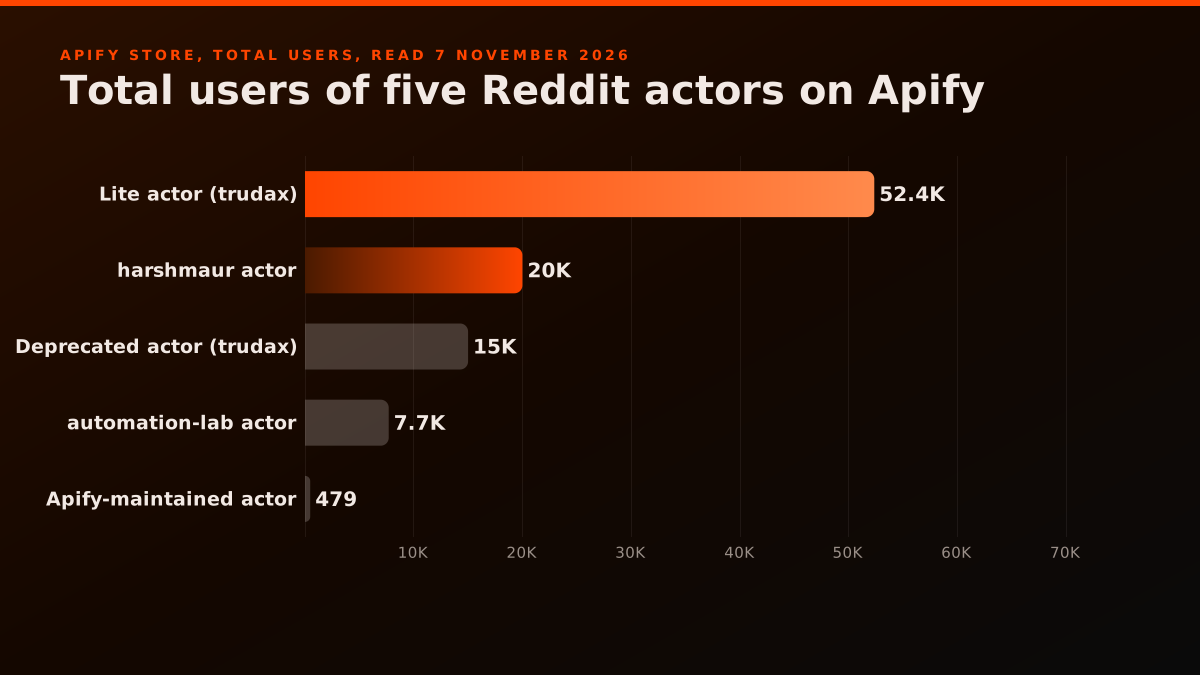
The sibling Reddit Scraper Lite by the same developer was not marked deprecated on the same day. It is the bigger of the two by far, with 52,365 total users and 8,622 monthly active users, and it shares the same RSS default described below.
Why did Apify Reddit actors stop working in 2026?
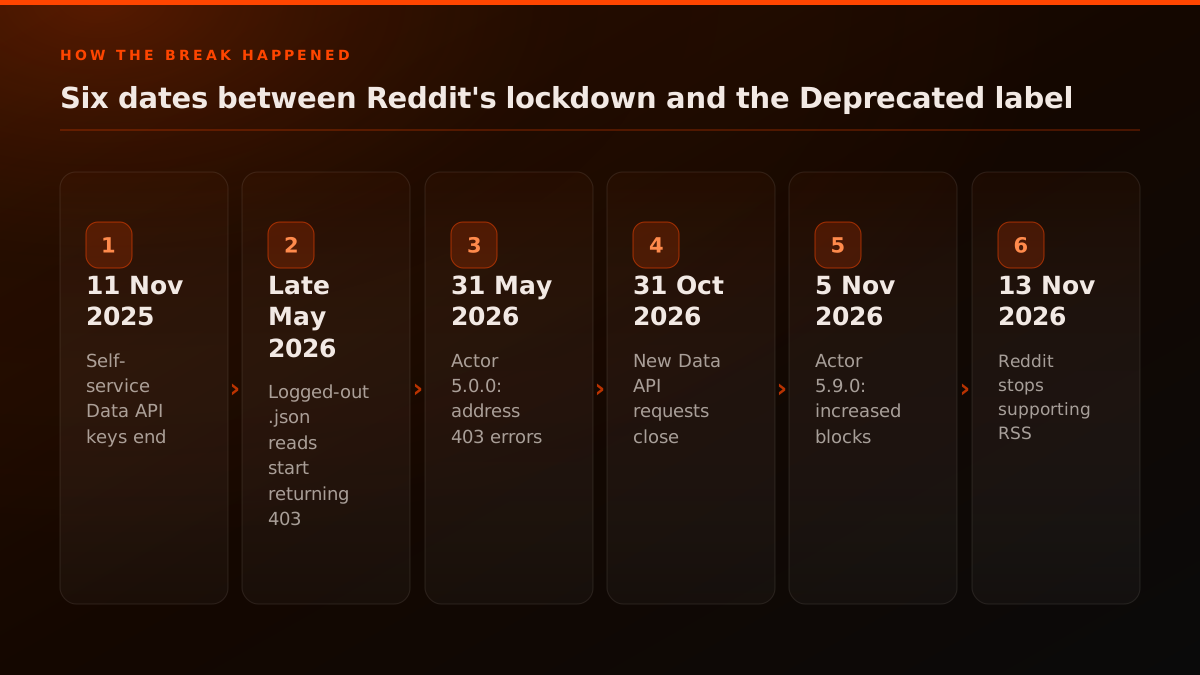
Because Reddit stopped serving logged-out reads. The first public reports we found are dated 29 and 30 May 2026, when developers saw .json requests return 403. The trudax actor shipped 4.22.2 on 30 May and a breaking 5.0.0 on 31 May, both about 403 errors, and the blocks never fully went away.
The r/apify thread that opened the wave is short and blunt:
Since yesterday, I can't get Apify scrape Reddit. I'm doing low volume calls, 1000 items at max.
Blocked reddit scraping
Since yesterday, I can't get Apify scrape Reddit. I'm doing low volume calls, 1000 items at max. I know of the "official Reddit API" way - anybody found a good workaround?
What the replies in that thread established, in order:
- 1 June 2026: "You can no longer access the 'subreddit url + .json' API without valid session cookies."
- 19 August 2026: a developer who had pulled about 6.5k posts found that logged-out requests to any .json endpoint "returned 403 100% of the time", from a residential IP, at any volume.
- Same reply: "Pacing doesn't buy you anything without" a logged-in session, so slowing a logged-out run down does not bring it back.
It isn't rate limiting, it's an auth gate.
The same break shows up outside Apify. One builder wrote in September that it was "json endpoints 403 everywhere, 1 feed per minute per ip":

Ben 🏛️
@Ben100__
for my reddit tool i spent the whole summer working around a closed api json endpoints 403 everywhere, 1 feed per minute per ip, official access at 12k$ a month for a saas ended up with a cloudflare relay and rss feeds read by an agent, it runs but it's duct tape now
Our .json endpoint explainer covers the technical side of the change in more depth.
What did the deprecated actor's changelog say?
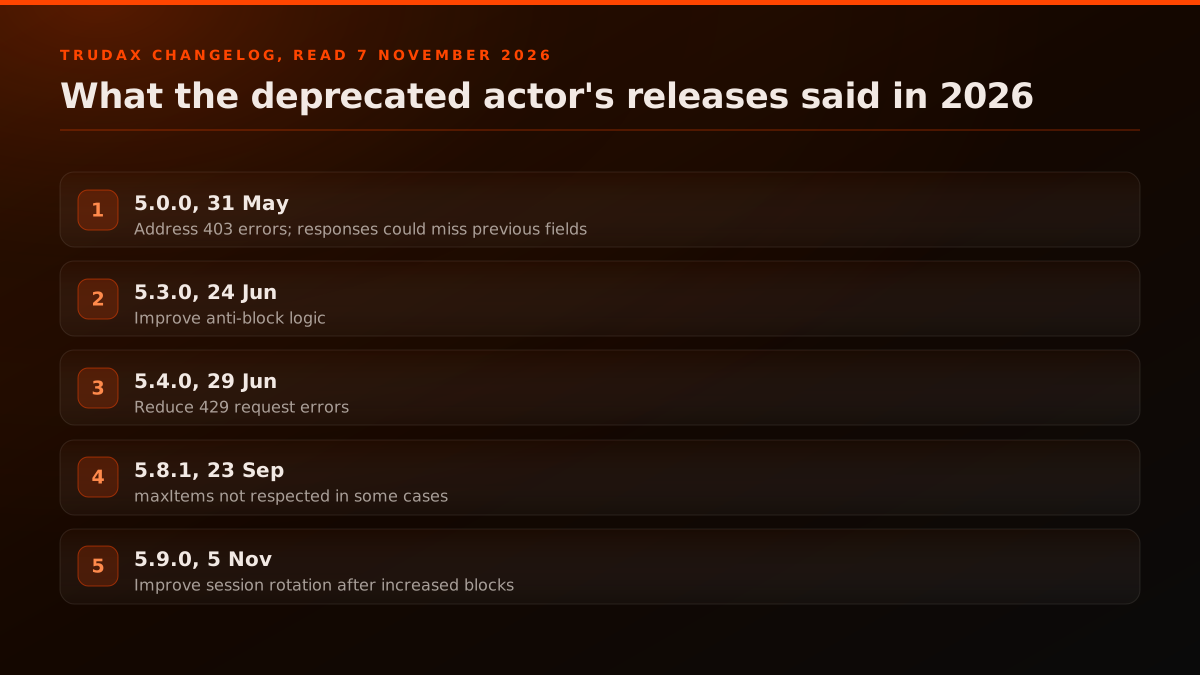
It reads like a running log of the lockdown. Between 30 May and 5 November 2026 the trudax actor shipped fixes for 403 errors, anti-block logic, 429 errors and session rotation, and the 5.0.0 release warned that responses "could be missing some of the previous fields".
The releases that matter, from the actor changelog:
What the deprecated actor's 2026 releases said
| Release | Date | Note | Source |
|---|---|---|---|
| 4.22.2 | 30 May 2026 | Work around 403 errors | published |
| 5.0.0 | 31 May 2026 | Address 403 errors; response could be missing some previous fields (breaking) | published |
| 5.3.0 | 24 Jun 2026 | Improve anti-block logic | published |
| 5.4.0 | 29 Jun 2026 | Reduce 429 request errors | published |
| 5.8.1 | 23 Sep 2026 | maxItems not respected in some cases | published |
| 5.9.0 | 5 Nov 2026 | Improve session rotation after increased blocks | published |
Two things follow for anyone still running it:
- Fields can be missing without an error. The 5.0.0 note is the only warning you get that a column your report depends on may now be empty.
- Each fix is a race. Five block-related releases between May and November is the pattern of a source that keeps moving.
Why does a broken run look like a clean run with no results?
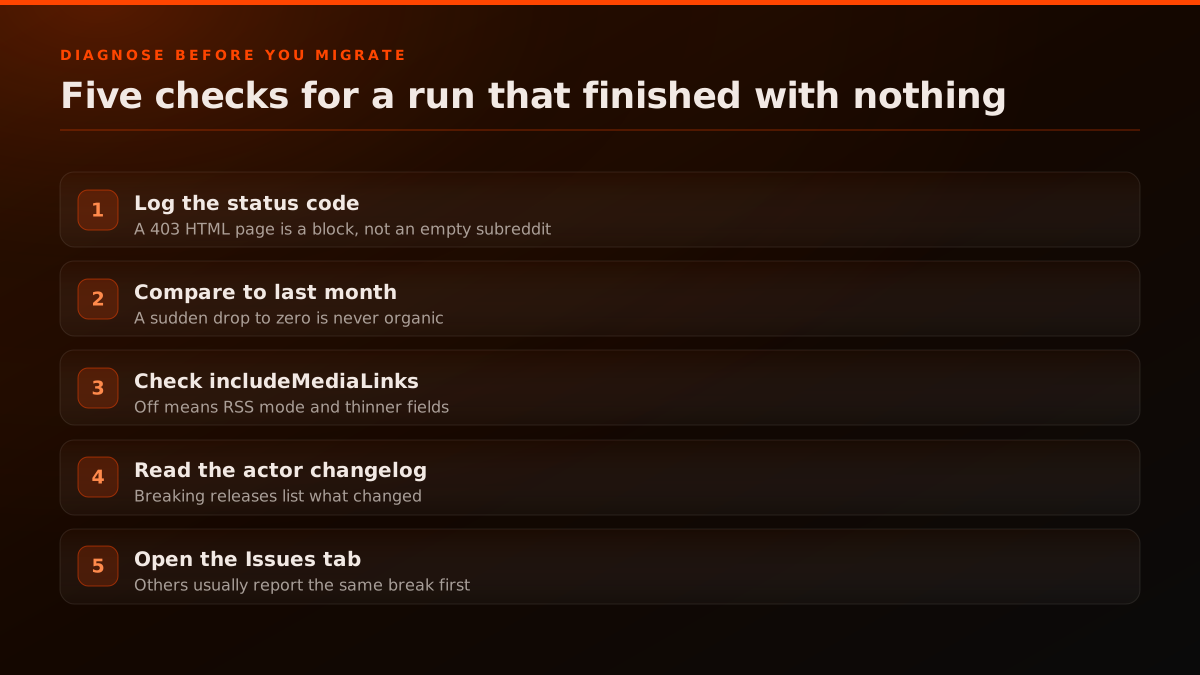
Because a Reddit block page is HTML, not JSON. A run that parses JSON inside a try block and returns an empty list on failure turns a total block into "0 items found", which looks exactly like a quiet subreddit. Check status codes before you trust any zero.
The dangerous failure is the quiet one
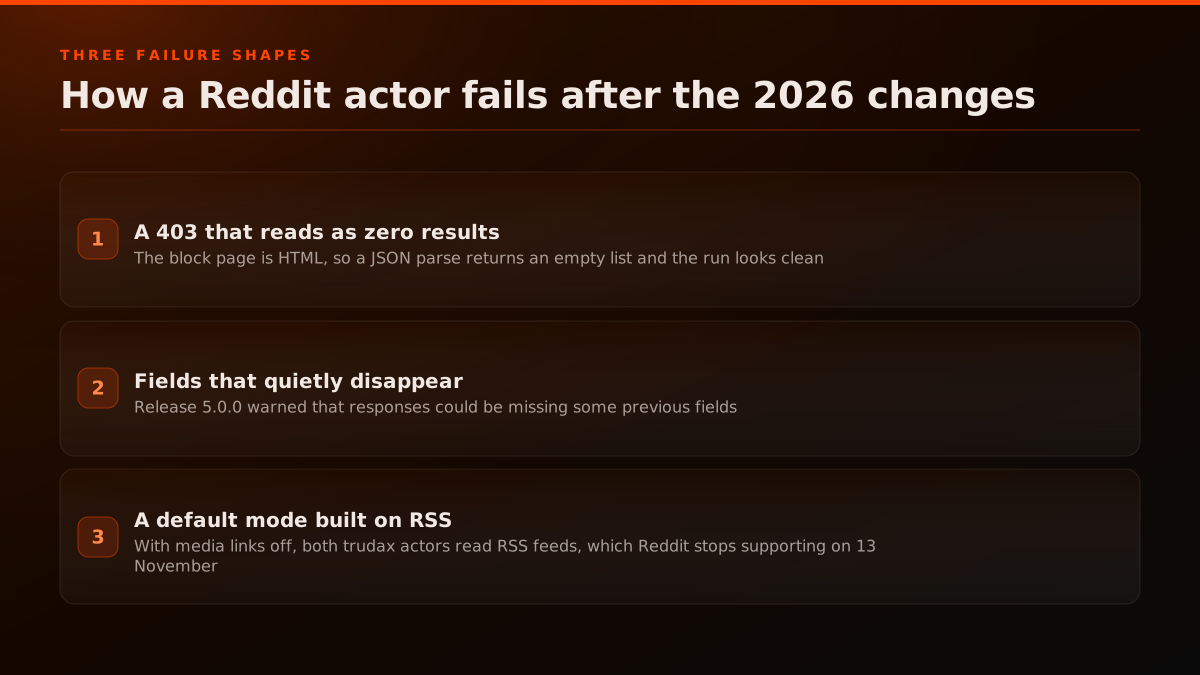
The three failure shapes we see described most often:
- A 403 that reads as zero results. The run succeeds, the dataset is empty, nobody gets paged.
- Fields that disappear. Scores or comment counts arrive blank after a breaking release.
- A thinner default mode. RSS-based runs return titles and links but no votes or comment counts.
A quick way to check your own history, if your runs write to a table:
-- days where a scheduled Reddit run returned nothing
SELECT run_date, COUNT(*) AS items
FROM reddit_items
GROUP BY run_date
HAVING COUNT(*) = 0
ORDER BY run_date DESC;
What happens to Apify Reddit actors on November 13, 2026?
Reddit stops supporting RSS feeds that day, per its 30 September 2026 admin post on r/modnews. Any actor run that reads Reddit through RSS loses its source. Both trudax actors use RSS by default, so default runs are the most exposed, whatever their price.
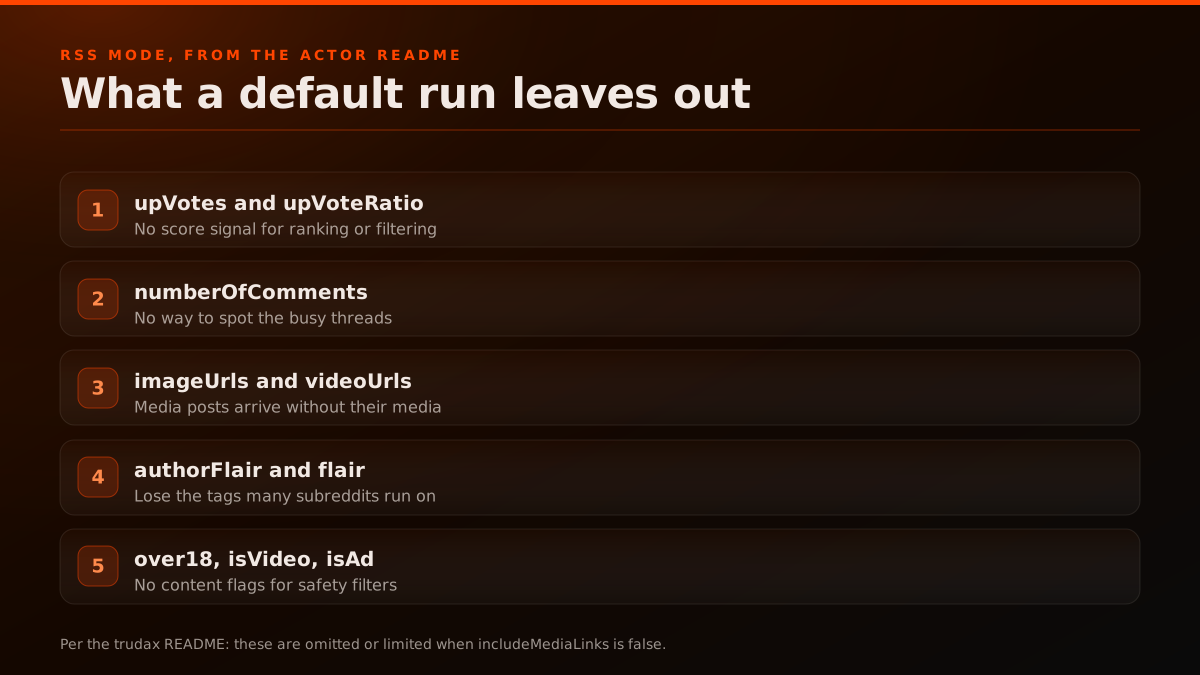
The r/modnews post cites large-scale scraping and automated abuse as the reason, and points moderators to Devvit apps. TechCrunch reported the change the same day, alongside the end of public API access by March 2027. The trudax README says that with includeMediaLinks off, the default, "the scraper uses fast RSS feeds", which omit or limit these fields:
- upVotes and upVoteRatio
- numberOfComments
- imageUrls and videoUrls
- authorFlair, flair and userId
- isVideo, isAd and over18
The default run is the most exposed one
Developers in the r/scrapingtheweb thread are already passing this around. When one commenter suggested on 29 October that "polling the native RSS feeds with a basic script is basically free", the reply on 3 November was: "it's being phased out of support november 13 2026." Our RSS shutdown explainer lists what else breaks that day.
Start building with Redditapis
Reads $0.0015, votes $0.005, writes $0.012, DMs $0.025. $0.50 free credits.
Which Apify Reddit actors are still listed, and what do they cost?
Several. On 7 November 2026 the Apify Store listed active Reddit actors from Apify itself, from trudax (Lite), and from independent developers such as harshmaur and automation-lab, with "from" prices between $1.15 and $3.40 per 1,000 items. Each one has its own method, fields and maintenance record.
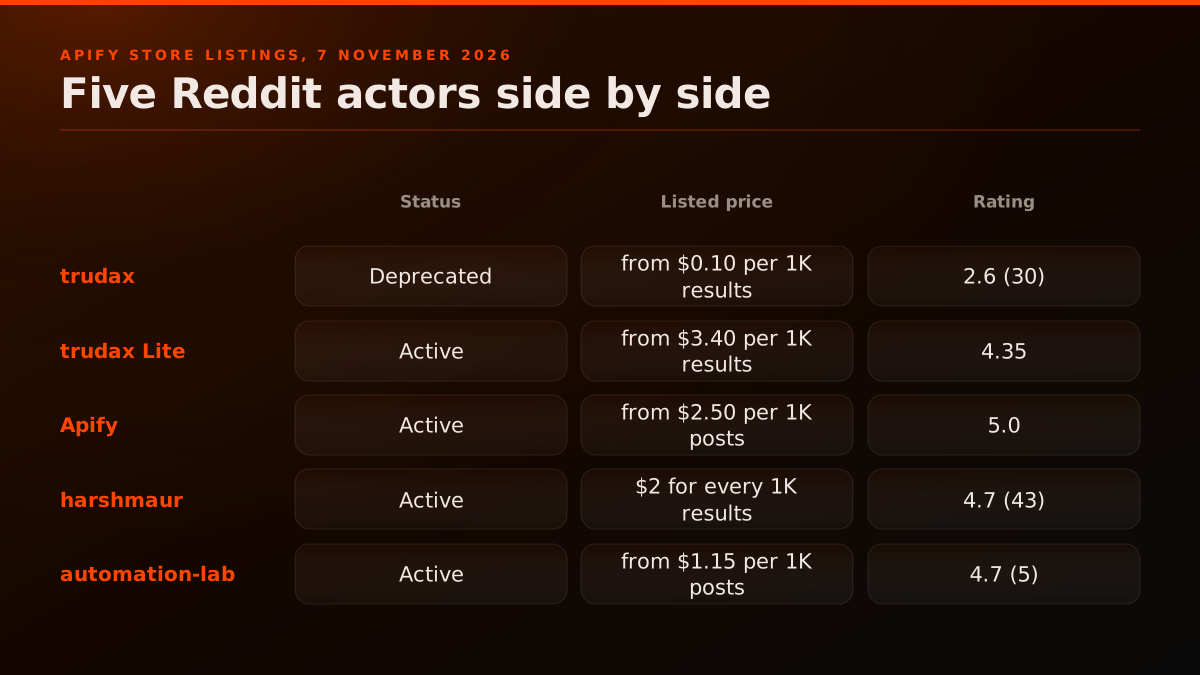
Five Reddit actors on the Apify Store, as listed on 7 November 2026
| Actor | Status | Listed price | Total users | Rating | Source |
|---|---|---|---|---|---|
| trudax/reddit-scraper | Deprecated | from $0.10 per 1,000 results, plus platform usage | 15K | 2.6 (30 reviews) | published |
| trudax/reddit-scraper-lite | Active | from $3.40 per 1,000 results | 52,365 | 4.35 | published |
| apify/reddit-scraper | Active, maintained by Apify | from $2.50 per 1,000 posts | 479 | 5.0 | published |
| harshmaur/reddit-scraper | Active | $2 for every 1,000 results | 20K | 4.7 (43 reviews) | published |
| automation-lab/reddit-scraper | Active | from $1.15 per 1,000 posts | 7.7K | 4.7 (5 reviews) | published |
Notes from each page, read the same day:
- apify/reddit-scraper is maintained by Apify, needs no Reddit login or API key, and says "Only public content is read". It is pay per event, from $2.50 per 1,000 posts, with 336 monthly users.
- harshmaur/reddit-scraper lists a starting price of $2 for every 1,000 results and 4.7 from 43 reviews.
- automation-lab/reddit-scraper lists from $1.15 per 1,000 posts and $0.58 per 1,000 comments, with empty runs free.
- trudax/reddit-scraper-lite lists from $3.40 per 1,000 results and shares the RSS default.
Apify's own tutorial for the deprecated actor still ranks on the first page for this search, and it is a clear picture of how the input form works if you are mapping an old job:
For cost per workload rather than per listing, see Reddit API pricing vs Apify.
How many people are looking for a way out?
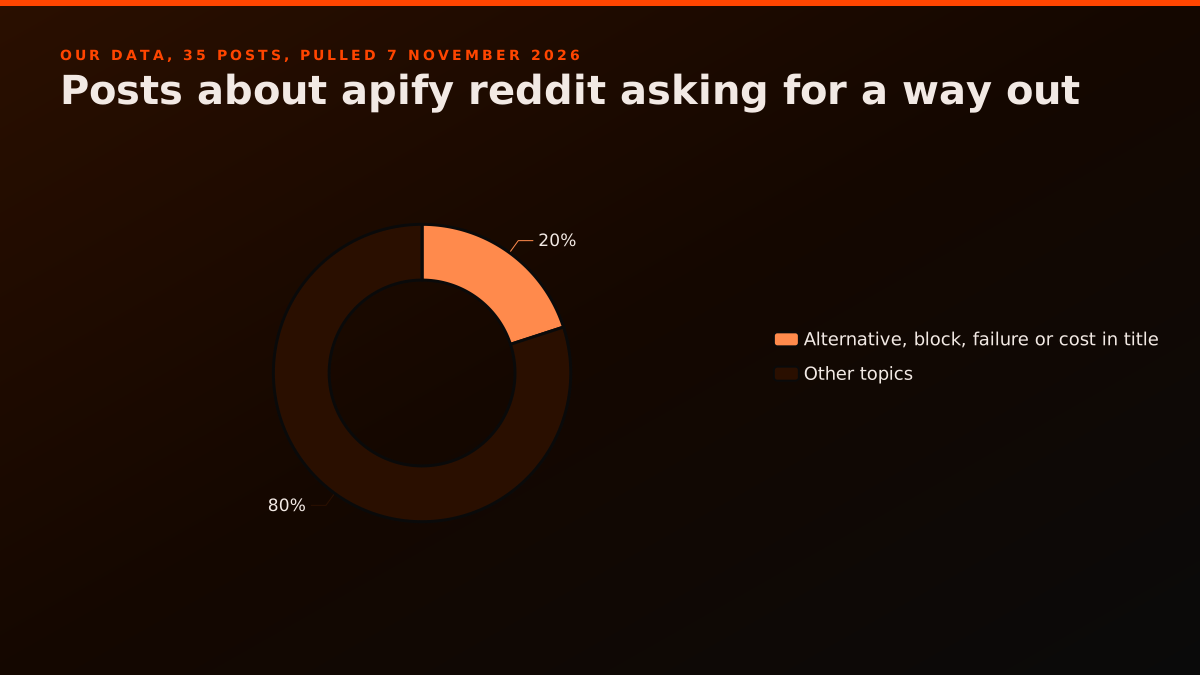
A steady share. We searched Reddit for "apify reddit" over the past year through our own API and checked how many post titles asked for an alternative or reported a block, a failure or rising cost. One in five did, and the r/apify community carries a regular stream of Reddit questions.
We measured it through our own API:
What we measured on Reddit about Apify Reddit actors, 7 November 2026
| Measure | Value | How | Source |
|---|---|---|---|
| Posts returned for apify reddit, past year | 35 | Search, deduplicated by id | measured |
| Of those, titles asking for a way out or reporting a break | 7 (20%) | Title pattern match | derived |
| r/apify posts matching reddit, past year | 29 | Search scoped to r/apify | measured |
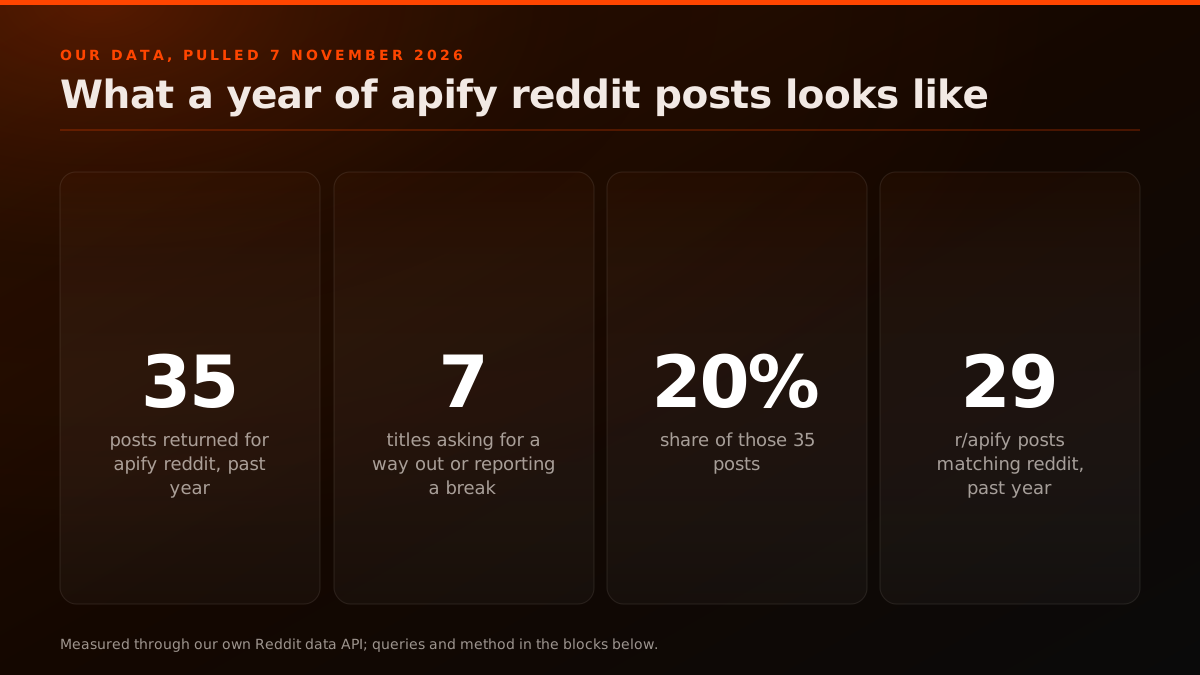
Of the 35 Reddit posts from the past year that our search returned for apify reddit, 20% asked for an alternative or reported a block, a failure or rising cost in the title.
Our data · Dataset:
apify-reddit-posts-past-year· Source: public Reddit posts, pulled through our API · Query:GET /search?q=apify+reddit&sort=relevance&t=year&limit=100· Pulled: 2026-11-07 · n = 35 · Method: share of items whose title matches /(block|alternative|expensive|not work|broken|deprecat|stopp|fail|instead)/i; frame: 35 unique items from 1 page(s), duplicates removed
In the past year, 29 posts in r/apify matched a search for reddit.
Our data · Dataset:
r-apify-reddit-posts-past-year· Source: public Reddit posts, pulled through our API · Query:GET /search?q=reddit&subreddit=apify&sort=new&t=year&limit=100· Pulled: 2026-11-07 · n = 29 · Method: count of items; filtered to subreddit matching /^apify$/i; frame: 29 unique items from 1 page(s), duplicates removed
The titles say it plainly: "Is there any alternative to apify for Reddit?" in r/n8n in July, and "What are you guys using to scrape Reddit at scale? Apify is getting expensive" in r/scrapingtheweb in September. The n8n poster wrote that "Apify's free plan consumes 5$ very quickly":
Is there any alternative to apify for Reddit?
I want to know if there is any alternative to Apify to scrape Reddit at regular interval for specific keywords as Apify's free plan consumes 5$ very quickly.
Should you switch to another Apify actor or leave the actor model?
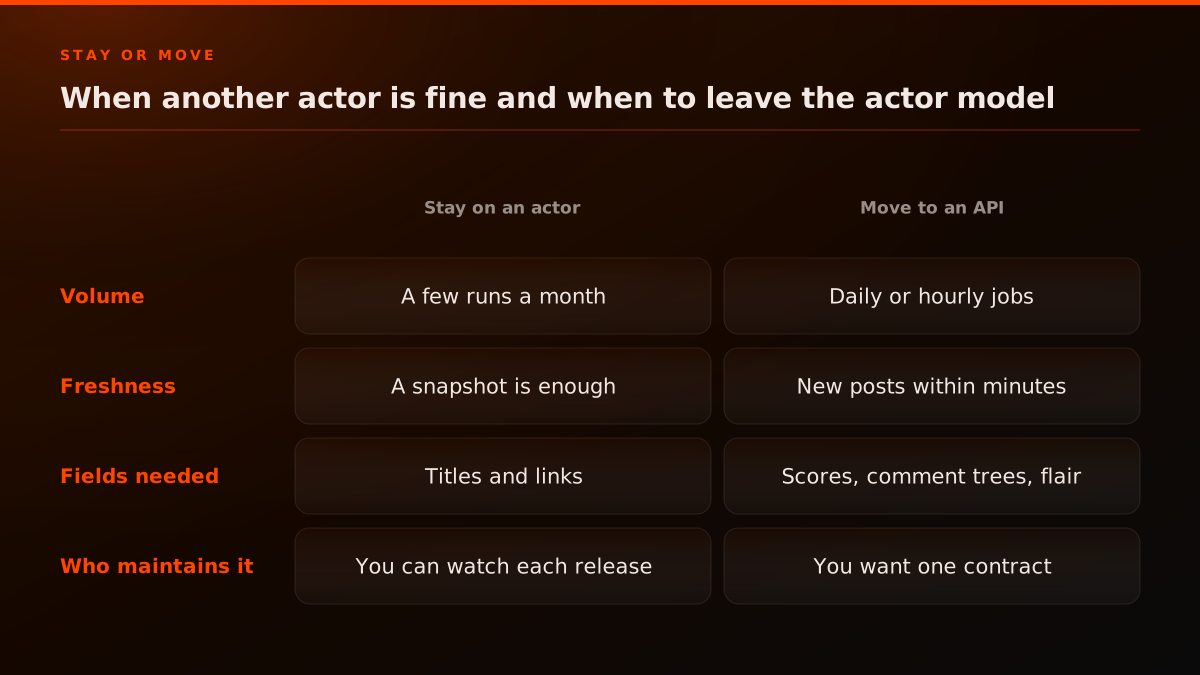
Switch actors if you run a few jobs a month and only need titles and links. Leave the actor model if your job runs daily or hourly, needs scores and full comment trees, or feeds a product that cannot go quiet for a week while a fix ships. The choice is per job, not per company.
Stay or move
When another actor is enough and when to leave the actor model
| Move to an API | Stay on an actor | |
|---|---|---|
| Run cadence | Daily or hourly | A few runs a month |
| Freshness | New posts within minutes | A snapshot is enough |
| Fields | Scores, comment trees, flair | Titles and links |
| Upkeep | One versioned contract | Watch each actor release |
The questions that decide it:
- How often does it run? A monthly research pull tolerates a broken week; a brand alert does not.
- Which fields do you read? If your report sorts by score or comment count, RSS mode is not enough.
- Who notices a zero? If nobody checks, pick the route with the fewest moving parts.
- Who maintains the reader? An actor is one developer's release cycle; an API is a versioned contract.
What are the routes for reading Reddit after November 13?
Four practical ones: another maintained actor, your own logged-in session, a Devvit app that runs inside Reddit, or a keyed data API that returns JSON. Each moves the maintenance burden to a different place, and only one of them puts your own Reddit account on the line.
After November 13
Four ways to keep a Reddit job running after the actor breaks
| Keyed data API | Another Apify actor | Logged-in session | Devvit app | |
|---|---|---|---|---|
| Runs outside Reddit | Yes, your servers | Yes, on Apify | Yes, your servers | No, inside Reddit |
| Who keeps it working | The API provider | The actor developer | You | You, on Reddit's platform |
| Depends on RSS | No | Check the README | No | No |
| Account the reads run as | The provider's | The actor's | Your Reddit account | Your app on Reddit |
| Output | JSON over HTTPS | Apify dataset | Whatever you parse | In-app data |
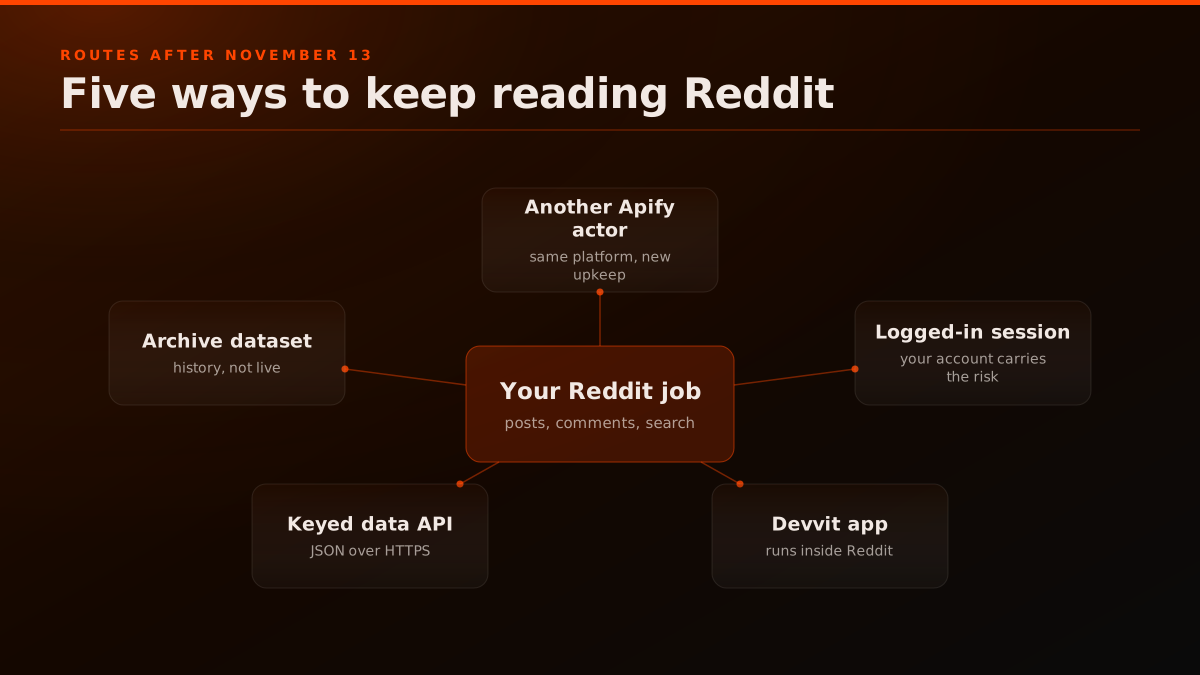
How each one plays out:
- Another actor. Same platform, same dataset format, new developer to trust. Check its README for an RSS default and its changelog for recent block fixes.
- A logged-in session. Developers report that session cookies still work, but the requests then run as your account, which is the account Reddit can limit.
- A Devvit app. Reddit's own route since its 30 September 2026 timeline; right for moderation tools, wrong for an external dashboard. Reddit's own Data API to Devvit migration guide is the starting point, and our Developer Platform migration guide covers which jobs port cleanly.
- A keyed data API. A provider such as redditapis.com returns public posts, comments and search over REST with an API key. Compare providers on our alternatives page.
Historical backfills are a separate question; the Pushshift alternatives guide covers archives.
How do you map Apify actor inputs to a REST API?
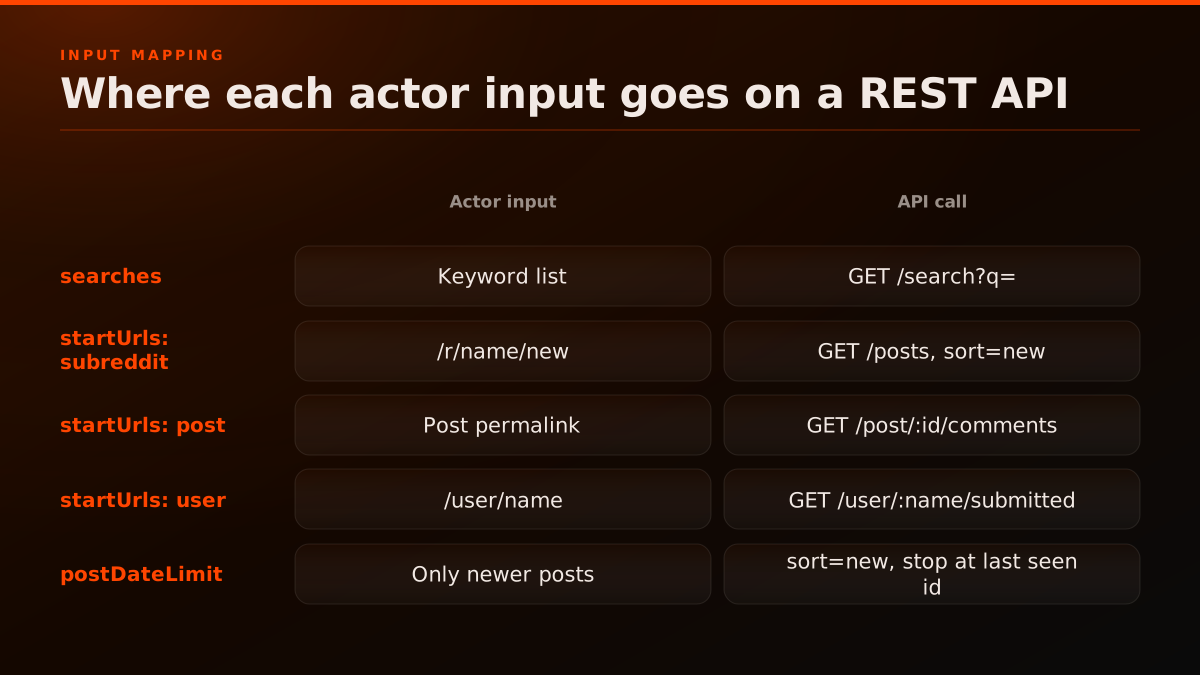
One input at a time. A search term becomes a search call, a subreddit start URL becomes a subreddit listing, a post URL becomes a comment-tree call, and a date limit becomes "sort by new and stop at the last id you stored". The mapping is mechanical once you list your inputs.
| Actor input | What it did | API call |
|---|---|---|
searches |
Keyword search | GET /api/reddit/search?q= |
startUrls with /r/name/new |
Subreddit listing | GET /api/reddit/posts?subreddit=&sort=new |
startUrls with a post permalink |
Post and comments | GET /api/reddit/post/:id/comments |
startUrls with /user/name |
User history | GET /api/reddit/user/:name/submitted |
postDateLimit |
Only newer posts | sort=new, stop at last seen id |
maxItems |
Cap per run | limit plus the after cursor |
How deep a listing reaches, and why Reddit lists stop near 1,000 items on every route, is measured in our limitations guide and the pagination guide. The trudax README says the same thing about its own runs: the 1,000 item ceiling "is not a limitation of the scraper".
The cheapest Reddit API. Try it free.
Reads from $0.0015 per call. $0.50 free credits. No credit card required.
What does the first API call look like?
A single HTTPS request with an API key. The call below replaces a keyword search run: it returns up to 100 posts as JSON with title, author, score, comment count, permalink and an after cursor for the next page, with no actor run, no dataset and no RSS dependency.
curl -sS "https://api.redditapis.com/api/reddit/search?q=your%20brand&sort=new&t=week&limit=100" \
  -H "Authorization: Bearer $REDDITAPIS_KEY"
One keyword search, JSON back, no actor run
endpoint
GET /api/reddit/search
auth
API key
results
Up to 100 per call
Sample request shape. Field list from the endpoint's documented response.
What changes compared with an actor run:
- No run to wait for. The response is the data; there is no dataset to fetch afterwards.
- Paging is explicit. Pass the
aftervalue back to get the next page. - Failures are loud. A bad key or a limit returns an HTTP error, not an empty list.
And the subreddit listing that replaces a start URL:
curl -sS "https://api.redditapis.com/api/reddit/posts?subreddit=redditdev&limit=5&sort=new" \
  -H "Authorization: Bearer $REDDITAPIS_KEY"
If the job is "tell me when a keyword appears", a monitor that pushes matches to a webhook, Slack or Discord replaces the schedule entirely; see the monitoring API page. Python users coming from PRAW can map calls with the PRAW vs REST comparison, and the quickstart gets the first call running.
How do you migrate an n8n, Make or Zapier flow off the actor?
Keep the trigger and the destination, and swap only the middle. Replace the Apify node with an HTTP Request node that calls the API with your key in a header, map the same fields into the same columns, and store the last seen post id so each run handles only new posts.
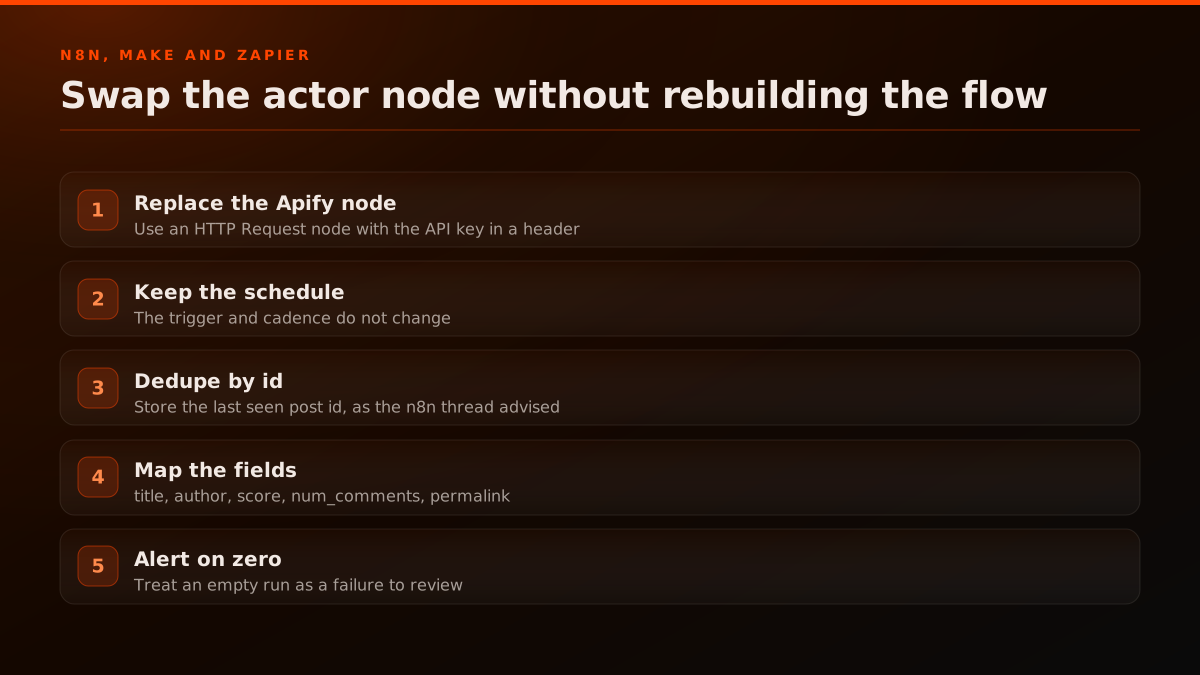
The step list:
- Replace the Apify node with an HTTP Request node and set the
Authorizationheader from a stored credential. - Keep the existing trigger and cadence.
- Store the last seen post id in a sheet, a table or the n8n data store.
- Map
title,author,score,num_commentsandpermalinkinto the old columns. - Add a branch that alerts when a run returns zero items.
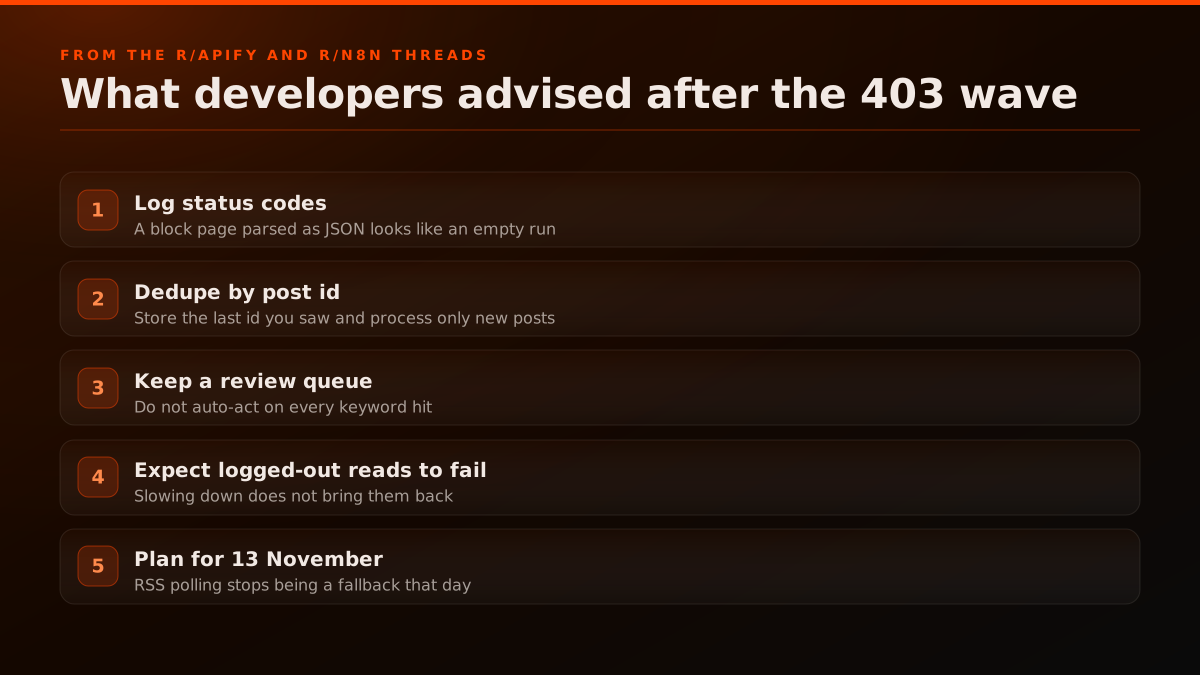
The top answer in the r/n8n thread gave the same advice: "dedupe by post/comment ID" and "keep a review queue instead of auto-acting on every hit". Our n8n guide has the full workflow, and the no-code tools comparison covers Make and Zapier.
Is reading Reddit through a third-party API allowed?
It depends on your use and the provider's terms, so read both. redditapis.com is an independent third-party API, not affiliated with Reddit, Inc., and it does not claim Reddit's approval. Moving off an actor changes who maintains the reader; it does not change your obligations for how you store and use Reddit content.
What to check before you migrate:
- The provider's terms and what it says about how it reads Reddit; ours is on the data access page.
- Reddit's policies for your use, including the Responsible Builder Policy explainer.
- Your retention. Store ids so you can re-fetch and honour deletions.
- Commercial or training use. Answering a question with a live search and training a model are different uses.
Our legal explainer covers the open questions, and the October 31 cutoff guide explains why a new Reddit Data API key is no longer an option for a new project.
Apify actor vs Reddit Data API vs a third-party data API
They answer different questions. An Apify actor is a hosted reader maintained by its developer. The Reddit Data API is Reddit's keyed route, closed to new requests since October 31, 2026. A third-party data API is a keyed REST service that returns Reddit data as JSON.
- Apify actor: dataset output, priced per result or per event, maintained per actor; check for an RSS default.
- Reddit Data API: OAuth, PRAW-compatible, no new requests after October 31, 2026, public access closing in March 2027.
- Third-party data API: REST and JSON, an API key at signup, one versioned contract.
On X, one builder summed up the year as "logged-out .json endpoints went dark in late may":

Om Patel
@om_patel5
reddit shut off logged-out access to its data, and it took out half my product overnight over half of all calls to my mcp server were reddit tools. every one of them started returning 403 so i rebuilt it in a day, and now it works better than before heres what happened and how… Show more

Our comparison with the official API goes field by field, and the scraping hub covers every method in one place.
Migration checklist
Do this before November 13, 2026. List every Reddit run you own, find the ones that use RSS or logged-out reads, decide per job whether to switch actors or move to an API, run the new route beside the old one for a week, then retire the schedule.
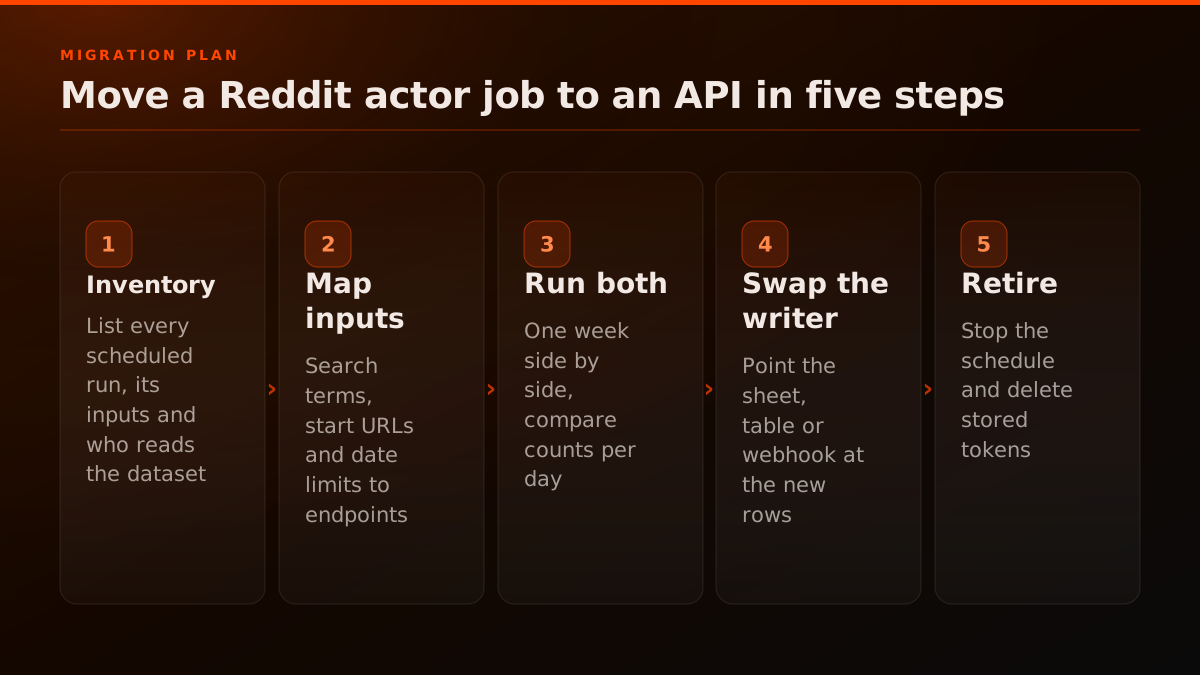
The checklist:
- Inventory: every scheduled actor run, its inputs, its destination and who reads it.
- Flag RSS runs: any run with includeMediaLinks off on a trudax actor.
- Flag silent zeros: any day in the last six months with zero items.
- Decide per job: another actor for light, occasional pulls; an API for daily, field-heavy or customer-facing jobs.
- Run side by side: one week, compare item counts per day.
- Retire: stop the old schedule and remove stored Reddit cookies or tokens.
When you are ready to test the API route, signup issues a key, the pricing page shows the cost per call, and the API documentation lists every endpoint.
Where these numbers come from.
Each row is a figure in this post and the artefact it was read from. Reddit's access rules and the third-party archives around them keep moving, so check the date on a source before you build against it.
- Apify Store: trudax/reddit-scraper
- Store page read 7 November 2026: Deprecated label, 15K total users, 483 monthly active users, 2.6 rating from 30 reviews, from $0.10 per 1,000 results, README on RSS default mode.
- Apify Store: trudax/reddit-scraper changelog
- Release notes including 5.0.0 (31 May 2026, address 403 errors) and 5.9.0 (5 November 2026, session rotation after increased blocks).
- Apify Store: trudax/reddit-scraper-lite
- Store page read 7 November 2026: 52,365 total users, 8,622 monthly active users, 4.35 rating, from $3.40 per 1,000 results.
- Apify Store: apify/reddit-scraper
- Apify-maintained actor read 7 November 2026: 479 total users, 336 monthly users, from $2.50 per 1,000 posts.
- r/modnews: Continuing our infrastructure updates
- Reddit admin post of 30 September 2026 ending RSS support on 13 November 2026.
- r/redditdev: Moving Data API apps to the Developer Platform
- Reddit admin timeline of 30 September 2026: new API requests close 31 October 2026, public access closes March 2027.
- r/apify: Blocked reddit scraping
- Thread of 30 May 2026 and its replies on logged-out .json reads returning 403.
Frequently asked questions.
Yes. The trudax/reddit-scraper actor carries a Deprecated label on its Apify Store page, which we read on 7 November 2026. The page shows 15K total users, 483 monthly active users and a 2.6 rating from 30 reviews, and it links to alternative actors. The separate Reddit Scraper Lite actor by the same developer was not marked deprecated when we checked. Why the break happened is covered in our .json endpoint guide.
Most likely because Reddit started refusing logged-out reads in late May 2026. The r/apify thread 'Blocked reddit scraping' is dated 30 May 2026, and the trudax actor's 5.0.0 release on 31 May 2026 reads 'address 403 errors'. If the run finishes but returns zero items, log the HTTP status: a 403 block page is HTML, and a JSON parser can turn it into an empty list. The .json endpoint guide covers the change.
It was listed as active on 7 November 2026, with 52,365 total users and 8,622 monthly active users. Its README says that with includeMediaLinks off, the default, it uses RSS feeds, and Reddit stops supporting RSS on November 13, 2026. Test a default run after that date before you rely on it, and turn on media links if you need scores and comment counts. The RSS shutdown explainer lists what else changes that day.
Reddit stops supporting RSS feeds that day, per its 30 September 2026 r/modnews post. Any actor run that reads Reddit through RSS loses that source. The trudax README says its default mode reads RSS feeds and omits upVotes, numberOfComments, media URLs and flair, so a default run is the one most exposed. The RSS shutdown explainer covers what else breaks.
It depends on volume and freshness. For a few runs a month, another maintained actor is the smallest change. For daily or hourly jobs, a keyed data API that returns posts, comments and search as JSON removes the actor upkeep. Compare the routes in our Reddit API alternatives page and the cost math in Reddit API pricing vs Apify.
Not reliably. Developers in the r/apify thread report that logged-out requests to .json endpoints return 403, with one writing on 19 August 2026 that it 'isn't rate limiting, it's an auth gate'. A logged-in session can still read, but the account then carries the risk. Our .json explainer lists every current route.
Swap the Apify node for an HTTP Request node that calls a Reddit data API with your key in a header, keep the same trigger and schedule, store the last seen post id to dedupe, and map title, author, score, num_comments and permalink into the same columns. Our n8n guide has the full workflow.
Read the provider's terms and Reddit's own policies for your use. redditapis.com is an independent third-party API, not affiliated with Reddit, Inc., and it does not claim Reddit approval. What it reads and which calls it bills is on the data access page, and the legal questions are in is scraping Reddit legal.
Keep reading.
Continue exploring related pages.
Reddit API documentation
The complete 2026 reference: auth, all 76 endpoints, and code.
Get a Reddit API key
Instant bearer token, no waitlist and no enterprise contract.
Reddit Responsible Builder Policy
Why Reddit denies API applications, and the managed REST bypass.
Reddit API use cases
14 use cases from AI training to brand monitoring and DMs.
Reddit Search API
Search posts, comments, users, and communities over one REST endpoint.
Reddit MCP server
Wrap the REST API as MCP tools for Claude, Cursor, and any MCP client.
Reddit MCP hub
Install tabs for every client, the full tool table, pricing and fixes.
Reddit API for AI agents
Live Reddit context for tool calls, MCP servers, and RAG pipelines.
Redditapis pricing
Endpoint-level costs and quick monthly totals - reads from $0.0015 / call.
Reddit API cost calculator
Estimate monthly spend using your request volume.
Reddit API guides and tutorials
Tutorials, walkthroughs, and API deep-dives for developers.
Reddit API alternatives
Evaluate alternatives by cost model, limits, and integration fit.
Cheap Reddit API
The cheapest way to get Reddit data: $0.0015 per call, no contract, no minimum.
Official Reddit API vs Redditapis
Access, setup, rate limits, and pricing, side by side.
PRAW alternative
A hosted Reddit REST API for any language, no app registration or OAuth.
Reddapi alternative
A maintained Reddit REST API with published pricing and write endpoints.
Reddit comment scraper alternative
The raw comment API: search and filter comments, historical and live, clean JSON.
Reddit scraper API
Hosted scraper API vs building your own: no proxies to manage, clean JSON.
RapidAPI Reddit alternative
A direct, maintained Reddit API with published pricing and write endpoints.
Bright Data Reddit alternative
A purpose-built Reddit API vs a general scraping platform: structured JSON, plus writes.
ScraperAPI Reddit alternative
A Reddit-native API vs a generic HTML fetcher: auth and pagination handled, typed JSON.
TikHub alternative
TikHub's Reddit surface is read-only; get comment, vote, and DM endpoints too.
EnsembleData alternative
No $100/month floor: pay per call from $0.0015, plus write, vote, and DM endpoints.
Scrape Creators alternative
7 read-only Reddit endpoints vs a dedicated API with real write, vote, and DM paths.
FetchLayer alternative
Posts, comments, and search only; add vote, comment, and DM over the same REST auth.
PullPush alternative
PullPush is free but volunteer-run and goes offline for reindexing; a maintained REST API that stays up.
Reddit monitoring API
Build your own keyword and brand-mention monitor: search, comment search, and subreddit streams over REST.
F5Bot vs Redditapis
F5Bot's Slack and Discord delivery needs its $49.99/mo Gold tier; Redditapis includes it from $19/mo.
Syften vs Redditapis
Syften caps you at 100 to 500 results a day; Redditapis allows 10,000 a day per monitor at the entry plan.
Octolens vs Redditapis
Octolens meters by mention with overage fees; Redditapis is flat-priced by subreddit slot from $19/mo.
Affiliate program
Earn 20% lifetime commissions - capped at $5,000/yr.
Reddit Vote API tutorial
Upvote and downvote a post programmatically via the REST API.
Reddit Data API: REST, no PRAW
REST endpoints for Reddit data with no PRAW and no OAuth dance.
Reddit scraping benchmarks
Real throughput, error rates, and cost benchmarks for Reddit scraping.
Reddit API answers
Direct answers on cost, access, rate limits, endpoints, and auth.
How much the Reddit API costs
Per-call pricing from $0.0015 a read, with $0.50 in free credits.
Reddit API in Python
One requests call with a bearer token, no PRAW and no OAuth flow.
Reddit shadowban checker
Check if a Reddit account is shadowbanned in seconds, free and no login.
Subreddit stats checker
See any subreddit's live subscriber count, active users, and age, free and no login.
Similar reads.
More guides on the Reddit API, scraping, pricing, and MCP servers.
Reddit RSS Feeds End November 13, 2026: What Breaks and What Replaces Them
Reddit stops supporting RSS feeds on November 13, 2026. What breaks, what Reddit offers moderators instead, the 2027 API dates, and how to replace a feed.
Reddit API Pricing vs Apify: 2026 Cost and Throughput Guide
Reddit API pricing vs Apify scrapers in 2026, a side by side developer comparison covering per call cost, rate limits, compliance, and per workload guidance.
Reddit Lead Generation in 2026: Find Buying-Intent Threads Through an API
Reddit lead generation that holds up: find the threads where buyers ask for a tool, monitor them through an API, and answer in public. Measured on 2026 data.
Reddit Comment IDs Are Now 13 Characters and Out of Order: What Breaks in Your Code
Reddit's new comment IDs are 13 characters and no longer increasing. When the change went live, what it breaks in your code, and the fix for each case.
Reddit Closed New Data API Requests on October 31: What to Do If You Never Applied
Reddit stopped accepting new Data API requests on October 31, 2026. What closed, why the request form kept failing, and how a new project reads Reddit now.
Reddit Data for Market Research After ChatGPT's Citation Drop (2026)
ChatGPT now cites Reddit about 88% less than six months ago. Here is what Reddit data is still worth pulling, and how to mine it through an API.
How to Estimate Your Reddit API Bill: a Per-Call Cost Model in Python
A per-call Reddit API cost model in Python: price every read, write and DM, then size the monthly bill for a keyword monitor, a RAG refresh and a reply bot.
Reddit API Limitations in 2026: What the API Will Not Do, Beyond Rate Limits
Every Reddit API ceiling that is not a rate limit: the 1,000-item listing cap we measured, search depth, deleted content, access approval and commercial terms.