Reddit Data for Market Research After ChatGPT's Citation Drop (2026)
ChatGPT now cites Reddit about 88% less than six months ago. Here is what Reddit data is still worth pulling, and how to mine it through an API.
ChatGPT now cites Reddit far less than it did six months ago. A study of 66.6 million logged-out answers, reported in October 2026, found the model went from citing Reddit in about 1 in 5 answers to about 1 in 43, a drop of roughly 88%. If your plan for Reddit was to be quoted inside an AI answer, that plan got much weaker. The data underneath Reddit did not.
TL;DR: ChatGPT's citations of Reddit fell about 88% from March to September 2026, per Ahrefs, as the model shifted to primary sources and because only 14.4% of answers ran a web search. Reddit's value moved from being cited to being read: demand, sentiment and trends are still there as first-party data. We pulled the 100 newest r/SEO posts about AI Overview through our API and 47% have a question mark in the title, and half of the posts naming ChatGPT do too.
TL;DR
An Ahrefs study of 66.6 million logged-out ChatGPT answers, reported on 12 October 2026, found the model cut how often it cites Reddit from about 1 in 5 answers in March to about 1 in 43 in September, a drop of about 88%, as it shifted to citing primary sources over aggregators. Only 14.4% of those answers ran a web search at all. That changes what Reddit is worth to a marketer: not a surface to get quoted in, but a source of first-party demand and sentiment data you pull yourself. The questions, complaints and comparisons people write in public are still there, and an API returns them as JSON with no app-review queue. We pulled the 100 newest r/SEO posts about AI Overview through our own API and 47% have a question mark in the title; half of the newest posts naming ChatGPT do too. That is demand you can read directly.
This is an independent explainer from redditapis.com, a third-party API that is not affiliated with Reddit, Inc. It is about what Reddit data is worth now, and how to pull it. How request-based access to Reddit's own Data API works is covered in our Reddit Data API overview; this post is about the value of the data itself once you have a way to read it.
What did the Ahrefs study actually find?
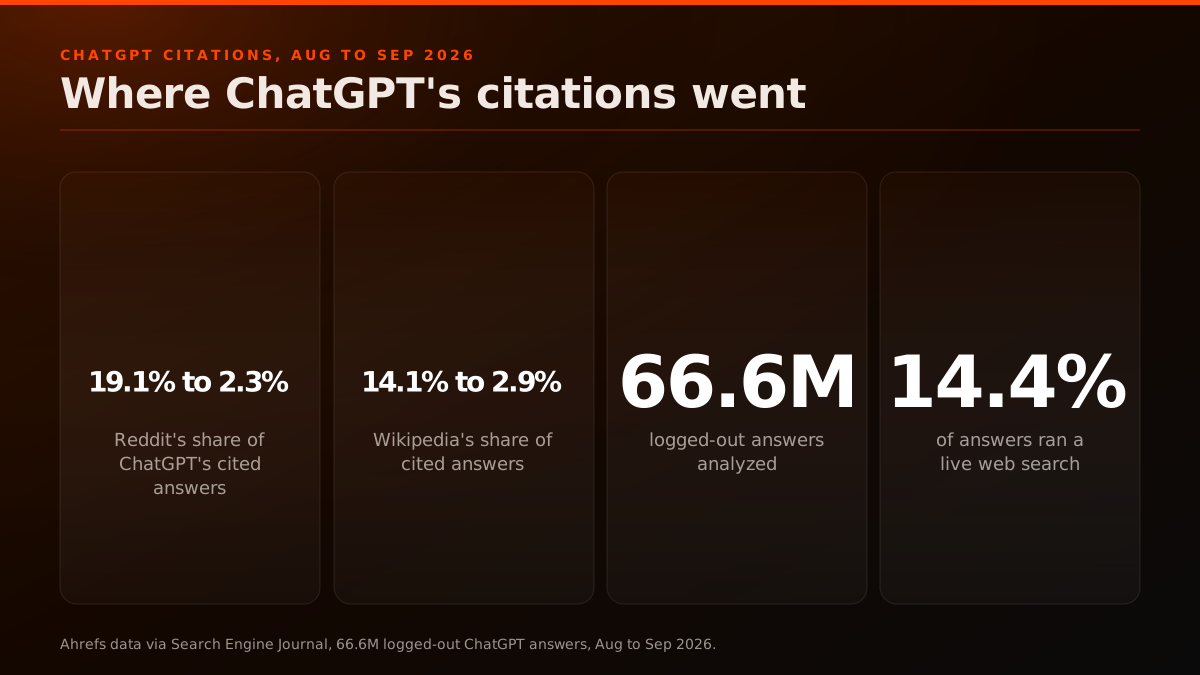
That ChatGPT cites Reddit far less than it used to, and moved toward primary sources. Across 66.6 million logged-out answers from August and September 2026, Ahrefs found Reddit citations down about 88% over six months, with only 14.4% of answers running a web search at all. The headline is a shift in what the model links, not a fall in what Reddit knows.
Three figures anchor the finding:
- 66.6 million answers were analyzed, from August and September 2026.
- About 88% fewer of them cited Reddit than six months earlier.
- 14.4% of them ran a live web search at all.
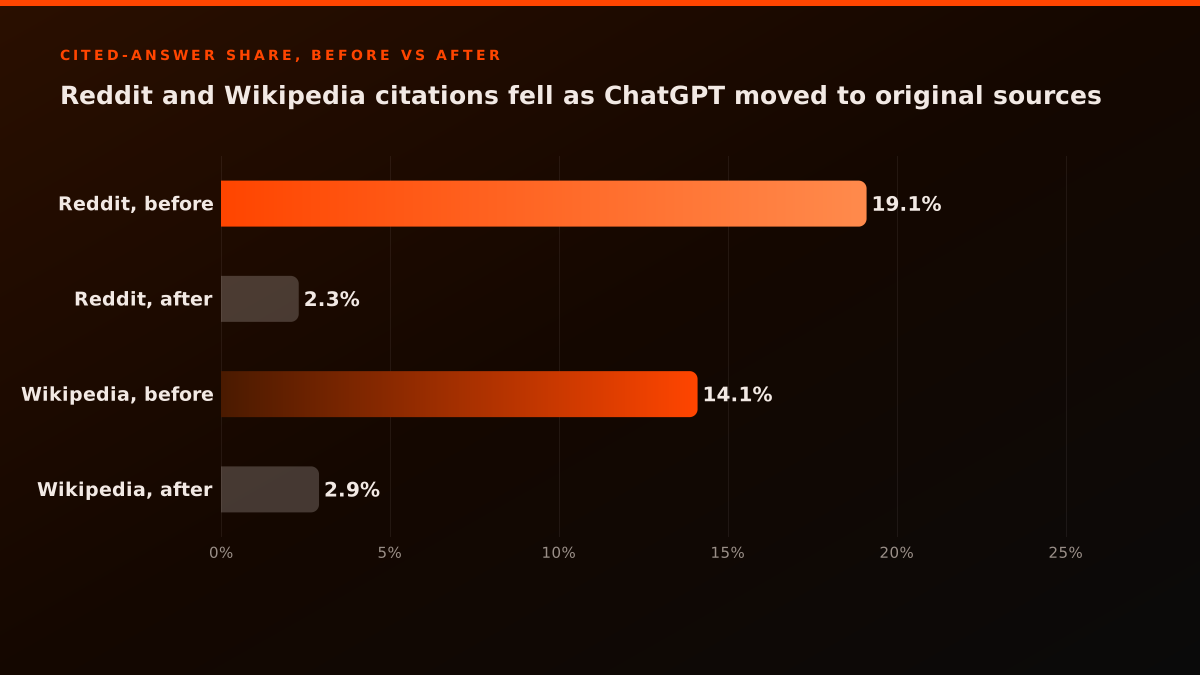
The share figures, as Search Engine Journal reported them from Ahrefs' data:
How far ChatGPT's citations of Reddit and Wikipedia fell, March to September 2026
| Source | Cited-answer share, March | September | Six-month change | Source |
|---|---|---|---|---|
| 19.1% | 2.3% | down about 88% | published | |
| Wikipedia | 14.1% | 2.9% | down about 80% | published |
The figures were echoed in independent coverage of the study, which repeated the 66.6 million sample and the 14.4% web-search share. They travelled fast among marketers the week they landed. One post summed up the study and the caveat in a line:

Stefano Galloni
@achille610
Ahrefs analyzed 66.6M ChatGPT answers: 14.4% triggered web search, averaging 1.6 queries when search occurred. Its separate Reddit dataset showed citations down 88% in six months. Useful signals—but dataset boundaries matter. #AIVisibility #SEO #ChatGPT https://t.co/UNVsfG9Xa2 h… Show more

Another marketer flagged the Reddit-specific figure the same day:

Yuri Moreno
@yurimoreno
Ahrefs tracked 66.6M ChatGPT answers: only 14.4% trigger a web search. And when they do, 76% of site: queries aim at brand sites, not Reddit (citations down 88% in 6 months). https://t.co/m99A6QkVJ5
Ahrefs: the model moved to primary sources
Why did ChatGPT stop citing Reddit so often?
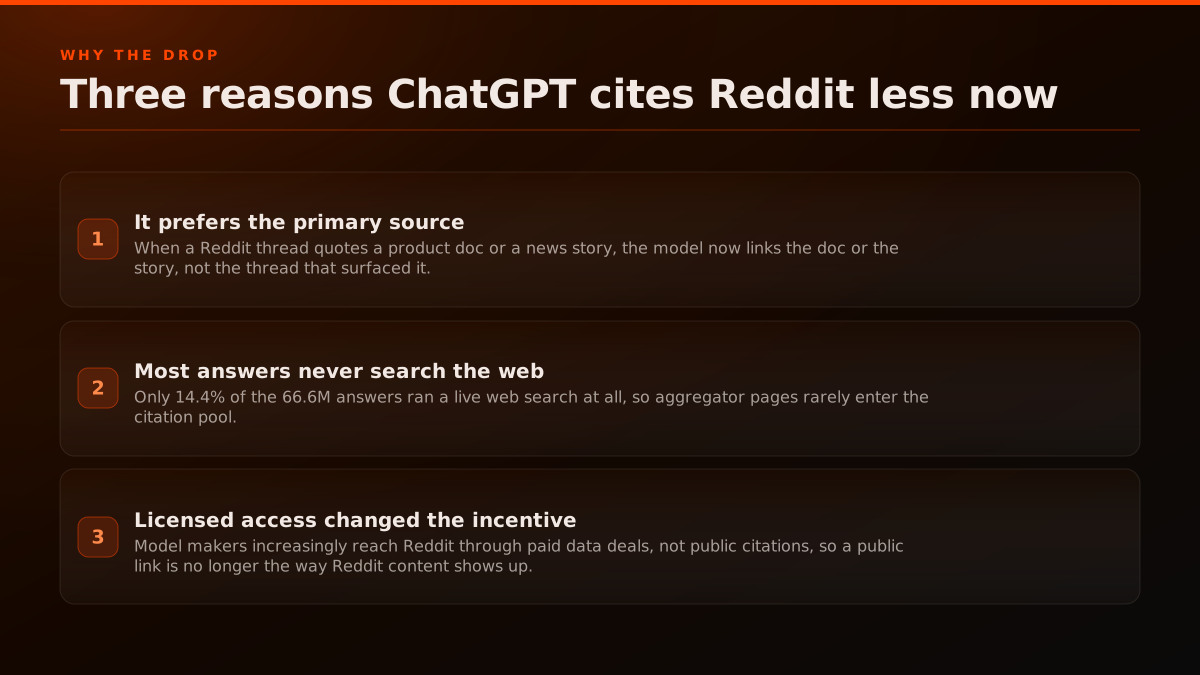
Because the model shifted to citing the primary source a thread points at, and because most answers never search the web. When a Reddit comment quotes a product doc or a news story, ChatGPT now tends to link the doc or the story, not the thread. Licensed data access changed the incentive too, so a public citation is no longer the way Reddit content shows up.
The three reasons, in short:
- It links the primary source a thread quotes, not the thread itself.
- Most answers never run a web search, so aggregator pages rarely enter the pool.
- Licensed access replaced the public citation as the way Reddit content reaches a model.
The drop was not unique to Reddit. Ahrefs' chart shows Wikipedia citations down 80% and YouTube down 27% over the same window, which is the signature of a model-wide move toward original sources rather than anything specific to one aggregator.
Does a lower citation rate mean Reddit data lost value?
No. A citation rate measures how often a model links Reddit inside an answer. It says nothing about whether the posts are useful. The value simply moved: from a surface you optimized to be quoted on, to a source you read directly. The questions, complaints and comparisons people write in public are first-party demand and sentiment data, and they are still there.
What actually changed:
- The citation was a model's ranking, which you do not set.
- The data is a public post, which you read on your own terms.
- The demand and sentiment underneath are first-party and unchanged.
The shift
Reddit as a data source versus Reddit as a citation target
| As a data source | As a citation target | |
|---|---|---|
| What you optimize | The questions you read | Being quoted in an answer |
| Who controls the outcome | You, on your servers | The model's ranking |
| Is it measurable | Yes, a number you pull | Rarely, and not stably |
| Affected by the citation drop | No, posts stay public | Yes, down about 88% |
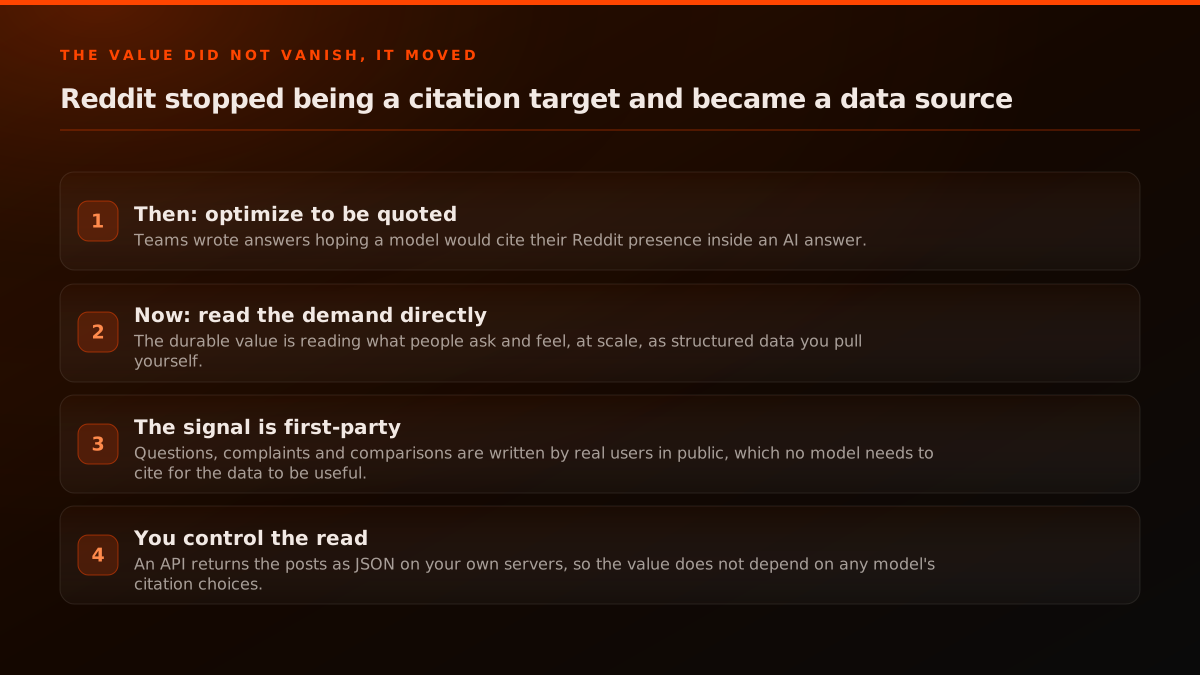
The point is control. A citation depends on a model's ranking, which you do not set and which just moved 88%. A data pull depends on a public post and an API key, which you do control. That is the difference between chasing a number someone else sets and reading a number you take yourself.
What Reddit data is still worth pulling?
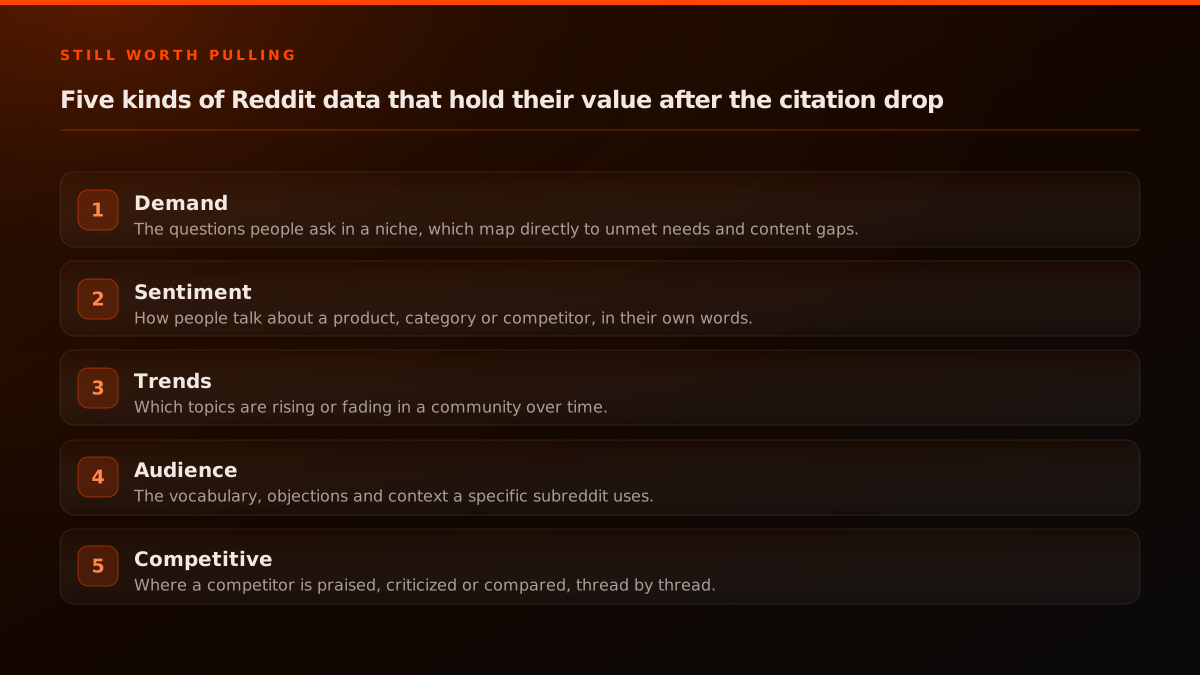
Five kinds, and none of them depend on a citation. Demand is the questions a community asks. Sentiment is how people describe a product or a competitor. Trends are which topics rise and fade. Audience is the vocabulary and objections of a specific subreddit. Competitive signal is where a rival is praised or criticized, thread by thread.
The five reads at a glance:
- Demand: the questions a community is asking right now.
- Sentiment: how people describe a product or a rival.
- Trends: which topics are rising and which are fading.
- Audience: the vocabulary and objections of a subreddit.
- Competitive: where a rival is praised or criticized.
Each maps to an endpoint and a question:
What Reddit data to pull for which research question
| Data type | What you read | Endpoint | Question it answers | Source |
|---|---|---|---|---|
| Demand | Question titles in a community | /api/reddit/search | What are people asking about? | derived |
| Sentiment | Comment language on a brand | /api/reddit/search/comments | How do people describe it? | derived |
| Trends | Post counts over time | /api/reddit/search | Which topics are rising? | derived |
| Audience | Top posts in a subreddit | /api/reddit/sub/:name/top | What words does this audience use? | derived |
Demand and sentiment have their own deep guides: the Reddit sentiment analysis guide covers reading comment language, and the audience research guide covers who a subreddit actually is. For topics rising and falling, the trending-topics guide covers the trend read.
Start building with Redditapis
Reads $0.0015, votes $0.005, writes $0.012, DMs $0.025. $0.50 free credits.
Where is the AI search demand actually showing up?
On Reddit, in the open, as questions. The communities arguing about AI search are writing their unmet needs down. We pulled the 100 newest r/SEO posts that match a search for AI Overview through our own API and counted how many ask a question in the title.
47% of the 100 newest r/SEO posts that match a search for AI Overview ask a question in the title.
Our data · Dataset:
reddit-ai-overview-demand-rseo· Source: public Reddit posts, pulled through our API · Query:reddit_search {"limit": 100, "q": "AI Overview", "sort": "new", "subreddit": "SEO"}· Pulled: 2026-10-19 · n = 100 · Method: share of items whose title matches /?/i; frame: 100 unique items from 1 page(s), deduplicated by id
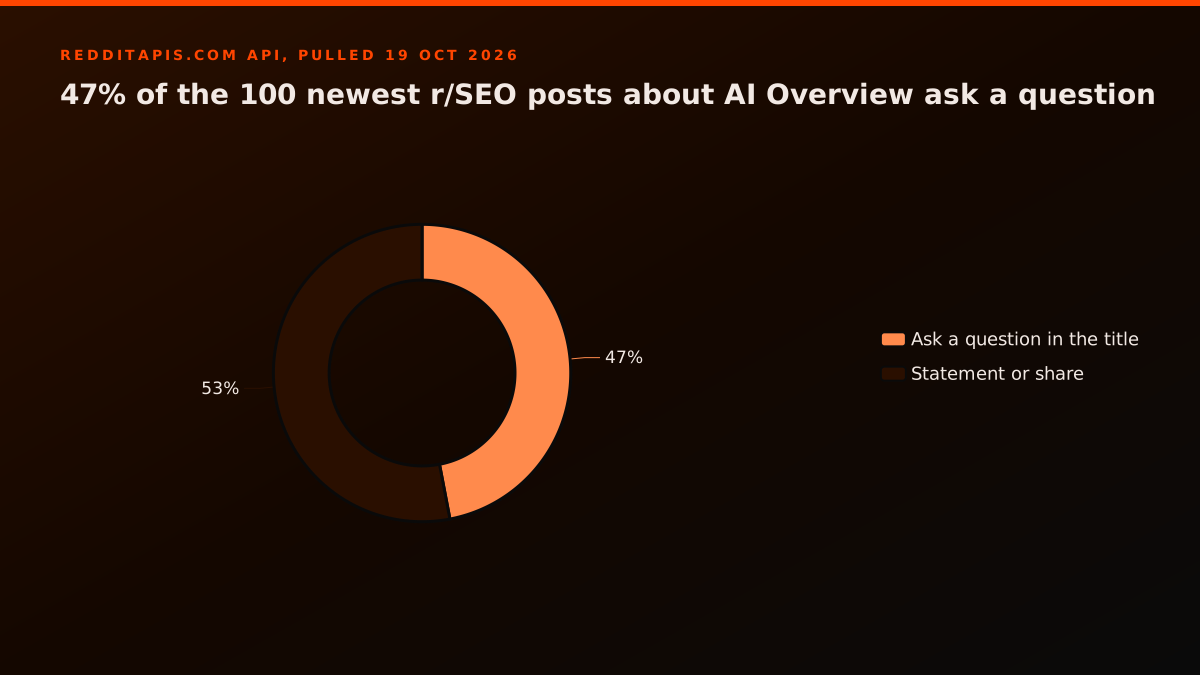
Nearly half of a live community's recent posts on this topic are literally questions. That is demand you can read without guessing. The same shift shows up in other communities too: a founder in r/SaaS described the behaviour driving it:
If I'm trying to understand a topic, compare products, or get an overview of something, I almost automatically open ChatGPT first.
Has anyone here actually seen AI search reduce their Google traffic yet?
I'm asking because my own search habits have changed quite a bit over the last year. I still use Google whenever I'm looking for a specific website or navigating somewhere. But if I'm trying to understand a topic,…
Does the demand come with any depth?
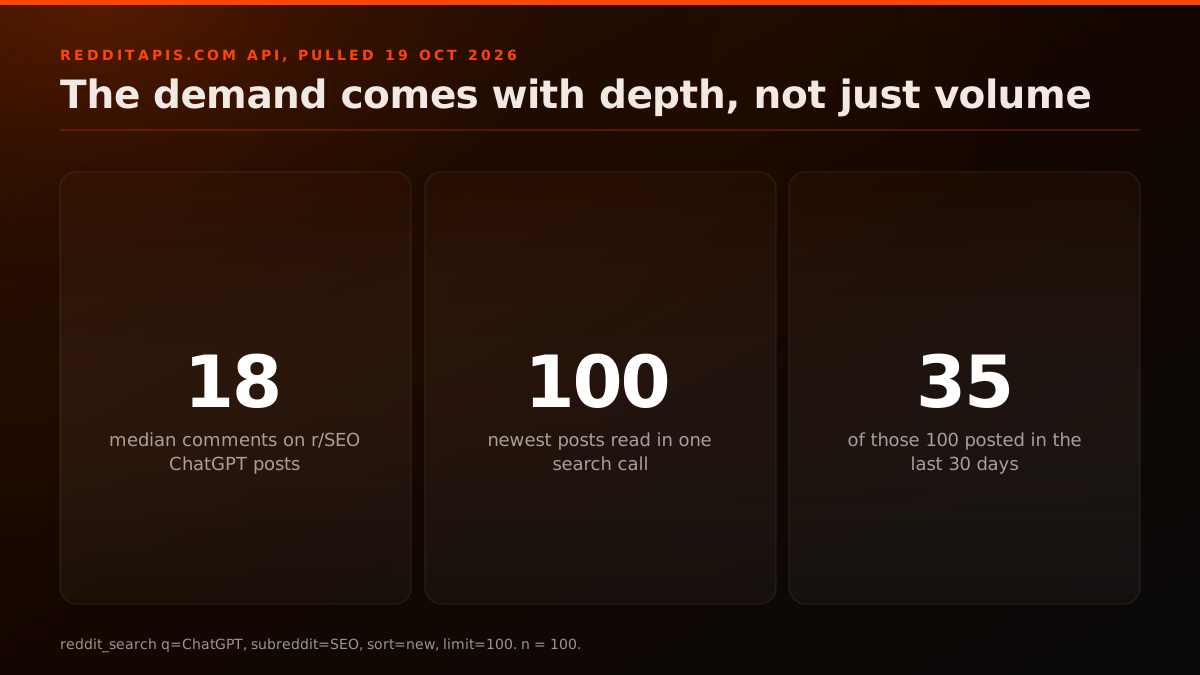
Yes, and it is ChatGPT-specific, not only about Google's AI Overviews. When we pull the 100 newest r/SEO posts that name ChatGPT, half have a question mark in the title, so the demand shows up under the exact term this post is pegged to. Each post is also a thread of replies where sentiment and context live, and the median one was an 18-comment discussion.
50% of the 100 newest r/SEO posts mentioning ChatGPT have a question mark in the title.
Our data · Dataset:
reddit-chatgpt-threads-rseo· Source: public Reddit posts, pulled through our API · Query:reddit_search {"limit": 100, "q": "ChatGPT", "sort": "new", "subreddit": "SEO"}· Pulled: 2026-10-19 · n = 100 · Method: share of items whose title matches /?/i; frame: 100 unique items from 1 page(s), deduplicated by id
The median post among the 100 newest r/SEO posts mentioning ChatGPT carried 18 comments.
Our data · Dataset:
reddit-chatgpt-threads-rseo· Source: public Reddit posts, pulled through our API · Query:reddit_search {"limit": 100, "q": "ChatGPT", "sort": "new", "subreddit": "SEO"}· Pulled: 2026-10-19 · n = 100 · Method: median of comments; frame: 100 unique items from 1 page(s), deduplicated by id
Founders are already asking the measurement question out loud. One r/SaaS thread compared tools for tracking AI-search and LLM referral traffic:
Which tools would you recommend for AI search / LLM traffic tracking?
I'm seeing more & more of ChatGPT / Perplexity / Gemini, etc as a source of sessions within Clarity, but I feel like I'm missing a bigger picture. What are the tools that you're using and find valuable. EDIT: I went…
Why can you not just read ChatGPT's citations back from its API?
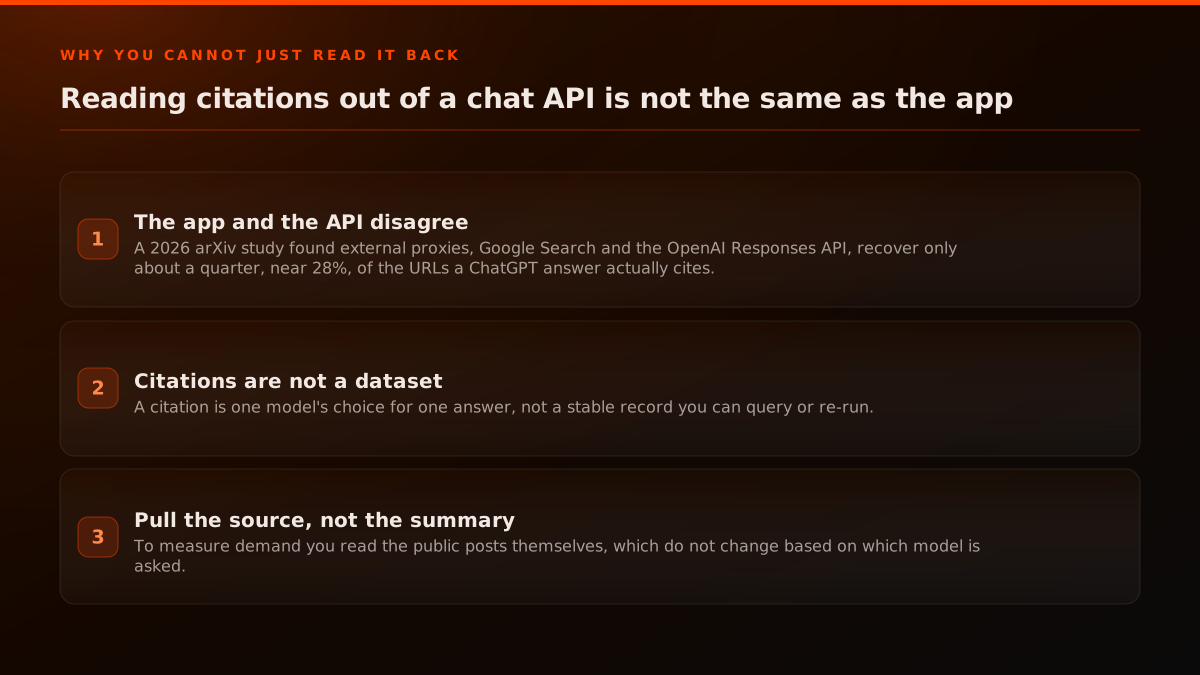
Because a chat API does not reproduce what the app cited. A 2026 arXiv paper, Understanding ChatGPT Citations, found that external proxies, Google Search and the OpenAI Responses API, recover only about a quarter, near 28%, of the URLs a ChatGPT answer actually cites. A citation is one model's choice for one answer, not a dataset.
Two reasons it does not work:
- The app and the API disagree: proxies recover only about a quarter, roughly 26 to 28%, of the cited URLs.
- A citation is one answer's choice, not a stable record you can query or re-run.
An API answer is not a citation record
So the reliable move is the opposite of reconstructing citations: read the public posts directly. They do not change based on which model is asked, and they are the thing the citations were pointing at in the first place.
How do you mine Reddit demand through an API?
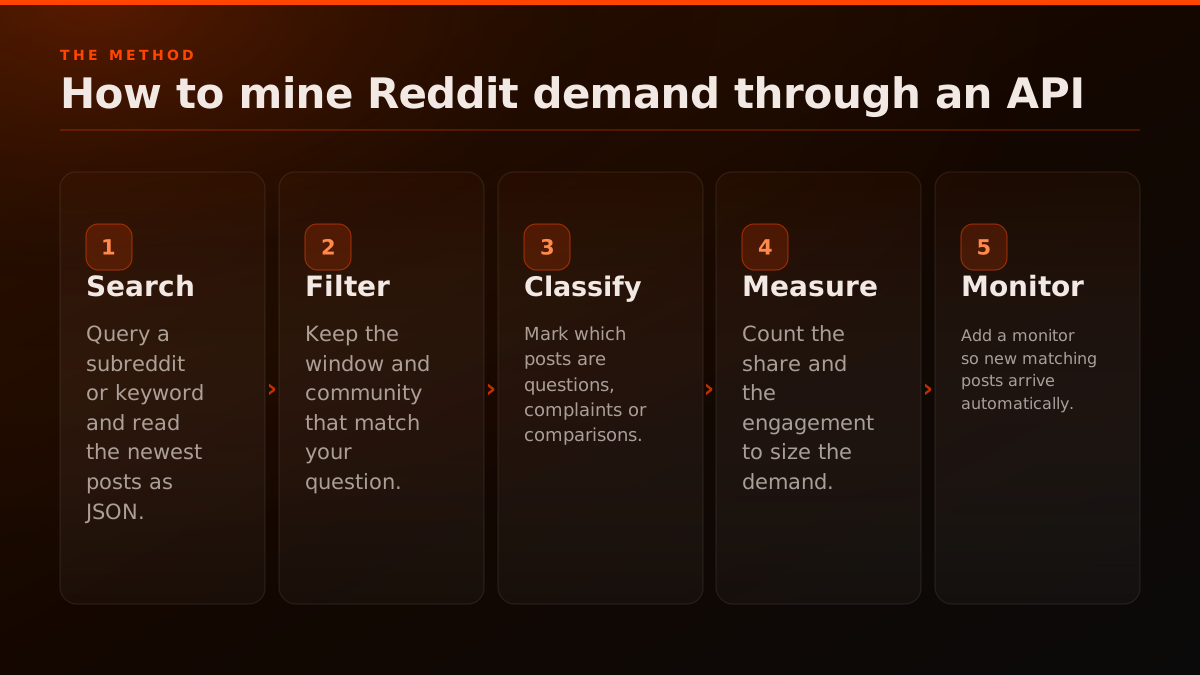
In five steps: search, filter, classify, measure, monitor. You query a subreddit or a keyword and read the newest posts as JSON, keep the window and community that match your question, mark which posts are questions or complaints, count the share, then add a monitor so new matching posts arrive on their own.
The five steps:
- Search a subreddit or keyword for the newest posts.
- Filter to the window and community you care about.
- Classify each post as a question, complaint or comparison.
- Measure the share and the engagement.
- Monitor so new matches arrive without polling.
Every post comes back structured, so the classifying and counting are yours to run:
The first call a demand pull makes
endpoint
GET /api/reddit/search
auth
API key
returns
JSON
Sample request shape. Field list from the endpoint's documented response.
The first call looks like this:
curl -sS "https://api.redditapis.com/api/reddit/search?q=AI%20Overview&subreddit=SEO&sort=new&limit=100" \
  -H "Authorization: Bearer $REDDITAPIS_KEY"
Which read do you want: demand, sentiment, or trend?
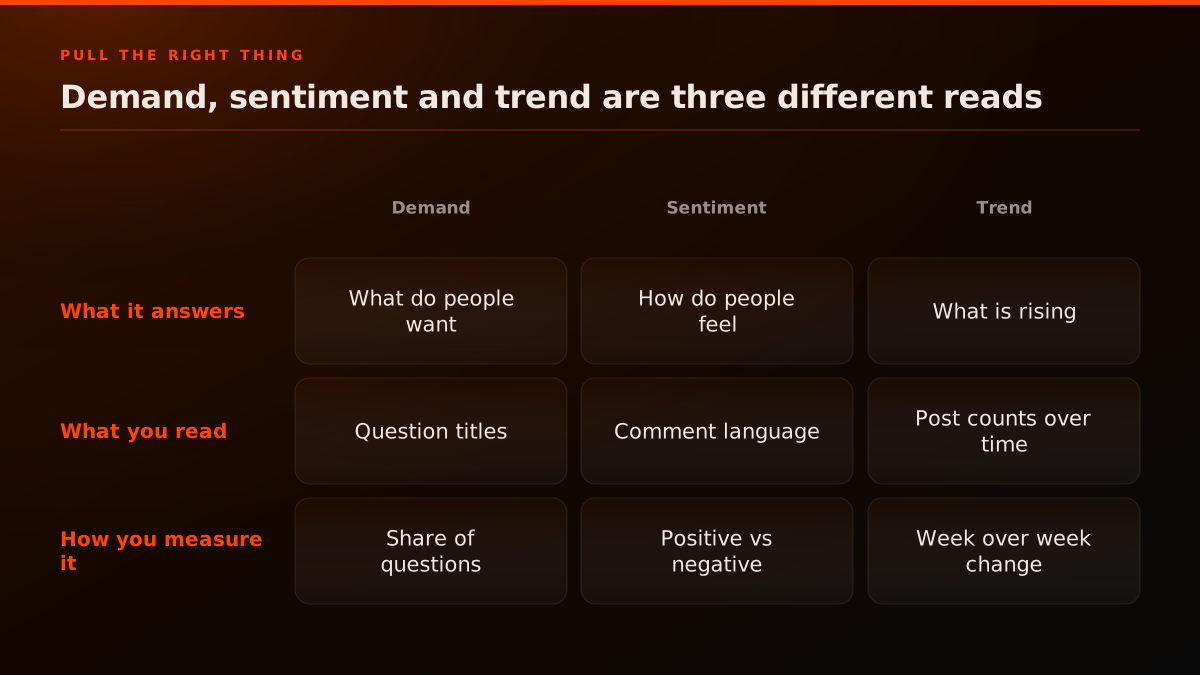
They are three different questions and three different reads. Demand asks what people want and you read it from question titles. Sentiment asks how people feel and you read it from comment language. Trend asks what is rising and you read it from post counts over time. Picking the wrong one is the common mistake.
Match the read to the question:
- Demand reads question titles for what people want.
- Sentiment reads comment language for how people feel.
- Trend reads post counts over time for what is rising.
Pull the right thing
Demand, sentiment and trend are three different reads
| Demand | Sentiment | Trend | |
|---|---|---|---|
| What it answers | What do people want | How do people feel | What is rising |
| What you read | Question titles | Comment language | Post counts over time |
| Endpoint | /api/reddit/search | /api/reddit/search/comments | /api/reddit/search |
Sentiment, in particular, is where the citation drop barely matters: how people describe your brand is written in comments, in public, every day. A founder in r/SaaS keeping a running log of what triggers AI citations put the habit plainly:
I've been keeping a messy log of what seems to trigger ai citations vs what doesnt.
anyone figured out how to actually show up in perplexity/chatgpt search?
honestly been hitting rank 1 for some of our big keywords lately but the traffic is basically... dead? i think the "google rank 1 trap" is hitting us hard. ai overviews are just answering everything before people even…
The cheapest Reddit API. Try it free.
Reads from $0.0015 per call. $0.50 free credits. No credit card required.
A worked example: sizing demand for a topic
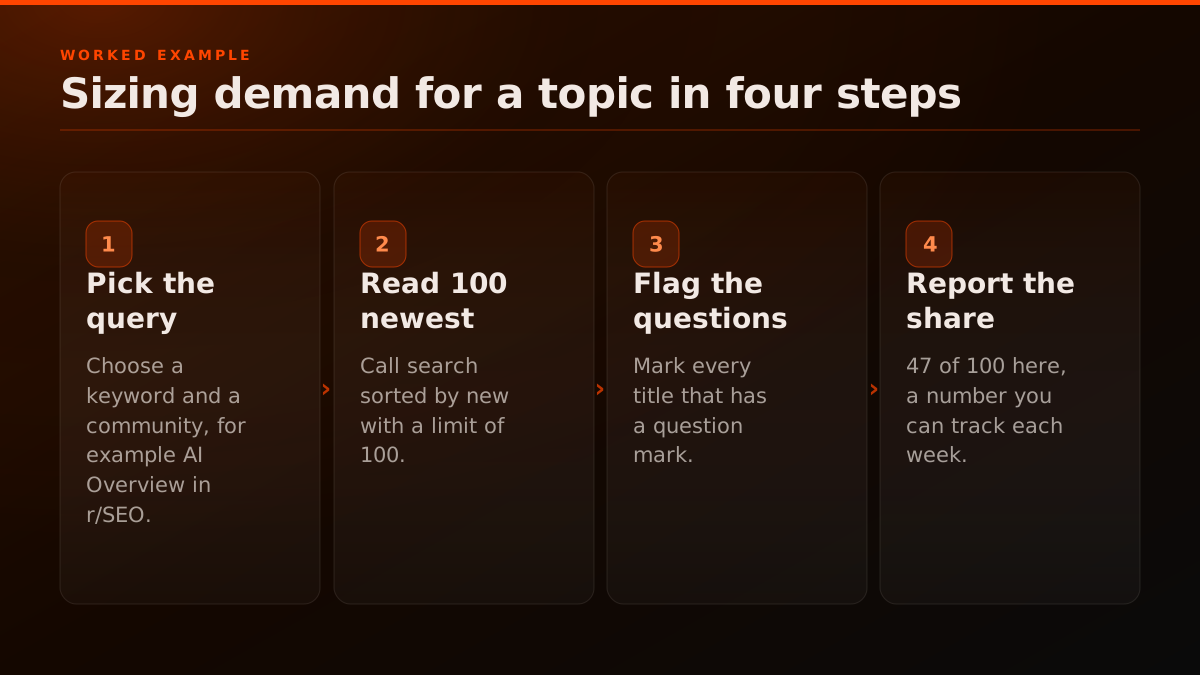
Four steps turn a vague sense of demand into a number you can track. Pick a query, such as AI Overview in r/SEO. Read the 100 newest posts. Flag every title that has a question mark. Report the share, which was 47 of 100 here. Run it again next week and you have a trend line instead of a snapshot.
The four steps:
- Pick a query, such as AI Overview in r/SEO.
- Read the 100 newest posts in one call.
- Flag every title that has a question mark.
- Report the share, 47 of 100 here, and track it weekly.
Reading the same community over time is how you catch a shift early. This short walks through checking and improving AI visibility, which is the sibling job to measuring demand:
What should SEO and GEO teams do now?
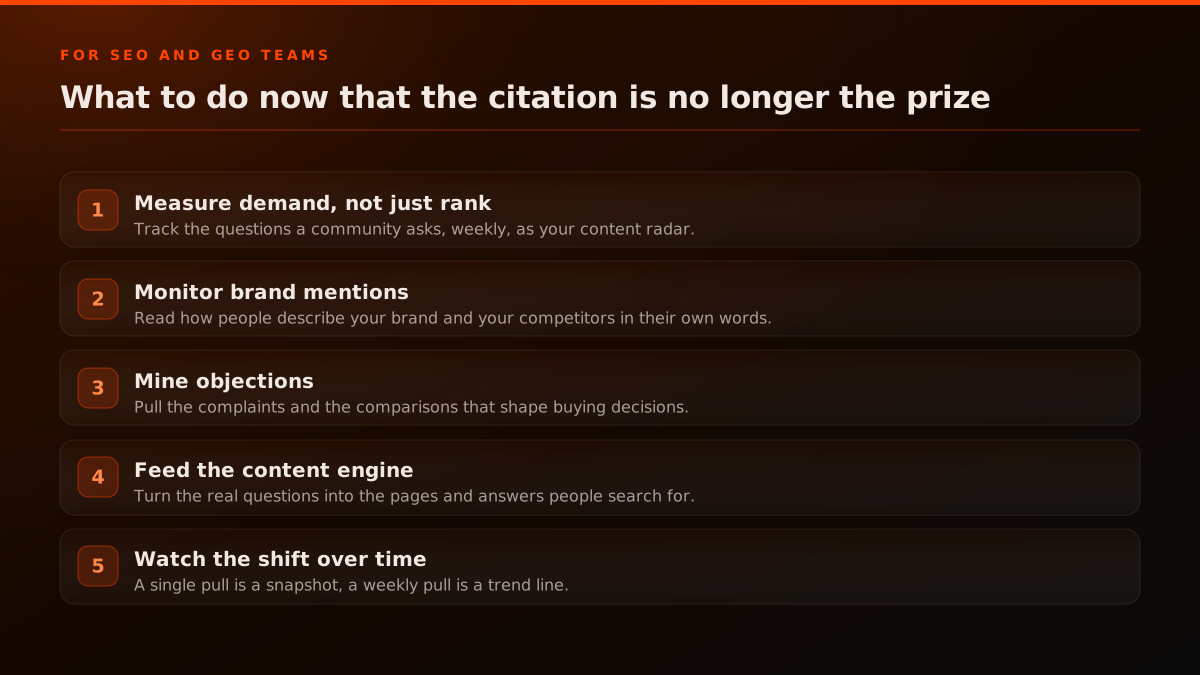
Measure demand, not just rank. Track the questions a community asks, weekly, as a content radar. Monitor how people describe your brand and your competitors. Mine the objections and comparisons that shape buying. Feed the real questions into the pages people search for. A single pull is a snapshot, a repeated pull is a trend line.
Five moves:
- Measure demand weekly, not just rank.
- Monitor how people describe your brand and competitors.
- Mine the objections and comparisons that shape buying.
- Feed the real questions into the pages people search for.
- Watch the shift over time, not once.
The teams feeling this most are the ones asked for AEO or GEO work without a measurement plan. One r/SaaS playbook thread put "track AI mentions and citations, not only rankings" at the top of its list, which is exactly the read this post is about:
GEO + SEO for AI search in 2026 what’s actually working? (quick playbook)
Hey everyone, I’ve been testing how brands show up in AI search (ChatGPT/Claude/Perplexity/AI Overviews) and it’s clearly different from classic SEO. Here’s the simple playbook I’m using right now: 1. Write for…
Mine the data, or chase the citation?
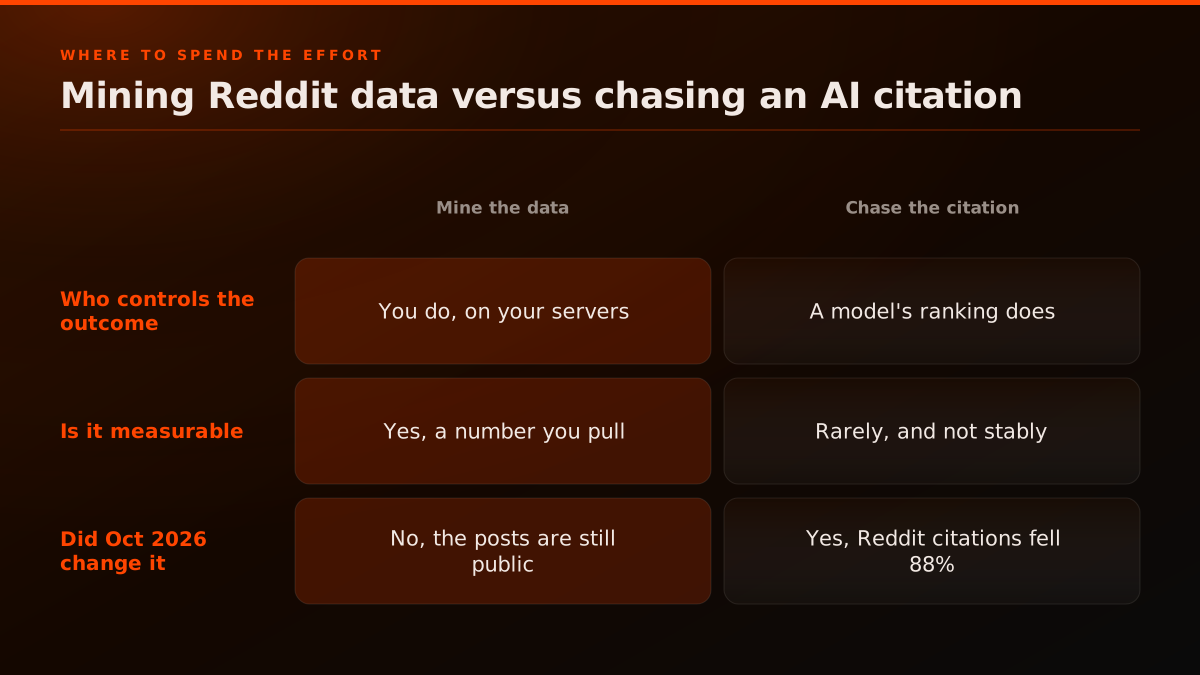
Mine the data. Chasing an AI citation means optimizing for a number a model sets and just cut by 88%. Mining the data means reading a number you take yourself, from posts that stay public whatever the model does. One you control and can measure, the other you do not.
The difference in three lines:
- A citation is a number a model sets, and it just fell about 88%.
- A data pull is a number you take, from posts that stay public.
- One you control and can measure; the other you do not.
For the AI side of this, where Reddit data feeds a retrieval pipeline rather than a research dashboard, the Reddit as a RAG data source guide covers ingestion and retrieval.
What to do this quarter
List the questions you need answered, pick the two or three subreddits where your audience actually posts, pull a baseline of the shares you care about, set a monitor so new matches arrive on their own, and review weekly against that baseline. It is a small amount of setup for a demand radar that does not depend on anyone's citations.
The plan:
- List the demand and sentiment questions you need answered.
- Pick the two or three subreddits where your audience posts.
- Pull a baseline of the shares you care about.
- Set a monitor, then review weekly against the baseline.
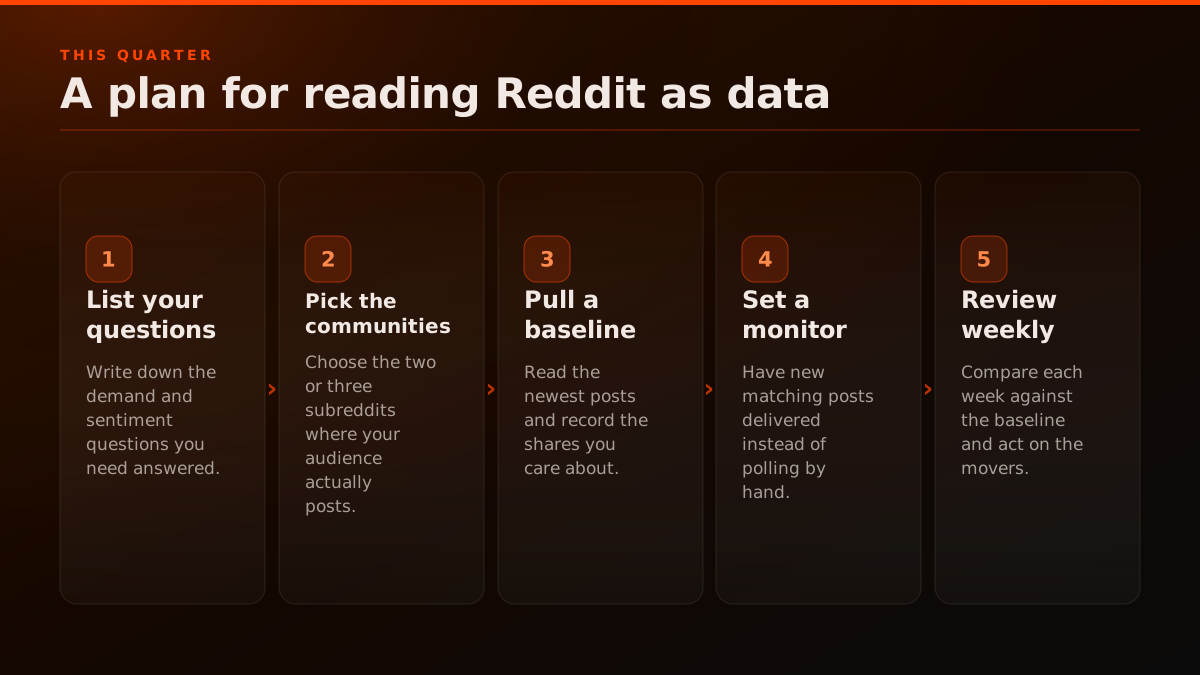
Monitors do the watching for you: the monitoring API pushes new matching posts to a webhook, Slack or Discord, so a weekly review becomes reading what already arrived.
Reading Reddit data you can trust
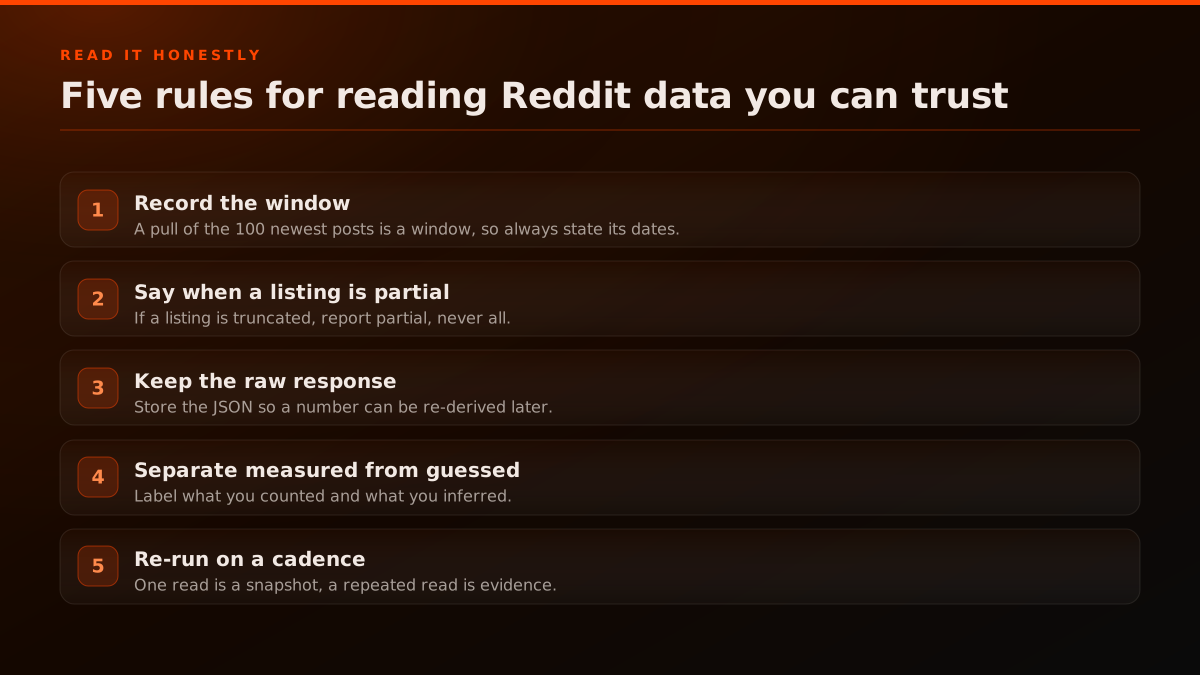
Record the window, because a pull of the 100 newest posts is a window, not a census. Say when a listing is partial rather than calling it complete. Keep the raw JSON so a number can be re-derived. Separate what you counted from what you inferred. Re-run on a cadence, because one read is a snapshot and a repeated read is evidence.
Five rules:
- Record the window of every pull, with its dates.
- Flag a partial listing as partial, never as complete.
- Keep the raw JSON so a number can be re-derived later.
- Separate what you counted from what you inferred.
- Re-run on a cadence so a snapshot becomes a trend.
When you are ready to pull a baseline, the quickstart runs the first call, signup issues a key, and the API documentation lists every endpoint and field.
Where these numbers come from.
Each row is a figure in this post and the artefact it was read from. Reddit's access rules and the third-party archives around them keep moving, so check the date on a source before you build against it.
- Ahrefs: How ChatGPT Does Query Fan-Out (15 Million Queries Studied)
- Ahrefs study of 66.6M logged-out GPT-5.6 answers, 12 October 2026. Reports ChatGPT's Reddit citations down 88% and that only 14.4% of answers ran a web search.
- Search Engine Journal: ChatGPT favors primary sources over aggregators
- Coverage of the Ahrefs study, 12 October 2026. States Reddit was cited in 19.1% of US ChatGPT answers in March and 2.3% in September, and Wikipedia 14.1% to 2.9%.
- Relevant Audience: ChatGPT query fan-out citations, Ahrefs study
- Independent coverage of the same Ahrefs study, 13 October 2026, repeating the 66.6M sample and the 14.4% web-search share.
- arXiv 2610.15382: Understanding ChatGPT Citations
- Jiang et al, 11 October 2026. Finds external proxies recover only about 26% to 28% of the URLs a ChatGPT answer cites.
- r/SaaS: Has anyone here actually seen AI search reduce their Google traffic yet?
- Public r/SaaS thread, 4 August 2026, 12 comments. A founder asking for real data on whether AI search is cutting informational traffic.
- r/SaaS: Anyone figured out how to actually show up in perplexity/chatgpt search?
- Public r/SaaS thread, 16 March 2026, 37 comments. A founder keeping a log of what triggers AI citations versus what does not.
- r/SaaS: Which tools would you recommend for AI search / LLM traffic tracking?
- Public r/SaaS thread, 29 May 2025, 54 comments. Founders comparing ways to track AI-search and LLM referral traffic.
- r/SaaS: GEO + SEO for AI search in 2026, what's actually working?
- Public r/SaaS thread, 20 January 2026, 16 comments. A playbook thread that lists tracking AI mentions and citations, not only rankings.
Frequently asked questions.
No. The citation rate fell about 88% from March to September 2026, per Ahrefs, but that measures how often a model links Reddit inside an answer, not how useful the underlying posts are. The value moved from being quoted to being read: the questions, complaints and comparisons people write are first-party demand and sentiment data, and an API returns them as JSON whether or not any model cites them. See our Reddit data API overview.
Five kinds hold their value: demand (the questions a community asks), sentiment (how people describe a product or competitor), trends (which topics are rising), audience (the vocabulary and objections of a specific subreddit), and competitive signal (where a rival is praised or criticized). Each is a read you run yourself, so none of it depends on a model's citation choices. The sentiment guide and the audience research guide go deeper.
Pick a community and a keyword, read the newest posts as JSON, then classify which are questions, complaints or comparisons and measure the share. A single search call returns titles, authors, scores, comment counts and permalinks, so you can size demand and track it over time. Our quickstart runs the first call, and the method is in the body of this post.
Not reliably. A 2026 arXiv study found external proxies, Google Search and the OpenAI Responses API, recover only about a quarter, near 28%, of the URLs a ChatGPT answer actually cites. A citation is one model's choice for one answer, not a stable dataset you can query. To measure demand you read the public posts themselves, which do not change based on which model is asked. Our quickstart runs that first read.
Ahrefs attributes it to a shift toward primary sources: when a thread quotes a doc or a news story, the model now links the doc or the story. Only 14.4% of the 66.6 million answers studied ran a web search at all, so aggregator pages rarely enter the citation pool. Model makers also reach Reddit increasingly through paid data deals rather than public links, which our Reddit data API overview covers.
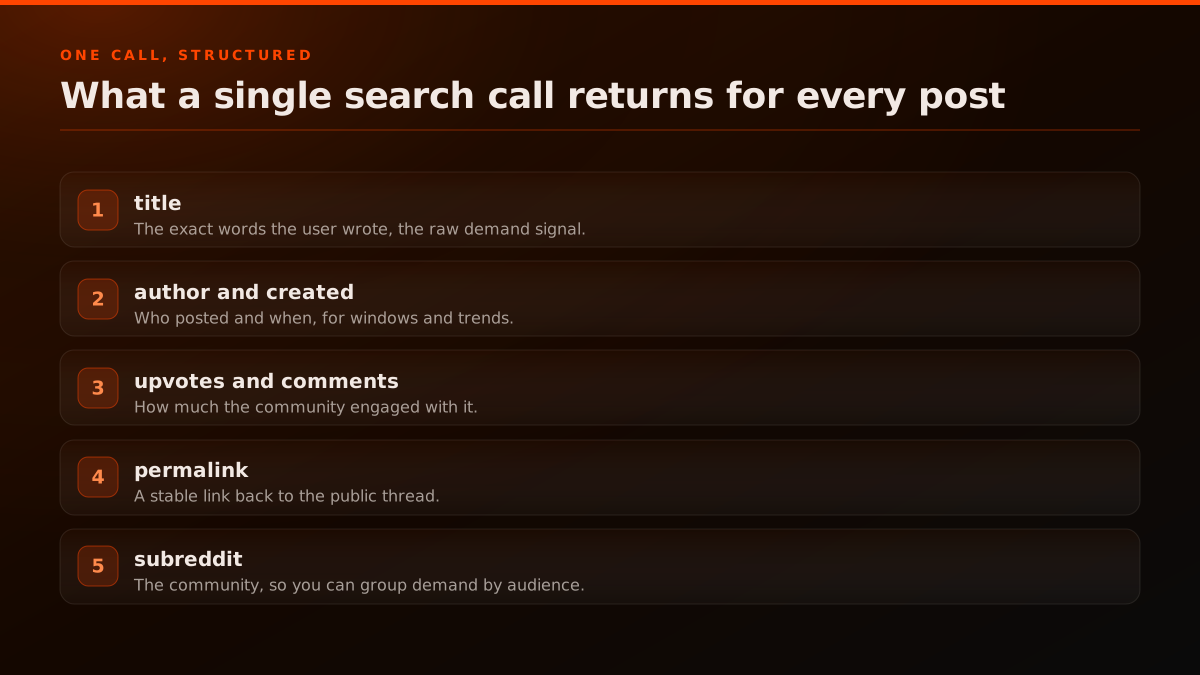
For every post it returns the title, the author, the created date, the upvotes and comment count, the permalink and the subreddit, up to 100 results per call with an after cursor for the next page. The title is the raw demand signal, the engagement numbers size it, and the permalink links back to the public thread. The quickstart runs the first call, and the full API documentation lists every field.
No. redditapis.com is an independent, third-party REST API for Reddit posts, comments, search and monitors, not affiliated with Reddit, Inc. It returns public Reddit data as JSON over HTTP with an API key at signup and no app-review queue. Pricing is on the pricing page.
Keep reading.
Continue exploring related pages.
Reddit API documentation
The complete 2026 reference: auth, all 59 endpoints, and code.
Get a Reddit API key
Instant bearer token, no waitlist and no enterprise contract.
Reddit Responsible Builder Policy
Why Reddit denies API applications, and the managed REST bypass.
Reddit API use cases
14 use cases from AI training to brand monitoring and DMs.
Reddit Search API
Search posts, comments, users, and communities over one REST endpoint.
Reddit MCP server
Wrap the REST API as MCP tools for Claude, Cursor, and any MCP client.
Reddit MCP hub
Install tabs for every client, the full tool table, pricing and fixes.
Reddit API for AI agents
Live Reddit context for tool calls, MCP servers, and RAG pipelines.
Redditapis pricing
Endpoint-level costs and quick monthly totals - reads from $0.0015 / call.
Reddit API cost calculator
Estimate monthly spend using your request volume.
Reddit API guides and tutorials
Tutorials, walkthroughs, and API deep-dives for developers.
Reddit API alternatives
Evaluate alternatives by cost model, limits, and integration fit.
Cheap Reddit API
The cheapest way to get Reddit data: $0.0015 per call, no contract, no minimum.
Official Reddit API vs Redditapis
Access, setup, rate limits, and pricing, side by side.
PRAW alternative
A hosted Reddit REST API for any language, no app registration or OAuth.
Reddapi alternative
A maintained Reddit REST API with published pricing and write endpoints.
Reddit comment scraper alternative
The raw comment API: search and filter comments, historical and live, clean JSON.
Reddit scraper API
Hosted scraper API vs building your own: no proxies to manage, clean JSON.
RapidAPI Reddit alternative
A direct, maintained Reddit API with published pricing and write endpoints.
Bright Data Reddit alternative
A purpose-built Reddit API vs a general scraping platform: structured JSON, plus writes.
ScraperAPI Reddit alternative
A Reddit-native API vs a generic HTML fetcher: auth and pagination handled, typed JSON.
TikHub alternative
TikHub's Reddit surface is read-only; get comment, vote, and DM endpoints too.
EnsembleData alternative
No $100/month floor: pay per call from $0.0015, plus write, vote, and DM endpoints.
Scrape Creators alternative
7 read-only Reddit endpoints vs a dedicated API with real write, vote, and DM paths.
FetchLayer alternative
Posts, comments, and search only; add vote, comment, and DM over the same REST auth.
PullPush alternative
PullPush is free but volunteer-run and goes offline for reindexing; a maintained REST API that stays up.
Reddit monitoring API
Build your own keyword and brand-mention monitor: search, comment search, and subreddit streams over REST.
F5Bot vs Redditapis
F5Bot's Slack and Discord delivery needs its $49.99/mo Gold tier; Redditapis includes it from $19/mo.
Syften vs Redditapis
Syften caps you at 100 to 500 results a day; Redditapis allows 10,000 a day per monitor at the entry plan.
Octolens vs Redditapis
Octolens meters by mention with overage fees; Redditapis is flat-priced by subreddit slot from $19/mo.
Affiliate program
Earn 20% lifetime commissions - capped at $5,000/yr.
Reddit Vote API tutorial
Upvote and downvote a post programmatically via the REST API.
Reddit Data API: REST, no PRAW
REST endpoints for Reddit data with no PRAW and no OAuth dance.
Reddit scraping benchmarks
Real throughput, error rates, and cost benchmarks for Reddit scraping.
Reddit API answers
Direct answers on cost, access, rate limits, endpoints, and auth.
How much the Reddit API costs
Per-call pricing from $0.0015 a read, with $0.50 in free credits.
Reddit API in Python
One requests call with a bearer token, no PRAW and no OAuth flow.
Reddit shadowban checker
Check if a Reddit account is shadowbanned in seconds, free and no login.
Subreddit stats checker
See any subreddit's live subscriber count, active users, and age, free and no login.
Similar reads.
More guides on the Reddit API, scraping, pricing, and MCP servers.
Reddit Stops New Data API Requests on October 31: What to Do If You Have Not Applied
Reddit stops accepting new Data API requests on October 31, 2026. What closes, why the request form keeps failing, and how a new project reads Reddit after.
Reddit RSS Feeds End November 13, 2026: What Breaks and What Replaces Them
Reddit stops supporting RSS feeds on November 13, 2026. What breaks, what Reddit offers moderators instead, the 2027 API dates, and how to replace a feed.
How to Estimate Your Reddit API Bill: a Per-Call Cost Model in Python
A per-call Reddit API cost model in Python: price every read, write and DM, then size the monthly bill for a keyword monitor, a RAG refresh and a reply bot.
Reddit API Limitations in 2026: What the API Will Not Do, Beyond Rate Limits
Every Reddit API ceiling that is not a rate limit: the 1,000-item listing cap we measured, search depth, deleted content, access approval and commercial terms.
Subreddit AI-Rule Index 2026: 52.8% of the 250 Most Popular Subreddits Prohibit AI-Generated Posts or Comments
We read the rules of the 250 most popular subreddits. 132, or 52.8%, prohibit AI-generated posts or comments. 27 of the 50 largest do. 9 require disclosure.
Reddit Subscriber Counts Disappeared From Subreddits: How to Read Them From the API, and What 120 Subreddits Say About Whether the Number Ever Meant Anything
Reddit replaced the member count with Visitors and Contributions in September 2025. The data API still returns subscribers. We measured 120 subreddits to test Reddit's reason for the swap, and the data agrees with Reddit.

How to Run the Reddit MCP Server Remotely: Transport, Auth, and What Breaks in Production (2026)
The Reddit MCP server ships stdio only. Here is exactly what changes when you make it network reachable, measured from the published package: the transport, the auth boundary, and the failure modes nobody warns you about.
Reddit Monitoring in 2026: How Alerts Actually Work, What They Miss, and How to Cut the Noise
Reddit has no push, so every Reddit alert is somebody's polling loop. What that means for speed, what monitoring silently misses, and how to make the output usable.