Reddit Archive Search in 2026: How to Find Old Threads After the Archives Closed
How to search the Reddit archive for old threads in 2026: Reddit search, Google, the Wayback Machine, community archives and an API, with our own reach test.
Finding an old Reddit thread got harder this autumn. The copies people relied on outside Reddit are closing one by one, and Reddit's own search leans hard toward recent posts. This guide shows which ways of searching the Reddit archive still work in November 2026, with our own test of how far each one reaches back.
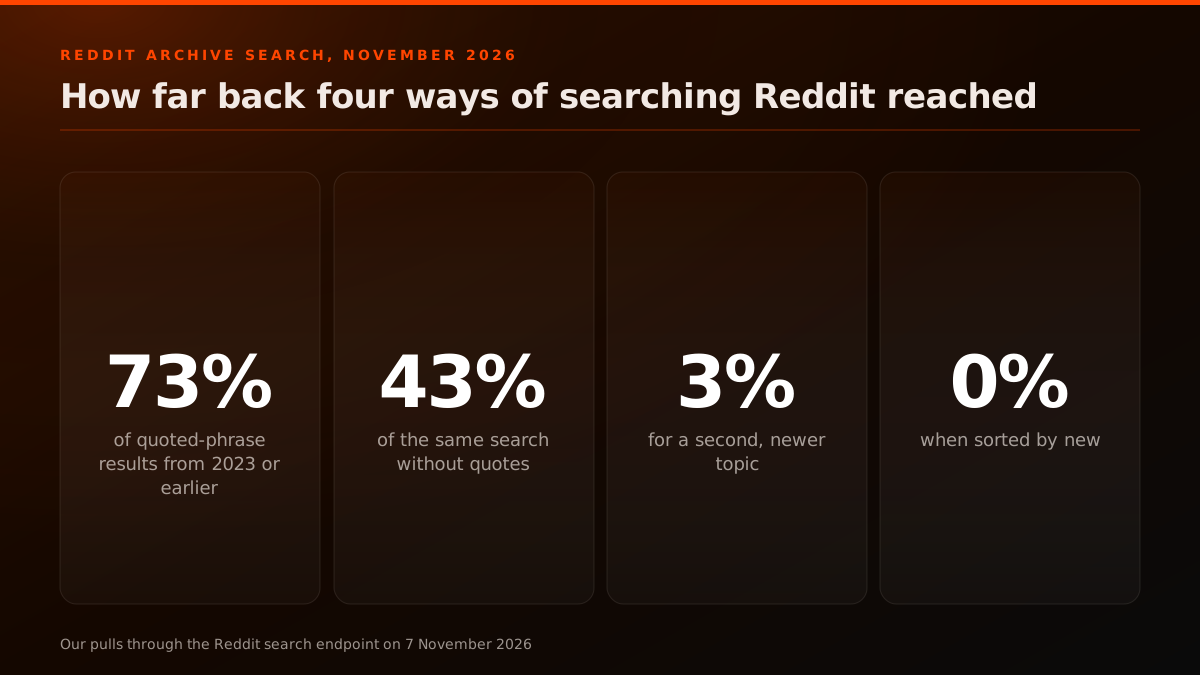
TL;DR: For an old thread, quote the exact phrase in Reddit's search and set the time filter to All time; in our test that returned 73% of results from 2023 or earlier, against 43% without quotes and 0% when sorted by new. Next, try Google with
site:reddit.comandbefore:, then a community archive such as Arctic Shift. Do not count on the Wayback Machine for old.reddit pages any more.
TL;DR
Reddit archive search means finding threads that Reddit's own feeds no longer surface. In 2026 the open copies are shrinking: Reddit limited the Wayback Machine in August 2025, users report old.reddit was excluded from it in November 2026, and Reddit said on 29 October 2026 it will require logins. What still works: Reddit's search with a quoted phrase and the All time filter, Google with site:reddit.com and before: or after:, community archives such as Arctic Shift, and a Reddit data API for repeatable searches. In our 7 November 2026 test, a quoted phrase returned 73% of its results from 2023 or earlier; the same words unquoted returned 43%, and sorting by new returned only November 2026 posts.
This is an independent guide from redditapis.com, a third-party API that is not affiliated with Reddit, Inc. The history of Pushshift and every replacement is in our Pushshift alternatives guide; this post is about the reader's job of finding old threads, whatever tool does it.
What is a Reddit archive search?
A Reddit archive search is any search that finds threads Reddit's live feeds no longer show you: posts from past years, threads in quiet subreddits, or copies of posts that were later edited or removed. It can run on Reddit itself, on Google, on a web archive, on a community archive or through an API.
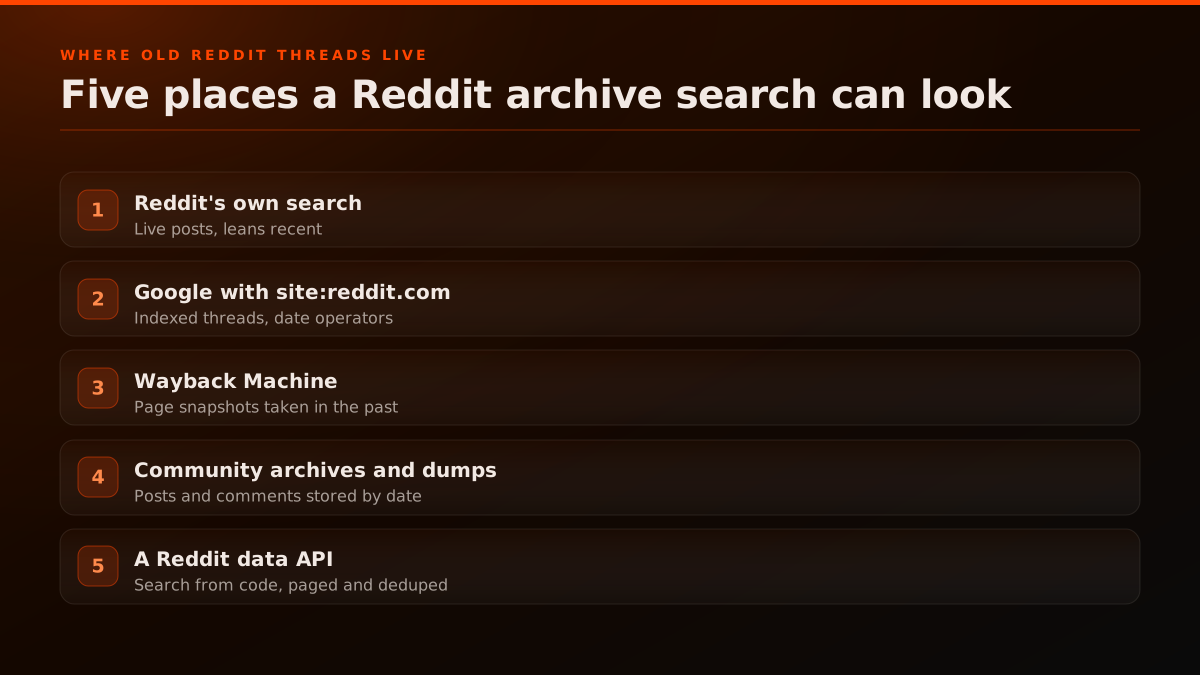
There are five places to look, and each one sees a different slice of the past:
- Reddit's own search, which covers live posts but favours recent ones unless you steer it.
- Google, which indexes many old threads and supports date operators.
- The Wayback Machine and archive.today, which hold page snapshots, including some posts later removed.
- Community archives and data dumps, such as Arctic Shift and PullPush, which store posts and comments by date.
- A Reddit data API, which runs Reddit's search from code so you can page, dedupe and filter by date.
What changed for Reddit archives in 2026?
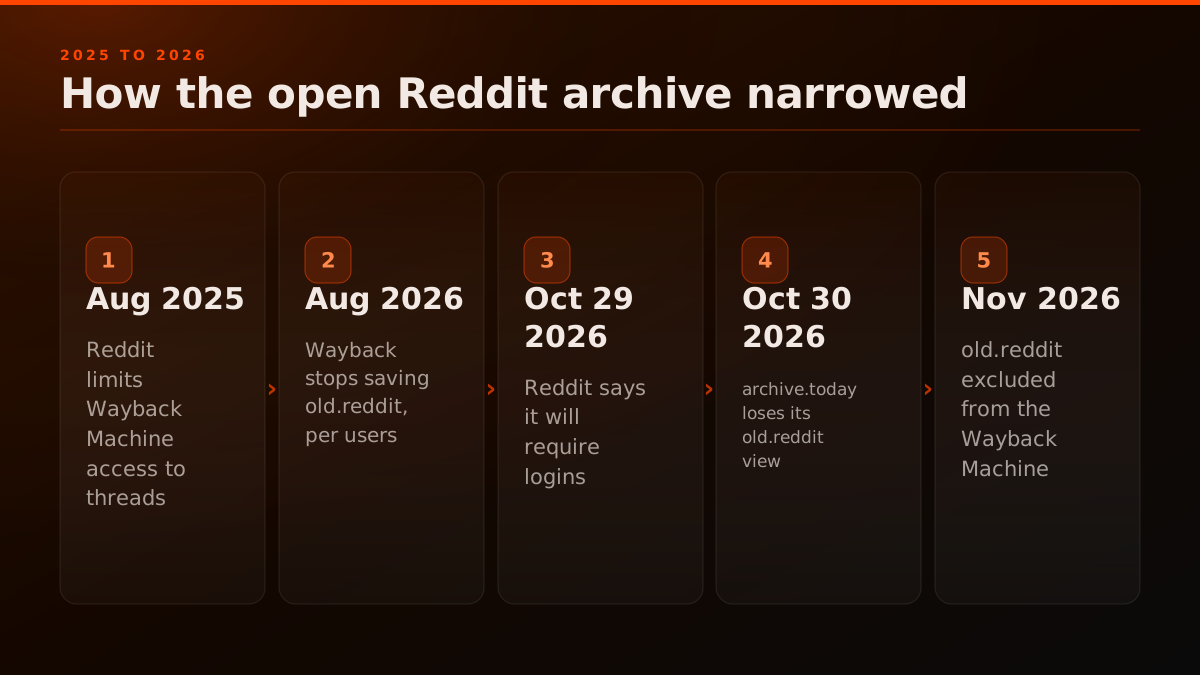
The open copies shrank. Reddit limited the Wayback Machine to its homepage in August 2025, users report archive.today lost its old.reddit view on 30 October 2026, and old.reddit.com was excluded from the Wayback Machine in early November. Reddit also said on 29 October that it will require logins.
Three kinds of change, in short:
- Reddit's own limits: the Wayback Machine restricted to the homepage in 2025, and a login requirement announced in 2026.
- User-reported losses: archive.today and the Wayback Machine no longer capturing or serving old.reddit pages.
- What stays reachable: live Reddit, Google's index, earlier www.reddit.com snapshots and community archives.
The sequence, with Reddit's own statements kept apart from user reports:
How the open Reddit archive narrowed, August 2025 to November 2026
| Date | What happened | Source | Source |
|---|---|---|---|
| Aug 2025 | Reddit limits the Wayback Machine to its homepage | Daily Dot, The Verge | published |
| About 20 Aug 2026 | Wayback stops saving old.reddit threads | User report, r/DataHoarder | unknown |
| 29 Oct 2026 | Reddit says it will require logins | The Verge, Q3 2026 earnings | published |
| 30 Oct 2026 | archive.today loses its old.reddit view | User report, r/DataHoarder | unknown |
| Early Nov 2026 | old.reddit.com excluded from the Wayback Machine | User reports, r/DataHoarder | unknown |
| 7 Nov 2026 | old.reddit snapshot API returns nothing | Our check | measured |
The first step was Reddit's. In August 2025 the Daily Dot reported, following The Verge, that Reddit would let the Wayback Machine index its homepage but no longer save individual threads, citing AI companies that took Reddit data from saved copies.
The next two steps come from users. On 31 October 2026 a poster on r/DataHoarder wrote that archive.today, the last tool still saving old.reddit layouts, now captured only the new site, which shows "only like two posts in a subreddit":
Reddit has killed the final Reddit archive today (Archive Today)?
Around Aug 20 2026, Reddit killed the Wayback Machine, and made Archive Today ignore old reddit - the saving grave was that Archive Today was still treating www reddit as old reddit, so nothing was changed. But now, on…
A week later, a post with 1,230 upvotes reported that old.reddit.com had been excluded from the Wayback Machine:
Years of archived Reddit history have been lost.
old.reddit.com has been excluded from the Wayback Machine
https://web.archive.org/web/20260000000000*/https://old.reddit.com/ Years of archived Reddit history have been lost. This likely happened because Reddit wanted to stop AI companies from scraping archived pages instead…

The same poster noted that old.reddit.com's robots.txt has disallowed everything since at least 2018, and a commenter pointed out that the Internet Archive stopped treating robots.txt as an automatic exclusion in 2017. So the file alone does not explain the change.
What does Reddit's login requirement mean for archive search?
It means fewer public copies and more sign-in prompts. Reddit told The Verge on 29 October 2026 that it will become a logged-in-only experience, tested first in select markets outside the US. Logged-out pages are what web archives capture, so a login wall leaves them less to save and readers more to sign into.
With its Q3 2026 results, Reddit told The Verge that the change is coming, without a full timeline:
This is a big change for Reddit, where we've allowed logged-out access to basically all of Reddit for the last two decades.
What that changes for someone looking for an old thread:
- Web archives: a capture of a logged-out page shows less, as the archive.today report already describes.
- Google results: threads stay indexed, but clicking through may ask for a login where the wall applies.
- Reddit's own search: unaffected for signed-in users, which is why the next section measures it.
The privacy group Reclaim The Net put the archive angle plainly:

Reclaim The Net
@ReclaimTheNetHQ
Reddit is ending logged-out browsing. The company says it needs to stop scrapers, but scrapers can make accounts like anyone else. The shareholder letter is more honest. It says logged-in users provide “more signals for ads targeting” and are the “most monetizable.” Every
How far back does Reddit's own search reach?
Less far than most people assume. In our test on 7 November 2026, a plain-words search sorted by relevance over all time returned 43% of its posts from 2023 or earlier. Quoting the phrase raised that to 73%. A broader, busier topic returned 3%, and sorting by new returned only posts from that week.
We measured it through our own API, three pages per query, counting each post once:
Of the 83 posts Reddit's own search returned for cast iron seasoning, sorted by relevance over all time, 43% were posted in 2023 or earlier.
Our data · Dataset:
reddit-search-relevance-all-time-cast-iron· Source: public Reddit posts, pulled through our API · Query:GET /search?q=cast+iron+seasoning&sort=relevance&t=all&limit=100· Pulled: 2026-11-07 · n = 83 · Method: share of items whose created matches /^20(0|1|2[0-3])/i; frame: 83 unique items from 3 page(s), duplicates removed
Putting the phrase in quotes helped: of the 83 posts returned for the quoted phrase, 73% were posted in 2023 or earlier.
Our data · Dataset:
reddit-search-relevance-all-time-cast-iron-quoted· Source: public Reddit posts, pulled through our API · Query:GET /search?q=%22cast+iron+seasoning%22&sort=relevance&t=all&limit=100· Pulled: 2026-11-07 · n = 83 · Method: share of items whose created matches /^20(0|1|2[0-3])/i; frame: 83 unique items from 3 page(s), duplicates removed
On a second topic the reach was shorter still: of the 95 posts Reddit's search returned for mechanical keyboard recommendation, sorted by relevance over all time, 3% were posted in 2023 or earlier.
Our data · Dataset:
reddit-search-relevance-all-time-mechanical-keyboard· Source: public Reddit posts, pulled through our API · Query:GET /search?q=mechanical+keyboard+recommendation&sort=relevance&t=all&limit=100· Pulled: 2026-11-07 · n = 95 · Method: share of items whose created matches /^20(0|1|2[0-3])/i; frame: 95 unique items from 3 page(s), duplicates removed
Sort the same search by new and the reach collapses: 100% of the 99 posts returned were posted in November 2026.
Our data · Dataset:
reddit-search-newest-all-time-cast-iron· Source: public Reddit posts, pulled through our API · Query:GET /search?q=cast+iron+seasoning&sort=new&t=all&limit=100· Pulled: 2026-11-07 · n = 99 · Method: share of items whose created matches /^2026-11/i; frame: 99 unique items from 3 page(s), duplicates removed
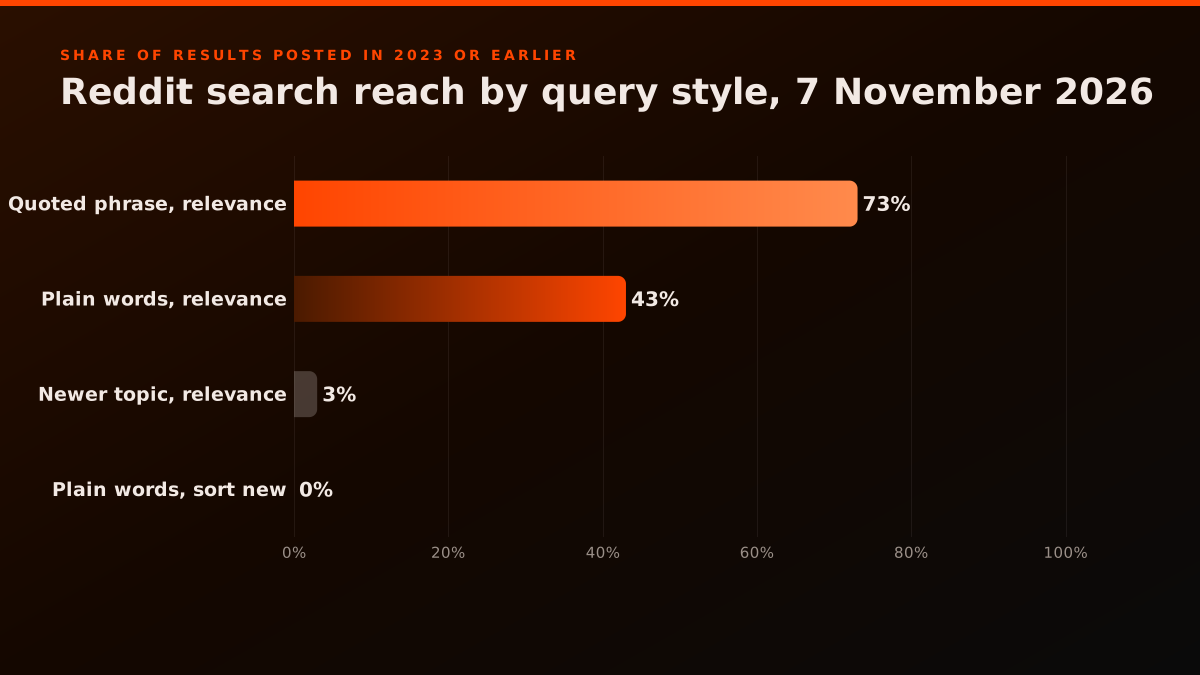
The full results, with the oldest post and the median post date for each query:
How far back Reddit's own search reached, by query style, 7 November 2026
| Query | Sort | Unique posts | From 2023 or earlier | Oldest result | Median post date | Source |
|---|---|---|---|---|---|---|
| "cast iron seasoning" (quoted) | relevance | 83 | 73% | 15 Feb 2010 | 12 Apr 2021 | measured |
| cast iron seasoning | relevance | 83 | 43% | 3 Jun 2013 | 22 Aug 2024 | measured |
| mechanical keyboard recommendation | relevance | 95 | 3% | 31 Mar 2020 | 23 Oct 2026 | measured |
| cast iron seasoning | new | 99 | 0% | 7 Nov 2026 | 7 Nov 2026 | measured |
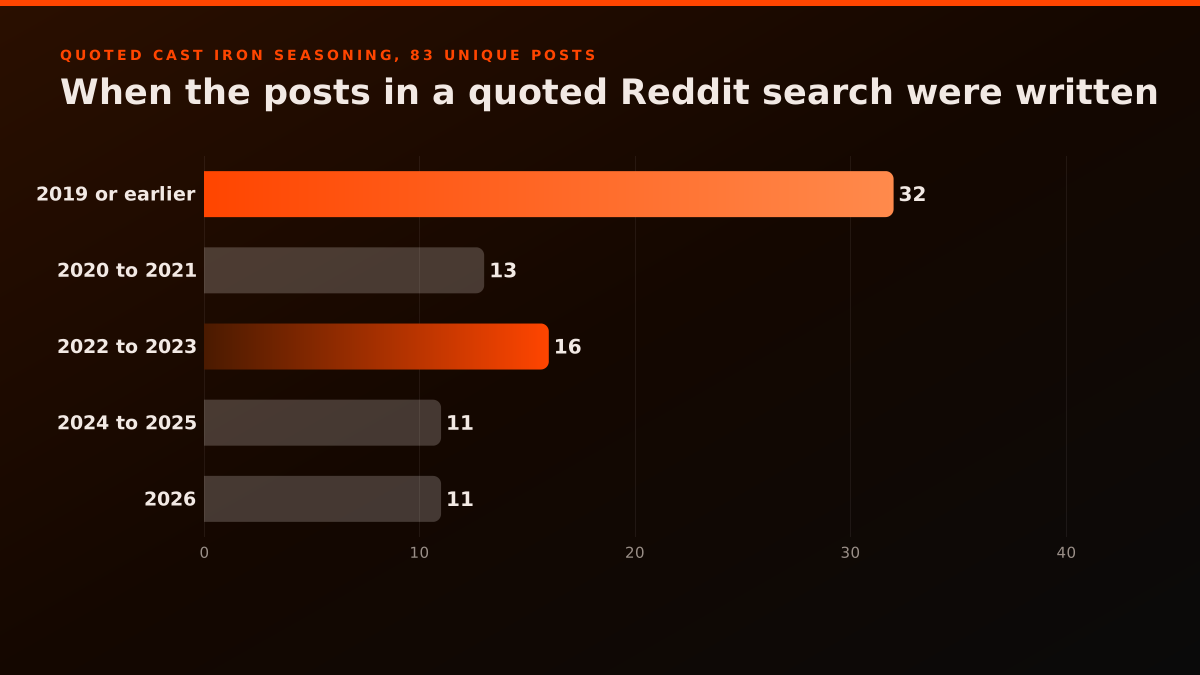
The quoted search is the one that behaves like an archive. Of its 83 unique posts, 32 were from 2019 or earlier, 13 from 2020 to 2021, 16 from 2022 to 2023, 11 from 2024 to 2025 and 11 from 2026. Its median post was from 12 April 2021 and its oldest from 15 February 2010.
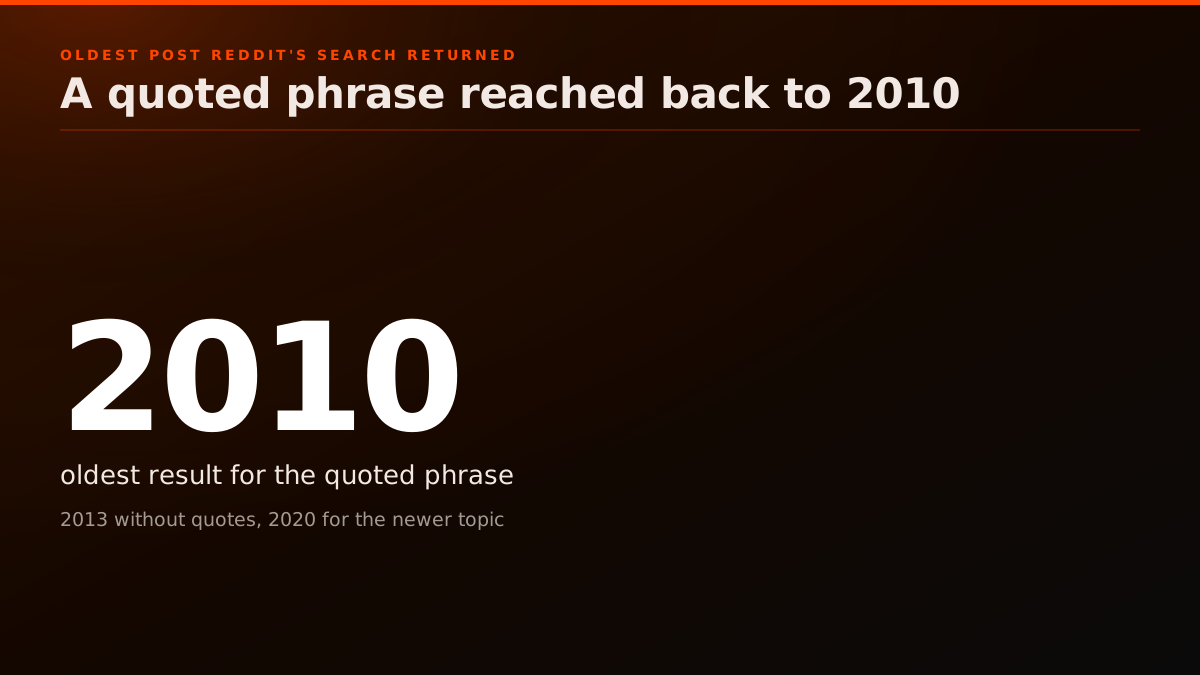
The oldest result is the clearest sign of reach. The quoted search went back to 2010, the unquoted one to 2013, and the newer keyboard topic only to March 2020, with a median post from October 2026.
Sorting by new is the trap. Its 99 posts spanned about 8 hours, from 02
to 10 UTC on 7 November, and many matched only loosely: one was about running out of cat food. Use new to watch a topic, never to dig into its past.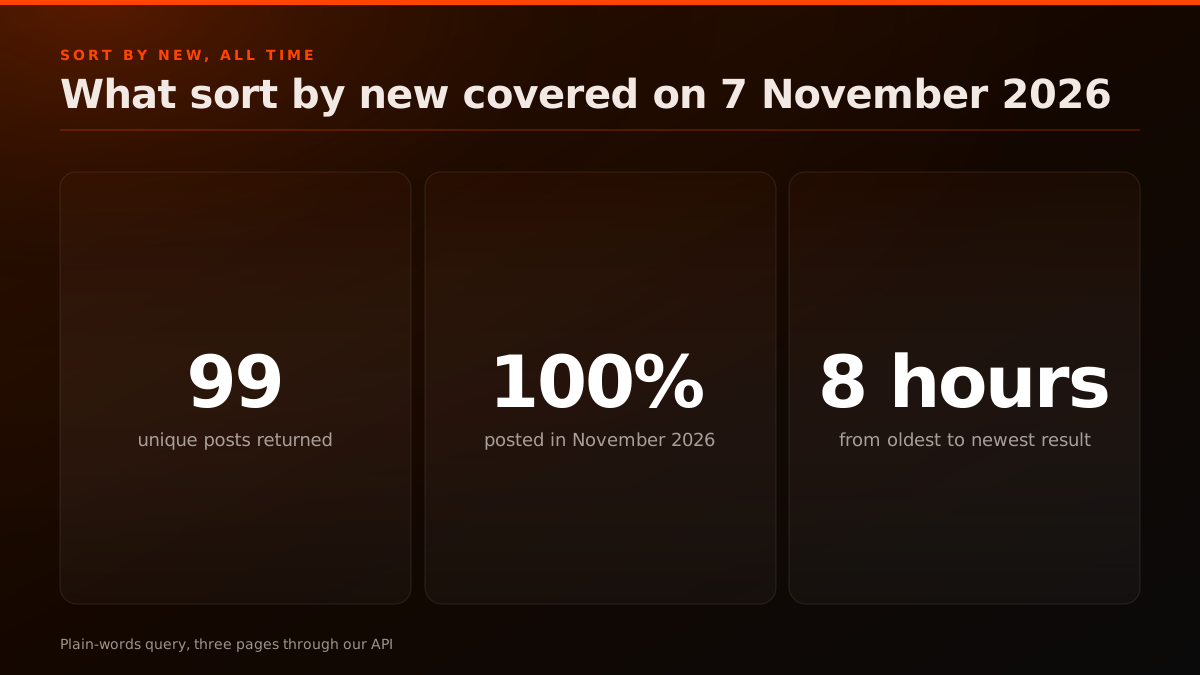
Start building with Redditapis
Reads $0.0015, votes $0.005, writes $0.012, DMs $0.025. $0.50 free credits.
How do you search old Reddit threads with Reddit's search?
Steer it toward the past. Put the exact phrase in quotes, set the time filter to All time, sort by Relevance or Top, and add a subreddit, title or author filter when you know one. Each filter shrinks the pool of loose recent matches that otherwise fills the first pages.
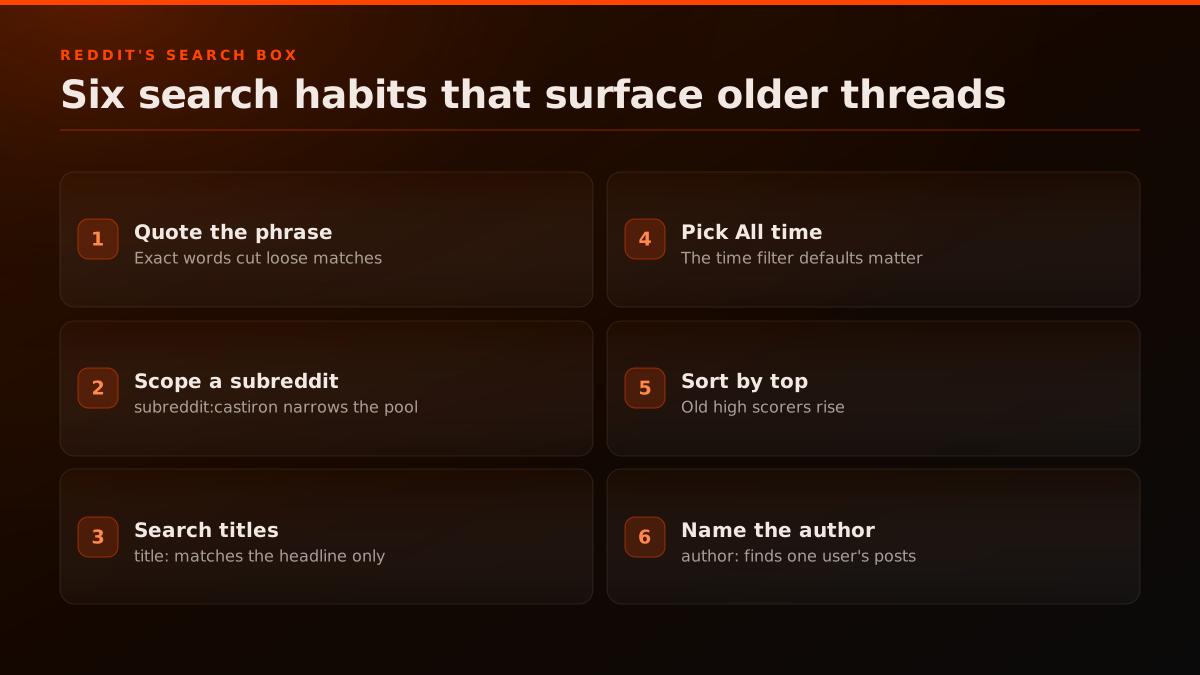
The six habits that made the most difference in our tests and in Reddit's own syntax:
- Quote the phrase:
"cast iron seasoning"matched posts that use those words together, which lifted our pre-2024 share from 43% to 73%. - Scope a subreddit:
subreddit:castiron seasoningremoves every other community's recent chatter. - Search titles:
title:"seasoning"matches the headline only, which is where old how-to threads state their topic. - Set All time: the time filter offers hour, day, week, month, year and all; there is no custom range.
- Sort by Top: old threads with high scores rise above this week's posts.
- Name the author:
author:usernamefinds one account's posts when you remember who wrote it.
The same operators combine, and the boolean operators guide shows which ones Reddit honours. This short video walks through the search filters in Reddit's interface:
Can Google find old Reddit threads?
Often, yes, and Google has the one thing Reddit's search lacks: a custom date range. Combine site:reddit.com with an exact phrase and the before: or after: operators to pull threads from a specific period. Coverage depends on what Google indexed, so a thread with no search traffic may be missing.
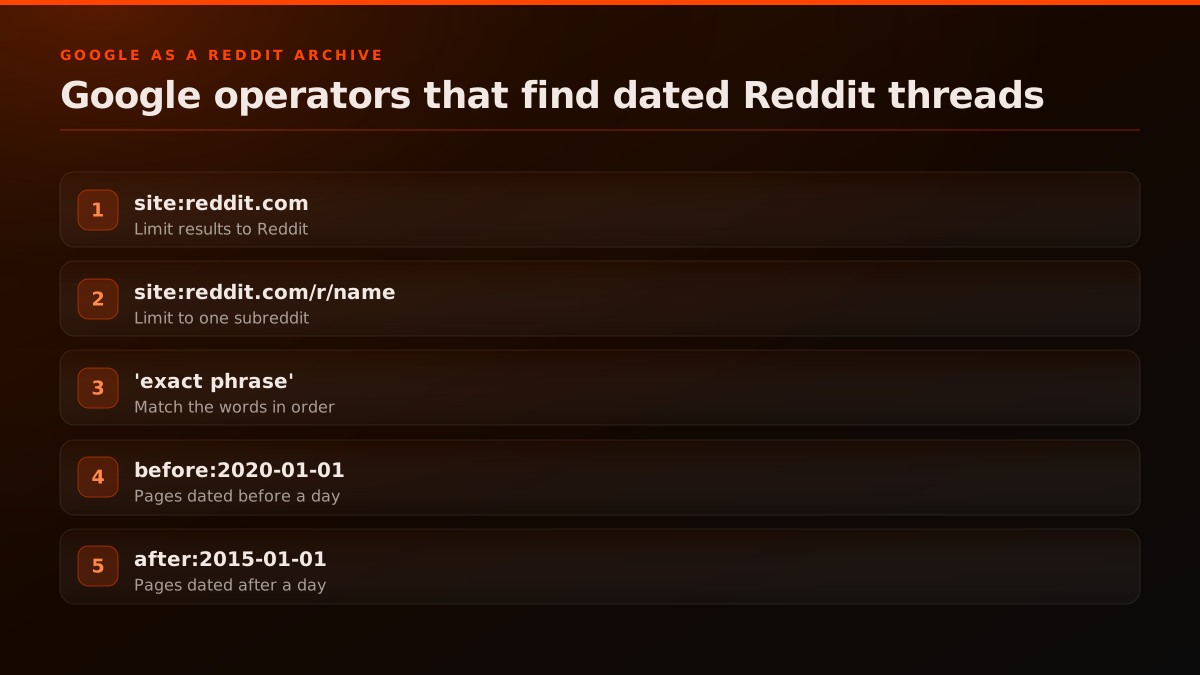
The operators that matter, from Google's own documentation for site:, Google's advanced search help and widely used date filters:
site:reddit.com "cast iron seasoning" before:2020-01-01
site:reddit.com/r/castiron "flaking" after:2015-01-01 before:2018-01-01
site:reddit.comlimits results to Reddit.site:reddit.com/r/namelimits them to one subreddit."exact phrase"keeps the words together.before:andafter:take a date and bound the results by it.
Google's dates are its own estimate of when a page appeared, not Reddit's post time, so check the date on the thread itself. And if Reddit's login wall reaches your country, clicking through may ask you to sign in, as The Verge reported.
Do the Wayback Machine and archive.today still work for Reddit?
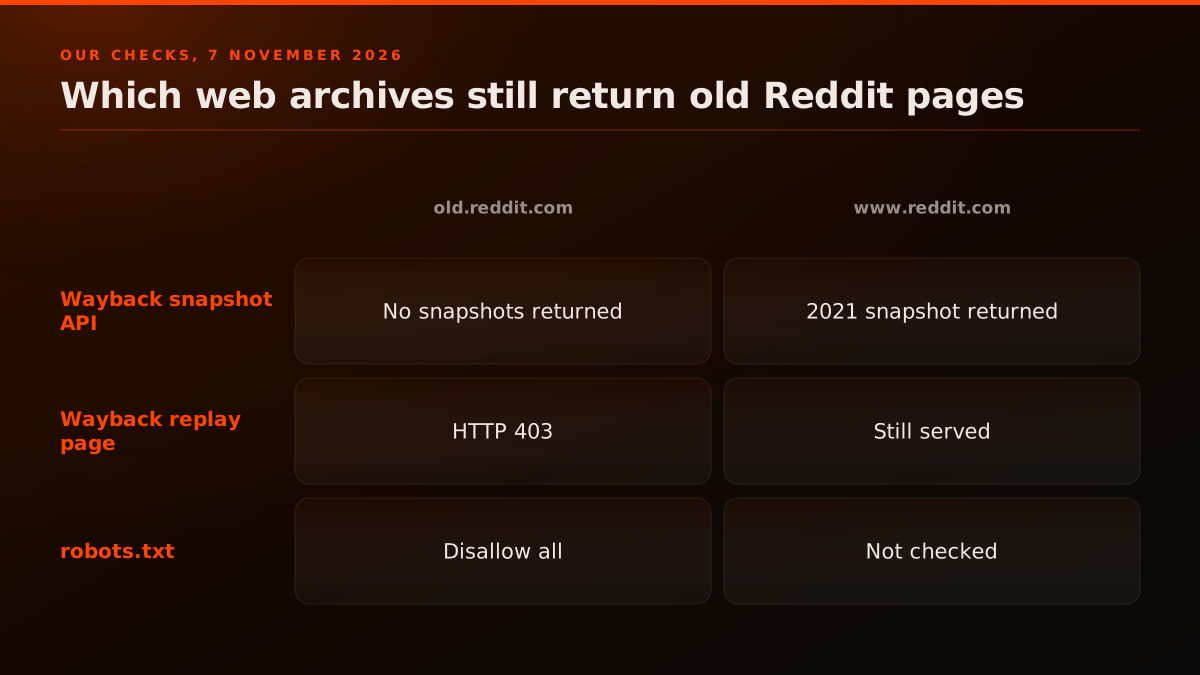
Only for what they already hold, and not for old.reddit pages. When we queried the Wayback Machine's availability API on 7 November 2026, it returned no snapshots for an old.reddit.com subreddit page, and a replay request returned HTTP 403. The same page on www.reddit.com still returned a snapshot from 2021.
What we checked, and what came back:
- Availability API, asking for 2020: no snapshots for old.reddit.com/r/AskReddit; a snapshot of 1 January 2021 for www.reddit.com/r/AskReddit.
- Replay page for the old.reddit URL: HTTP 403.
- old.reddit.com robots.txt: disallows every path for every user agent.
Excluded is not the same as deleted
For a thread you know existed, paste its www.reddit.com URL into the Wayback Machine before trying the old.reddit form. Readers hunting for lost fan fiction have been doing exactly that this week, using Reddit threads to find the old links and the Wayback Machine to open them:
https://x.com/B4tCaves/status/2116506759670157430 For archive.today, the r/DataHoarder report says new captures of Reddit now show the logged-out new site, so a recent capture may hold only a few comments.
Which third-party Reddit archive search tools still work?
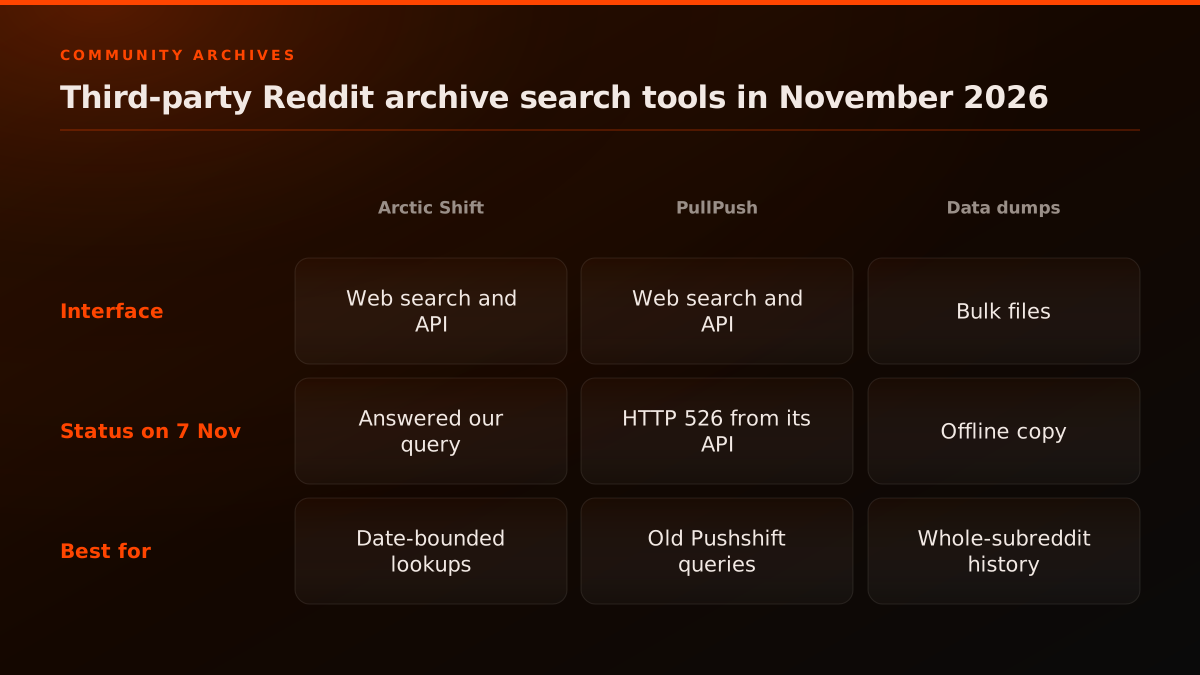
Arctic Shift is the dependable one this week. It answered our query on 7 November 2026 through its API and offers a web search by subreddit, author and date. PullPush, the closest copy of Pushshift's format, returned an HTTP 526 error from its API the same day. Data dumps work offline once downloaded.
How the three community options compare:
Community archives
Arctic Shift, PullPush and data dumps for old Reddit threads
| Arctic Shift | PullPush | Data dumps | |
|---|---|---|---|
| Interface | Web search, API, files | Web search, API | Bulk files |
| Query by date | Yes | Yes | After download |
| Our check, 7 Nov 2026 | Answered | HTTP 526 | Not a live service |
| Best for | Date-bounded lookups | Old Pushshift-style queries | Whole-subreddit history |
- Arctic Shift: a community project serving Reddit posts and comments through dumps, an API and a web search form. Its API asked us to slow down on one broad title query, so keep requests narrow.
- PullPush: keeps Pushshift's endpoints and parameters, which suits old scripts, but it has no service promise and was down for us.
- Data dumps: monthly or per-subreddit files of past posts and comments, often shared through Academic Torrents. Nothing is live, but a downloaded file cannot be switched off.
These are volunteer projects, and Reddit's tightening is aimed at copies of its data, so plan for any of them to change. The deeper comparison, including throughput and coverage, is in our Pushshift alternatives guide and the post on Arctic Shift for AI agents.
The cheapest Reddit API. Try it free.
Reads from $0.0015 per call. $0.50 free credits. No credit card required.
How do you search the Reddit archive with an API?
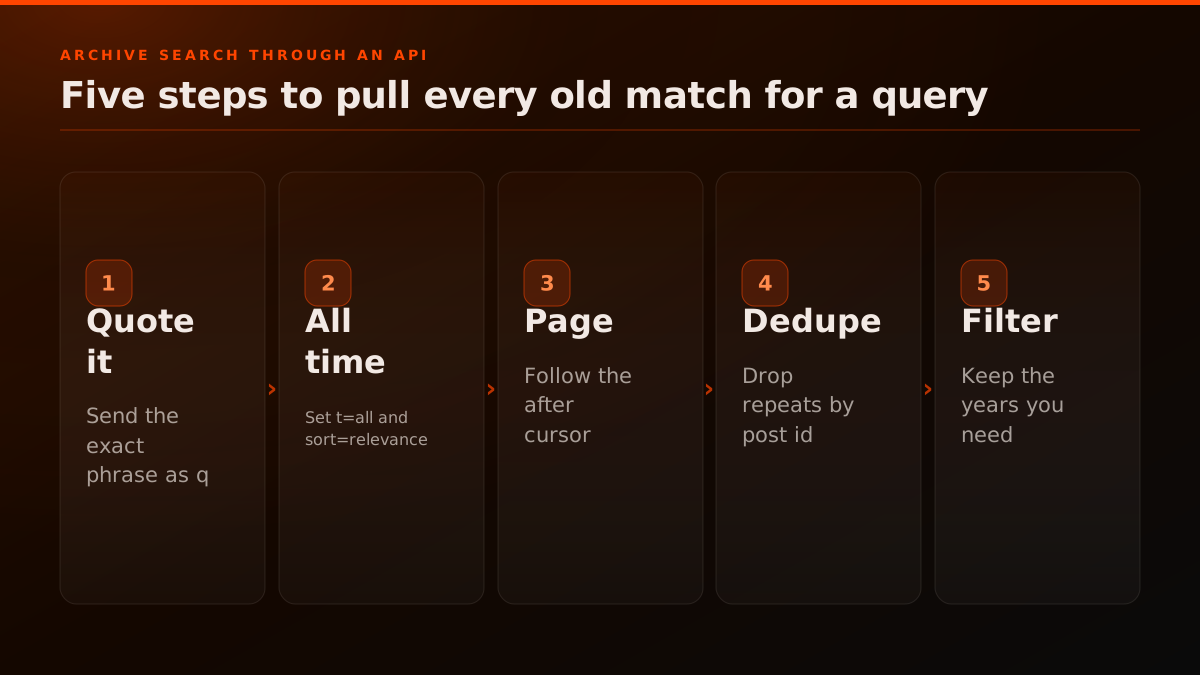
Run Reddit's own search from code with the time filter on all, the phrase in quotes and the sort on relevance, then follow the cursor through every page, drop repeated posts by id and filter on each post's created time. That turns the search box into a repeatable, date-filterable archive query.
The four parameters that turn a search into an archive query:
q: the phrase, in quotes, with anysubreddit:ortitle:filter.t=all: the all-time window, without which old posts never appear.sort=relevance: best match first, which reaches furthest back in our test.after: the cursor from each response, passed back for the next page.
The pattern in Python against our search endpoint:
import requests

API = "https://api.redditapis.com/api/reddit/search"
HEADERS = {"Authorization": "Bearer YOUR_API_KEY"}

def archive_search(phrase, pages=3, before_year=2024):
    seen, rows, after = set(), [], None
    for _ in range(pages):
        params = {"q": f'"{phrase}"', "sort": "relevance", "t": "all", "limit": 100}
        if after:
            params["after"] = after
        data = requests.get(API, headers=HEADERS, params=params, timeout=30).json()
        for post in data["posts"]:
            if post["id"] in seen:
                continue  # Reddit repeats posts across pages
            seen.add(post["id"])
            if int(post["created"][:4]) < before_year:
                rows.append((post["created"][:10], post["subreddit"], post["title"]))
        after = data.get("after")
        if not after:
            break
    return sorted(rows)
What the call returned for our quoted query:
One quoted, all-time Reddit search, 7 November 2026
q
"cast iron seasoning"
unique posts
83
oldest
15 Feb 2010
GET /api/reddit/search with t=all and sort=relevance, three pages, 7 November 2026.
The dedupe step is not optional. Each relevance query returned 105 rows over three pages, and for both cast iron queries only 83 were unique, so 22 rows, about 21%, were repeats of a post already seen:
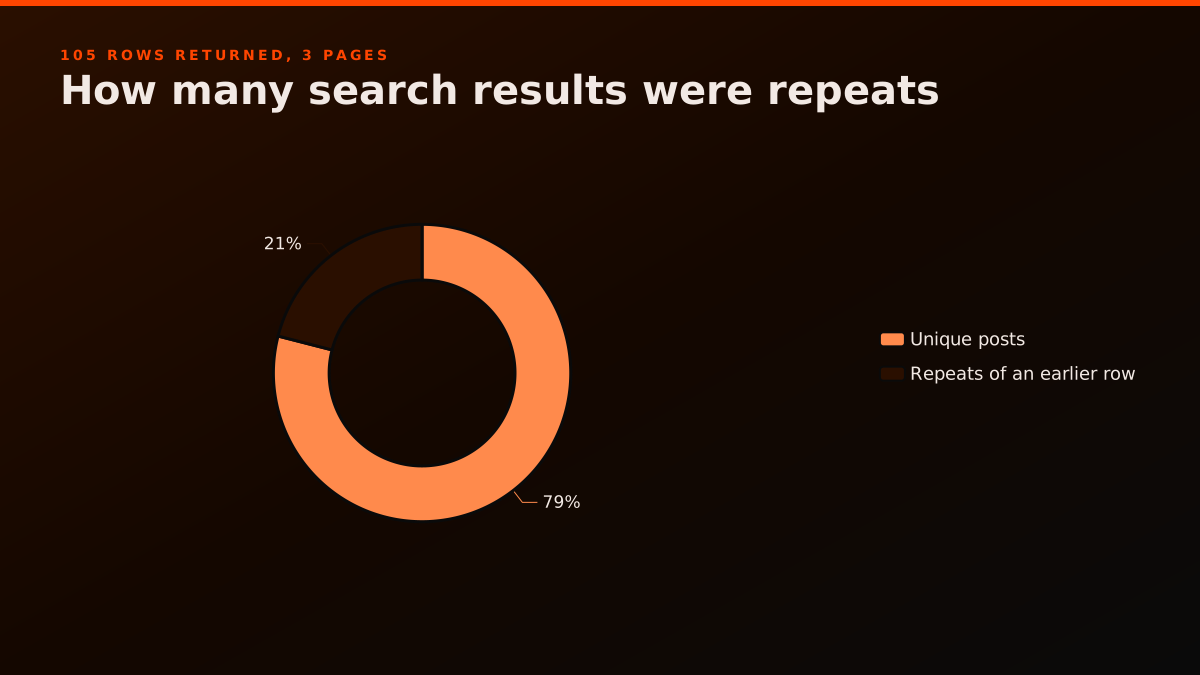
Reddit search repeats itself across pages
The pagination guide explains the cursor, and why a missing cursor does not always mean the list is complete.
How do you find an old Reddit comment instead of a post?
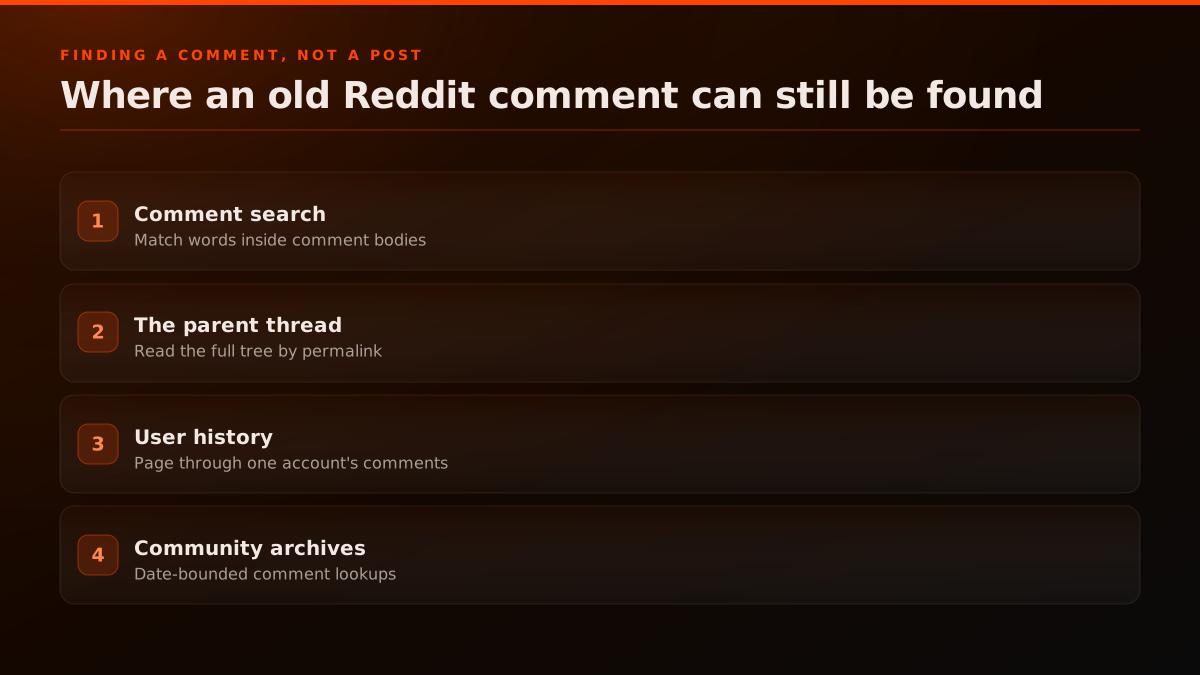
Search for the thread first, then read the comment. Reddit's comment search returns the posts whose comments matched, not the comments themselves. If you know the author, page through their comment history; if you need the comment text across many threads, use a comment search that opens each matching thread for you.
The four routes, from fastest to deepest:
- Comment search: finds threads whose comments contain your words. Our comment search API guide covers the version that returns the comment bodies.
- The parent thread: once you have the post, read its full comment tree by permalink.
- User history: a user's comment listing pages backwards in time, but Reddit stops it at roughly the newest 1,000 items, per our user API guide.
- Community archives: Arctic Shift and PullPush index comments by date, which reaches past that 1,000-item limit.
Which Reddit archive search method should you use?
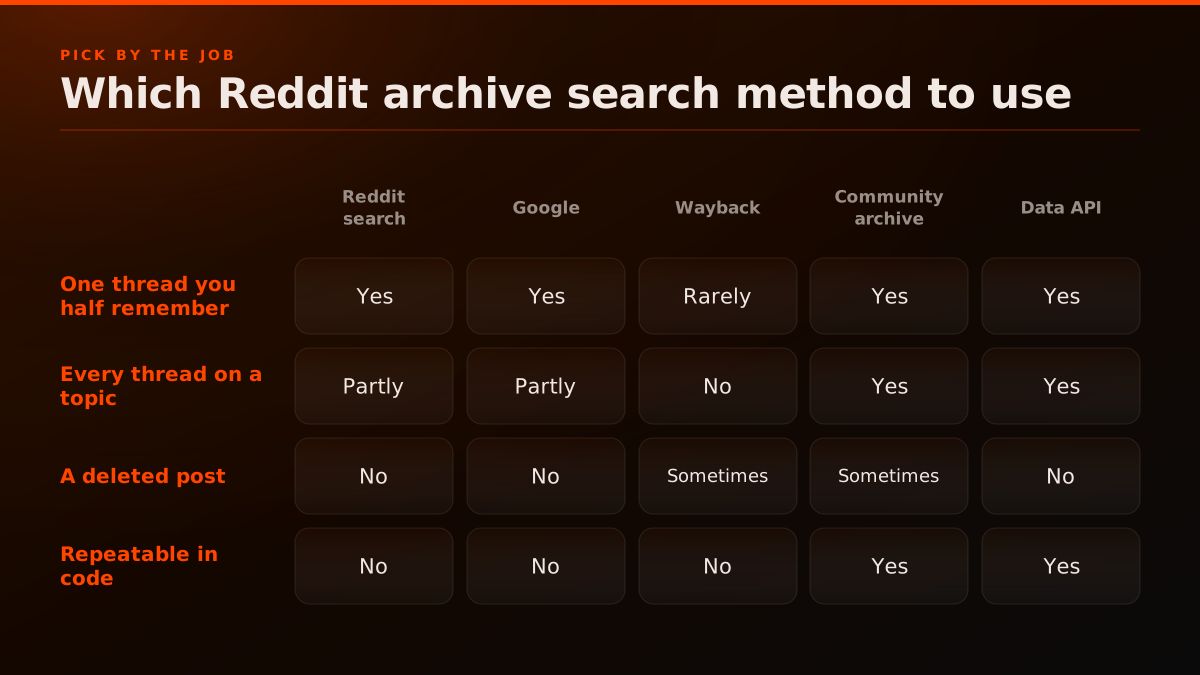
Pick by the job. For one thread you half remember, Reddit's search with quotes or Google with a date range is quickest. For every thread on a topic, use an API or a community archive. For a deleted post, only a snapshot taken before removal can help, so try the Wayback Machine and community archives.
Side by side:
Archive by archive
Which Reddit archive search methods still work in November 2026
| Reddit data API | Reddit search | Wayback Machine | Community archives | ||
|---|---|---|---|---|---|
| Reaches pre-2024 threads | Yes, with t=all | Yes, with quotes | Yes | Older snapshots only | Yes |
| Custom date range | Filter on created | No | before: and after: | By snapshot date | Yes |
| Deleted posts | No | No | No | If captured | If captured |
| Repeatable in code | Yes | No | No | Partly | Yes |
| Status, 7 Nov 2026 | Working | Working | Working | old.reddit excluded | Mixed |
| Job | First try | Then |
|---|---|---|
| One thread you half remember | Reddit search, quoted, All time | Google with site.com |
| Threads from a date range | Google with before: and after: | Arctic Shift by date |
| Every thread on a topic | A Reddit data API, paged and deduped | A data dump |
| A deleted post | Wayback Machine with the www URL | Community archives |
Teams that need the live side of Reddit next to the past, such as new posts on a topic as they appear, can see the build options in our guide to collecting Reddit data and the Pushshift alternative page.
What should you save before more of the Reddit archive closes?
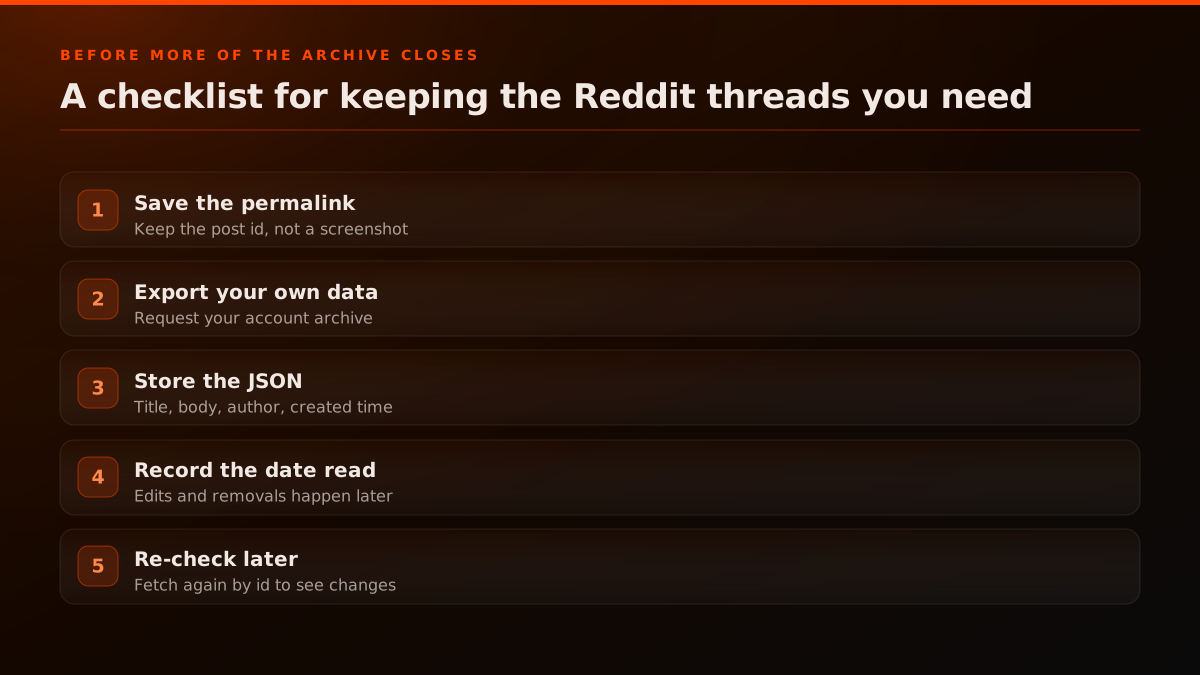
Save the threads you depend on now, as data rather than screenshots. Keep each post's permalink and id, its title, body, author and created time, and the date you read it. With the Wayback Machine and archive.today losing access, your own copy may become the only one you can open.
A short checklist:
- Save the permalink and id, so you can fetch the same post again later.
- Request your own data from Reddit's account settings if the threads are yours.
- Store the JSON, not a picture: title, body, author, subreddit and created time.
- Record when you read it, because edits and removals happen after the fact.
- Re-check later by id, to see whether the post was edited or removed.
Why a stored copy beats a re-read is covered in our comparison of live datasets and static dumps, and other access changes landing this month are in the RSS end date post.
Where these numbers come from.
Each row is a figure in this post and the artefact it was read from. Reddit's access rules and the third-party archives around them keep moving, so check the date on a source before you build against it.
- r/DataHoarder: old.reddit.com has been excluded from the Wayback Machine (7 November 2026)
- User report with 1,230 upvotes on 7 November 2026, linking the Wayback exclusion to Reddit's limits on archives.
- r/DataHoarder: Reddit has killed the final Reddit archive today (31 October 2026)
- User report that archive.today lost its old.reddit view on 30 October 2026.
- The Verge: Reddit will force everyone to log in (29 October 2026)
- Reddit's Q3 2026 announcement that it will become a logged-in-only experience, starting with tests outside the US.
- Daily Dot: Reddit to block the Internet Archive from indexing the site (14 August 2025)
- Report that Reddit would limit the Wayback Machine to its homepage rather than individual threads.
- Internet Archive blog: robots.txt meant for search engines don't work well for web archives (2017)
- The Wayback Machine's 2017 change to stop treating robots.txt as an automatic exclusion.
- old.reddit.com robots.txt
- Disallows all user agents from every path, as read on 7 November 2026.
- Google Search Central: the site: operator
- Google's documentation for limiting results to one site.
- Arctic Shift on GitHub
- The community project that serves Reddit data through dumps, an API and a web interface.
- Arctic Shift web search
- Search form for posts and comments by subreddit, author and date.
- Internet Archive Wayback Machine
- The archive and its availability API used in our 7 November 2026 check.
Frequently asked questions.
Start with Reddit's own search, with the phrase in quotes, the time filter on All time and the sort on Relevance or Top. In our 7 November 2026 test, quoting the phrase raised the share of results from 2023 or earlier from 43% to 73%. If that fails, use Google with site:reddit.com plus before: or after:, then a community archive such as Arctic Shift. For repeatable searches in code, use the Reddit search API.
Only partly. Reddit began limiting the Internet Archive's access to individual threads in August 2025, according to The Verge and the Daily Dot. When we checked on 7 November 2026, the Wayback availability API returned no snapshots for an old.reddit.com subreddit page and a replay request returned HTTP 403, while the same page on www.reddit.com still returned a 2021 snapshot. Treat it as a fallback, and see our Pushshift alternatives for other archives.
Because Reddit's search favours recent posts unless you steer it. Sorting by new returns only the latest posts: in our test all 99 results were from November 2026 and spanned about 8 hours. Relevance with All time reaches further, but a broad topic can still return mostly new posts; our second topic had 3% of results from 2023 or earlier. Quote the exact phrase, scope a subreddit, and search titles. The boolean operators guide lists the syntax.
Reddit's search box only offers fixed windows: hour, day, week, month, year and all time. It has no custom date range. For a specific range, use Google with site:reddit.com and the before: and after: operators, or a community archive that takes date bounds, such as Arctic Shift. With an API, request t=all, page through every result and filter on each post's created timestamp yourself, as our pagination guide shows.
Users on r/DataHoarder report that archive.today lost its old.reddit view on 30 October 2026 and that old.reddit.com was excluded from the Wayback Machine in early November 2026. Reddit has publicly said only that it limited the Internet Archive in 2025 and that it will move to a logged-in-only experience. Snapshots taken before the exclusion are not reported as deleted, only inaccessible. Our RSS end date post covers the other access change this month.
Not for the public. Pushshift has been limited to Reddit moderators since 2023. The community replacements are PullPush, which keeps Pushshift's query format, and Arctic Shift, which offers a web search, an API and bulk files. When we checked on 7 November 2026, Arctic Shift answered our query and PullPush's API returned an HTTP 526 error. Our Pushshift alternatives guide compares them in depth.
Reddit's own comment search returns the posts whose comments matched, not the comments. To get the comment text, open each matching thread, read a user's comment history if you know the author, or use a comment search that returns the bodies. Reddit stops a user's history listing at roughly the newest 1,000 items, so very old comments from active accounts need an archive. Our comment search API guide covers the options.
Reddit's own search does not return removed or deleted posts. Copies sometimes survive in the Wayback Machine, archive.today or community archives that captured the post before it was removed, but coverage is patchy and those archives are narrowing in 2026. One r/Hacking_Tutorials poster who said they had archived Reddit for a year put the share of those posts later deleted at about 30%. Save what you need now, with the post id, as the static dump comparison explains.
Keep reading.
Continue exploring related pages.
Reddit API documentation
The complete 2026 reference: auth, all 76 endpoints, and code.
Get a Reddit API key
Instant bearer token, no waitlist and no enterprise contract.
Reddit Responsible Builder Policy
Why Reddit denies API applications, and the managed REST bypass.
Reddit API use cases
14 use cases from AI training to brand monitoring and DMs.
Reddit Search API
Search posts, comments, users, and communities over one REST endpoint.
Reddit MCP server
Wrap the REST API as MCP tools for Claude, Cursor, and any MCP client.
Reddit MCP hub
Install tabs for every client, the full tool table, pricing and fixes.
Reddit API for AI agents
Live Reddit context for tool calls, MCP servers, and RAG pipelines.
Redditapis pricing
Endpoint-level costs and quick monthly totals - reads from $0.0015 / call.
Reddit API cost calculator
Estimate monthly spend using your request volume.
Reddit API guides and tutorials
Tutorials, walkthroughs, and API deep-dives for developers.
Reddit API alternatives
Evaluate alternatives by cost model, limits, and integration fit.
Cheap Reddit API
The cheapest way to get Reddit data: $0.0015 per call, no contract, no minimum.
Official Reddit API vs Redditapis
Access, setup, rate limits, and pricing, side by side.
PRAW alternative
A hosted Reddit REST API for any language, no app registration or OAuth.
Reddapi alternative
A maintained Reddit REST API with published pricing and write endpoints.
Reddit comment scraper alternative
The raw comment API: search and filter comments, historical and live, clean JSON.
Reddit scraper API
Hosted scraper API vs building your own: no proxies to manage, clean JSON.
RapidAPI Reddit alternative
A direct, maintained Reddit API with published pricing and write endpoints.
Bright Data Reddit alternative
A purpose-built Reddit API vs a general scraping platform: structured JSON, plus writes.
ScraperAPI Reddit alternative
A Reddit-native API vs a generic HTML fetcher: auth and pagination handled, typed JSON.
TikHub alternative
TikHub's Reddit surface is read-only; get comment, vote, and DM endpoints too.
EnsembleData alternative
No $100/month floor: pay per call from $0.0015, plus write, vote, and DM endpoints.
Scrape Creators alternative
7 read-only Reddit endpoints vs a dedicated API with real write, vote, and DM paths.
FetchLayer alternative
Posts, comments, and search only; add vote, comment, and DM over the same REST auth.
PullPush alternative
PullPush is free but volunteer-run and goes offline for reindexing; a maintained REST API that stays up.
Reddit monitoring API
Build your own keyword and brand-mention monitor: search, comment search, and subreddit streams over REST.
F5Bot vs Redditapis
F5Bot's Slack and Discord delivery needs its $49.99/mo Gold tier; Redditapis includes it from $19/mo.
Syften vs Redditapis
Syften caps you at 100 to 500 results a day; Redditapis allows 10,000 a day per monitor at the entry plan.
Octolens vs Redditapis
Octolens meters by mention with overage fees; Redditapis is flat-priced by subreddit slot from $19/mo.
Affiliate program
Earn 20% lifetime commissions - capped at $5,000/yr.
Reddit Vote API tutorial
Upvote and downvote a post programmatically via the REST API.
Reddit Data API: REST, no PRAW
REST endpoints for Reddit data with no PRAW and no OAuth dance.
Reddit scraping benchmarks
Real throughput, error rates, and cost benchmarks for Reddit scraping.
Reddit API answers
Direct answers on cost, access, rate limits, endpoints, and auth.
How much the Reddit API costs
Per-call pricing from $0.0015 a read, with $0.50 in free credits.
Reddit API in Python
One requests call with a bearer token, no PRAW and no OAuth flow.
Reddit shadowban checker
Check if a Reddit account is shadowbanned in seconds, free and no login.
Subreddit stats checker
See any subreddit's live subscriber count, active users, and age, free and no login.
Similar reads.
More guides on the Reddit API, scraping, pricing, and MCP servers.
Reddit AI Agents Need Live Data: Why an Archive Like Arctic Shift Isn't Enough
An AI agent that reads Reddit needs current state, not a snapshot. What a free archive like Arctic Shift covers, where it breaks for live agent tool calls, and when you need a live API.
What Sources Does ChatGPT Use? Reddit's Share of AI Citations, Measured (2026)
What sources does ChatGPT use in 2026? Wikipedia, brand sites and reviews lead, and Reddit fell from 3.83% to 0.52% of citations. Data and our 20-prompt test.
Reddit's .json Endpoint Is Dead in 2026: Every Way to Still Pull Reddit Data
The old reddit.com/....json scraping trick is rate-limited and blocked in 2026. Here is every current way to still pull Reddit data, the official Data API, your own OAuth app, PullPush and Arctic Shift for history, a managed REST API, data dumps, and headless scraping, with the tradeoffs.
Apify Reddit Scraper Deprecated: Why Actors Broke in 2026 and How to Migrate
The most used Apify Reddit actor is now marked Deprecated. Why Reddit actors broke in 2026, what changes on November 13, and how to migrate a job.
Reddit Lead Generation in 2026: Find Buying-Intent Threads Through an API
Reddit lead generation that holds up: find the threads where buyers ask for a tool, monitor them through an API, and answer in public. Measured on 2026 data.
Reddit Comment IDs Are Now 13 Characters and Out of Order: What Breaks in Your Code
Reddit's new comment IDs are 13 characters and no longer increasing. When the change went live, what it breaks in your code, and the fix for each case.
Reddit Closed New Data API Requests on October 31: What to Do If You Never Applied
Reddit stopped accepting new Data API requests on October 31, 2026. What closed, why the request form kept failing, and how a new project reads Reddit now.
Reddit Data for Market Research After ChatGPT's Citation Drop (2026)
ChatGPT now cites Reddit about 88% less than six months ago. Here is what Reddit data is still worth pulling, and how to mine it through an API.